---
title: "Living WWII Veterans by State (2025)"
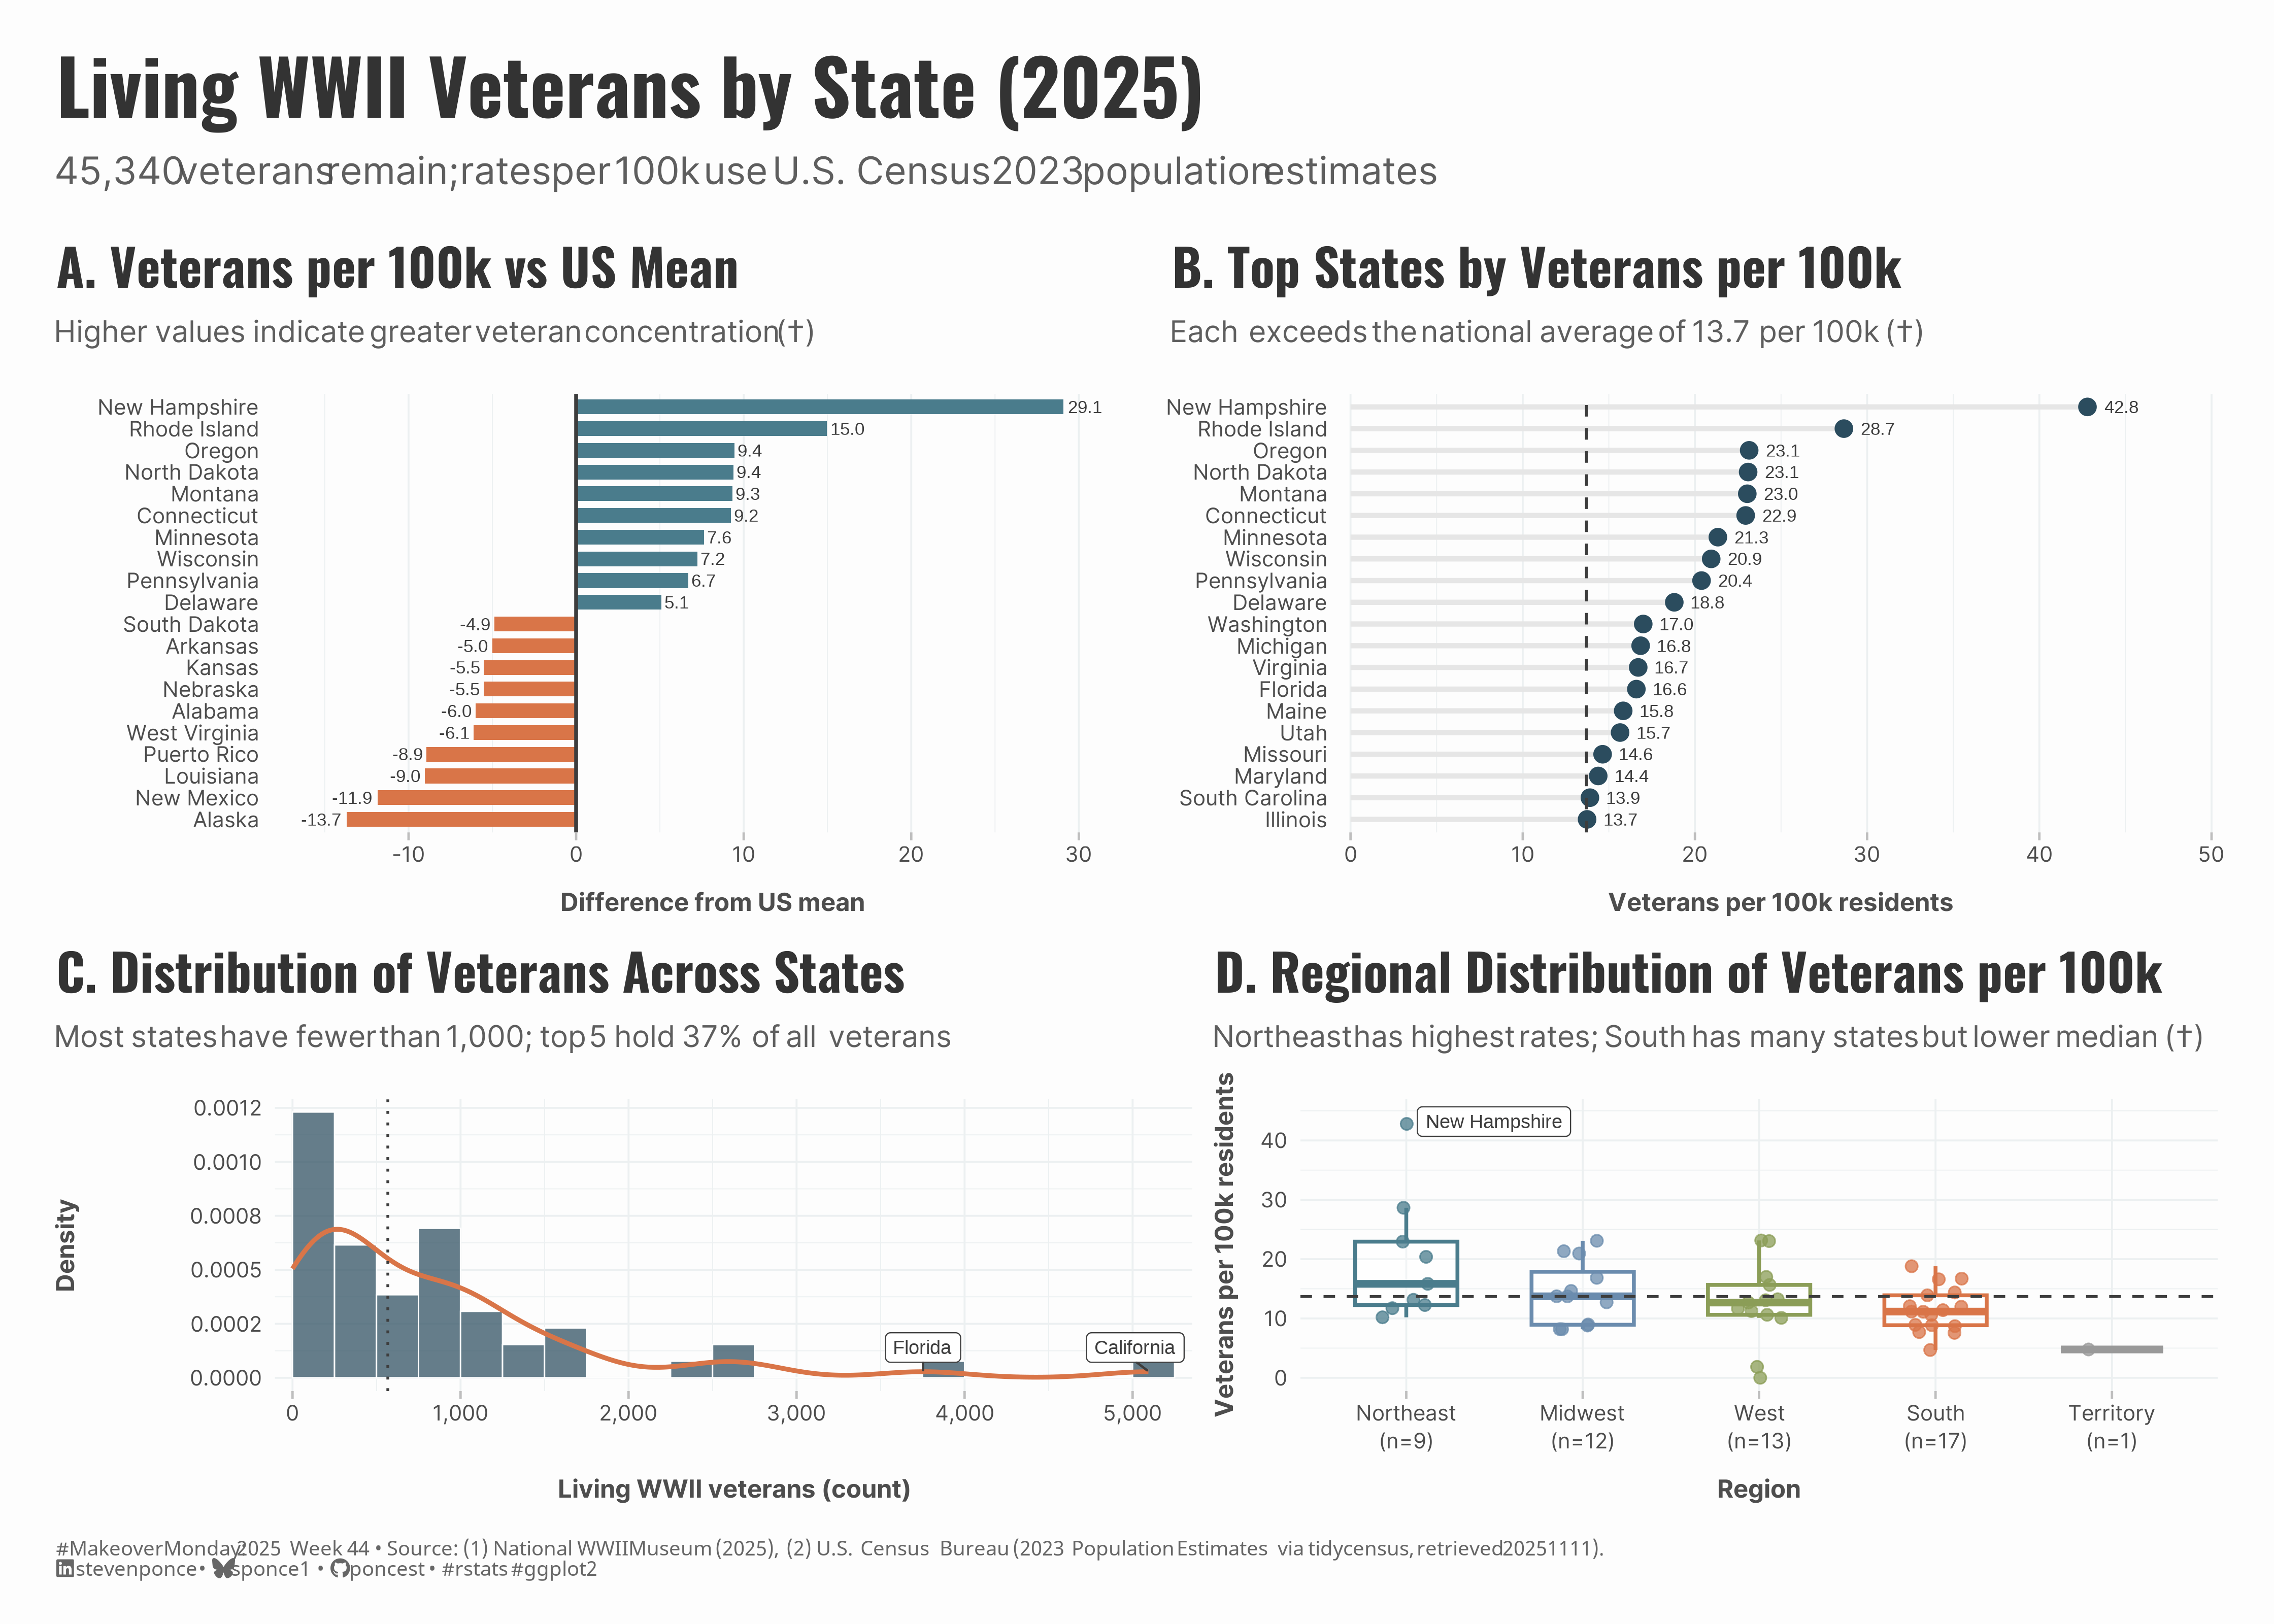
subtitle: "45,340 veterans remain; rates per 100k use U.S. Census 2023 population estimates"
description: "Multi-panel analysis of 45,340 living WWII veterans by state, comparing raw counts vs population-adjusted rates. New Hampshire leads per capita (42.8 per 100k) while five states hold 37% of all veterans. "
date: "2025-11-11"
categories: ["MakeoverMonday", "2025"]
tags: [
"makeover-monday",
"data-visualization",
"ggplot2",
"patchwork",
"veterans",
"wwii",
"demographic-analysis",
"population-normalization",
"diverging-bar-chart",
"lollipop-chart",
"distribution-analysis",
"box-plot",
"tidycensus",
"us-census"
]
image: "thumbnails/mm_2025_44.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
```{r}
#| label: setup-links
#| include: false
# CENTRALIZED LINK MANAGEMENT
## Project-specific info
current_year <- 2025
current_week <- 44
project_file <- "mm_2025_44.qmd"
project_image <- "mm_2025_44.png"
## Data Sources
data_main <- "https://data.world/makeovermonday/week-44-2025-wwii-veteran-statistics"
data_secondary <- "https://data.world/makeovermonday/week-44-2025-wwii-veteran-statistics"
## Repository Links
repo_main <- "https://github.com/poncest/personal-website/"
repo_file <- paste0("https://github.com/poncest/personal-website/blob/master/data_visualizations/MakeoverMonday/", current_year, "/", project_file)
## External Resources/Images
chart_original <- "https://raw.githubusercontent.com/poncest/MakeoverMonday/refs/heads/master/2025/Week_44/original_chart.png"
## Organization/Platform Links
org_primary <- "https://www.nationalww2museum.org/war/wwii-veteran-statistics"
org_secondary <- "https://www.nationalww2museum.org/war/wwii-veteran-statistics"
# Helper function to create markdown links
create_link <- function(text, url) {
paste0("[", text, "](", url, ")")
}
# Helper function for citation-style links
create_citation_link <- function(text, url, title = NULL) {
if (is.null(title)) {
paste0("[", text, "](", url, ")")
} else {
paste0("[", text, "](", url, ' "', title, '")')
}
}
```
### Original
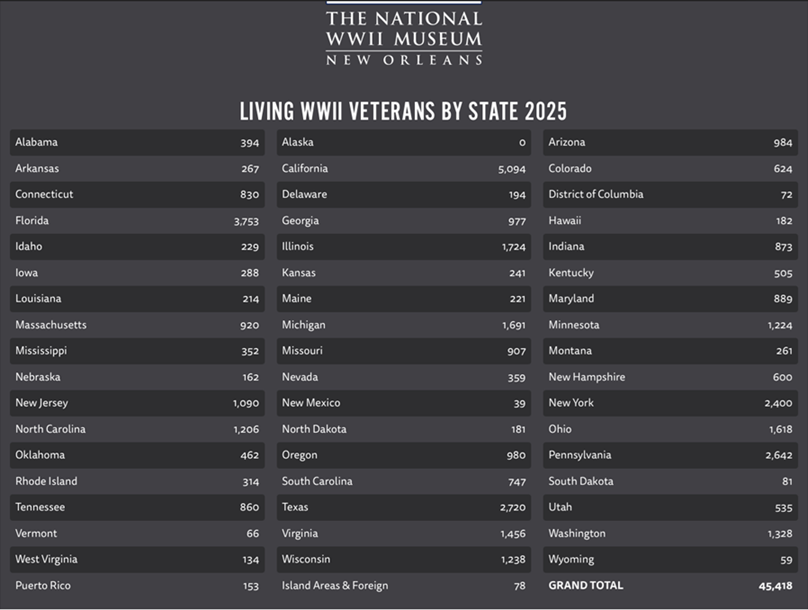
The original visualization comes from `r create_link("National WWII Museum. (2025). WWII Veteran Statistics", data_secondary)`
<!--  -->
### Makeover
{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
  if (!require("pacman")) install.packages("pacman")
  pacman::p_load(
    tidyverse,   # Easily Install and Load the 'Tidyverse'
    janitor,     # Simple Tools for Examining and Cleaning Dirty Data
    skimr,       # Compact and Flexible Summaries of Data
    scales,      # Scale Functions for Visualization
    ggtext,      # Improved Text Rendering Support for 'ggplot2'
    showtext,    # Using Fonts More Easily in R Graphs
    glue,        # Interpreted String Literals
    patchwork,   # The Composer of Plots
    ggrepel,     # Automatically Position Non-Overlapping Text Labels
    tidycensus   # Load US Census Boundary and Attribute Data
  )
})

### |- figure size ----
camcorder::gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  = 14,
    height = 10,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
#|

ww2_veterans_raw <- read_csv(
  here::here("data/MakeoverMonday/2025/Living_WWII_Veterans_by_State_2025.csv")) |>
  clean_names()

### |-  Get state population data from US Census Bureau ----
# Source: US Census Bureau, Population Division
# Annual Estimates of the Resident Population: July 1, 2023
# Retrieved via tidycensus package
state_pop_census <- get_estimates(
  geography = "state",
  product = "population",
  vintage = 2023,
  year = 2023
  ) |>
  filter(variable == "POPESTIMATE") |>
  select(NAME, value) |>
  rename(state = NAME, population_2023 = value)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(ww2_veterans_raw)
skim_without_charts(ww2_veterans_raw) |> summary()
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

ww2_veterans_clean <- ww2_veterans_raw |>
  filter(state != "Island Areas & Foreign") |>
  left_join(state_pop_census, by = "state") |>
  mutate(
    veterans_per_100k = if_else(!is.na(population_2023),
      1e5 * living_wwii_veterans_2025 / population_2023,
      NA_real_
    ),
    region = case_when(
      state %in% c(
        "Connecticut", "Maine", "Massachusetts", "New Hampshire", "Rhode Island",
        "Vermont", "New Jersey", "New York", "Pennsylvania"
      ) ~ "Northeast",
      state %in% c(
        "Illinois", "Indiana", "Iowa", "Kansas", "Michigan", "Minnesota", "Missouri",
        "Nebraska", "North Dakota", "Ohio", "South Dakota", "Wisconsin"
      ) ~ "Midwest",
      state %in% c(
        "Alabama", "Arkansas", "Delaware", "District of Columbia", "Florida", "Georgia",
        "Kentucky", "Louisiana", "Maryland", "Mississippi", "North Carolina", "Oklahoma",
        "South Carolina", "Tennessee", "Texas", "Virginia", "West Virginia"
      ) ~ "South",
      state %in% c(
        "Alaska", "Arizona", "California", "Colorado", "Hawaii", "Idaho", "Montana",
        "Nevada", "New Mexico", "Oregon", "Utah", "Washington", "Wyoming"
      ) ~ "West",
      state == "Puerto Rico" ~ "Territory",
      TRUE ~ "Other"
    )
  )

summary_stats <- ww2_veterans_clean |>
  summarise(
    total_veterans   = sum(living_wwii_veterans_2025, na.rm = TRUE),
    mean_per_state   = mean(living_wwii_veterans_2025, na.rm = TRUE),
    median_per_state = median(living_wwii_veterans_2025, na.rm = TRUE),
    mean_per_100k    = mean(veterans_per_100k, na.rm = TRUE)
  )

national_mean_per_100k <- as.numeric(summary_stats$mean_per_100k)
national_median_count <- as.numeric(summary_stats$median_per_state)

### |-  panel 1 data ----
# A) Veterans per 100k vs US mean
panel_1_data <- ww2_veterans_clean |>
  filter(!is.na(veterans_per_100k)) |>
  mutate(
    diff_from_mean = veterans_per_100k - national_mean_per_100k,
    state = fct_reorder(state, diff_from_mean),
    above_avg = diff_from_mean > 0
  ) |>
  slice_max(order_by = abs(diff_from_mean), n = 20)

### |-  panel 2 data ----
# B) Top states by per-capita rate
panel_2_data <- ww2_veterans_clean |>
  filter(!is.na(veterans_per_100k)) |>
  arrange(desc(veterans_per_100k)) |>
  slice_head(n = 20) |>
  mutate(state = fct_reorder(state, veterans_per_100k))

### |-  panel 3 data ----
# C) Histogram + density with labels for states ≥ 3,000 veterans
big_states <- ww2_veterans_clean |>
  filter(living_wwii_veterans_2025 >= 3000) |>
  mutate(y_pos = 0.00003)

top5_share <- ww2_veterans_clean |>
  arrange(desc(living_wwii_veterans_2025)) |>
  slice_head(n = 5) |>
  summarise(share = sum(living_wwii_veterans_2025, na.rm = TRUE) /
    sum(ww2_veterans_clean$living_wwii_veterans_2025, na.rm = TRUE)) |>
  pull(share)

### |-  panel 4 data ----
# D) Box + jitter
panel_4_data <- ww2_veterans_clean |>
  filter(!is.na(veterans_per_100k)) |>
  group_by(region) |>
  mutate(
    regional_median = median(veterans_per_100k),
    n_states = n()
  ) |>
  ungroup() |>
  mutate(region = fct_reorder(region, regional_median, .desc = TRUE))

region_levels <- levels(panel_4_data$region)
n_map <- panel_4_data |>
  distinct(region, n_states) |>
  deframe()
label_map <- setNames(
  paste0(region_levels, "\n(n=", n_map[region_levels], ")"),
  region_levels
)
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
# Get base colors with custom palette
colors <- get_theme_colors(
  palette = list(
    below_avg = "#D97548",
    above_avg = "#4A7C8C",
    primary_accent = "#2B4C5E",
    secondary_accent = "#D97548",
    box_northeast = "#4A7C8C",
    box_west = "#8B9D57",
    box_south = "#D97548",
    box_midwest = "#6B8CAE",
    box_territory = "#999999",
    gray_dark = "#3D3D3D",
    gray_medium = "#9A9A9A",
    gray_light = "#E6E6E6"
  )
)

### |-  titles and caption ----
title_text <- "Living WWII Veterans by State (2025)"

subtitle_text <- str_glue(
  "**{comma(summary_stats$total_veterans)}** veterans remain; ",
  "rates per 100k use U.S. Census 2023 population estimates"
)

# Create caption
caption_text <- create_mm_caption(
  mm_year = current_year,
  mm_week = current_week,
  source_text = "(1) National WWII Museum (2025), (2) U.S. Census Bureau (2023 Population Estimates via tidycensus, retrieved 20251111). "
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # # Text styling
    plot.title = element_text(
      size = rel(1.6), family = fonts$title, face = "bold",
      color = colors$title, lineheight = 1.1, hjust = 0,
      margin = margin(t = 5, b = 10)
    ),
    plot.subtitle = element_markdown(
      size = rel(0.95), family = fonts$subtitle, face = "italic",
      color = alpha(colors$subtitle, 0.9), lineheight = 1.1,
      margin = margin(t = 0, b = 20)
    ),

    # Legend formatting
    legend.position = "plot",
    legend.justification = "top",
    legend.margin = margin(l = 12, b = 5),
    legend.key.size = unit(0.8, "cm"),
    legend.box.margin = margin(b = 10),
    legend.title = element_text(face = "bold"),

    # Axis formatting
    axis.ticks.y = element_blank(),
    axis.ticks.x = element_line(color = "gray", linewidth = 0.5),
    axis.title.x = element_text(
      face = "bold", size = rel(0.85),
      margin = margin(t = 10)
    ),
    axis.title.y = element_text(
      face = "bold", size = rel(0.85),
      margin = margin(r = 10)
    ),
    axis.text.x = element_text(
      size = rel(0.85), family = fonts$subtitle,
      color = colors$text
    ),
    axis.text.y = element_text(
      size = rel(0.85), family = fonts$subtitle,
      color = colors$text
    ),

    # Grid lines
    panel.grid.minor = element_line(color = "#ecf0f1", linewidth = 0.2),
    panel.grid.major = element_line(color = "#ecf0f1", linewidth = 0.4),

    # Margin
    plot.margin = margin(20, 20, 20, 20)
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |-  panel 1 plot ----
# A) Veterans per 100k vs US mean
panel_1 <- ggplot(panel_1_data, aes(diff_from_mean, state, fill = above_avg)) +
  # Geoms
  geom_col(width = 0.68) +
  geom_vline(xintercept = 0, linewidth = 0.8, color = colors$palette$gray_dark) +
  geom_text(aes(label = number(diff_from_mean, accuracy = 0.1)),
    hjust = ifelse(panel_1_data$diff_from_mean > 0, -0.15, 1.15),
    size = 2.8, color = colors$palette$gray_dark
  ) +
  # Scales
  scale_fill_manual(values = c(`TRUE` = colors$palette$above_avg, `FALSE` = colors$palette$below_avg)) +
  scale_x_continuous(
    labels = label_number(accuracy = 1),
    expand = expansion(mult = c(0.1, 0.12))
  ) +
  # Labs
  labs(
    title = "A. Veterans per 100k vs US Mean",
    subtitle = "Higher values indicate greater veteran concentration (†)",
    x = "Difference from US mean", y = NULL
  ) +
  # Theme
  theme(
    plot.margin = margin(5, 5, 5, 5),
    panel.grid.major.y = element_blank(),
    axis.text.y = element_text(margin = margin(r = 4))
  )

### |-  panel 2 plot ----
# B) Top states by per-capita rate
panel_2 <-
  ggplot(panel_2_data, aes(veterans_per_100k, state)) +
  # Geoms
  geom_segment(aes(x = 0, xend = veterans_per_100k, yend = state),
    color = colors$palette$gray_light, linewidth = 1.1
  ) +
  geom_point(size = 3.2, color = colors$palette$primary_accent) +
  geom_vline(
    xintercept = national_mean_per_100k, linetype = "dashed",
    color = colors$palette$gray_dark, linewidth = 0.6
  ) +
  geom_text(aes(label = number(veterans_per_100k, accuracy = 0.1)),
    nudge_x = 1.0, hjust = 0, size = 2.8, color = colors$palette$gray_dark
  ) +
  # Scales
  scale_x_continuous(
    labels = label_number(accuracy = 1),
    expand = expansion(mult = c(0.01, 0.15))
  ) +
  # Labs
  labs(
    title = "B. Top States by Veterans per 100k",
    subtitle = glue(
      "Each exceeds the national average of {number(national_mean_per_100k, accuracy = 0.1)} per 100k (†)"
    ),
    x = "Veterans per 100k residents", y = NULL
  ) +
  # Theme
  theme(
    plot.margin = margin(5, 5, 5, 5),
    panel.grid.major.y = element_blank(),
    axis.text.y = element_text(margin = margin(r = 4))
  )

### |-  panel 3 plot ----
# C) Histogram + density with labels for states ≥ 3,000 veterans
panel_3 <-
  ggplot(ww2_veterans_clean, aes(living_wwii_veterans_2025)) +
  # Geoms
  geom_histogram(aes(y = after_stat(density)),
    binwidth = 250, boundary = 0,
    fill = colors$palette$primary_accent, alpha = 0.72,
    color = "white", linewidth = 0.3
  ) +
  geom_density(color = colors$palette$secondary_accent, linewidth = 1.0) +
  geom_vline(
    xintercept = national_median_count, linetype = "dotted",
    color = colors$palette$gray_dark, linewidth = 0.6
  ) +
  geom_label_repel(
    data = big_states,
    aes(x = living_wwii_veterans_2025, y = y_pos, label = state),
    seed = 2025, size = 3, label.size = 0.25,
    fill = alpha("white", 0.9), color = colors$palette$gray_dark,
    direction = "y", nudge_y = 0.00002, min.segment.length = 0,
    box.padding = 0.25
  ) +
  # Annotate
  annotate("label",
    x = national_median_count, y = 0.0009, label = "State median",
    size = 2.7, label.size = 0, fill = alpha("white", 0.92),
    color = colors$gray_dark
  ) +
  annotate("label",
    x = Inf, y = Inf, hjust = 1.02, vjust = 1.2,
    label = paste0("Top 5 hold ", percent(top5_share, accuracy = 1)),
    size = 3, label.size = 0, fill = alpha("white", 0.9),
    color = colors$gray_dark
  ) +
  # Scales
  scale_x_continuous(
    labels = label_comma(),
    expand = expansion(mult = c(0.02, 0.02))
  ) +
  scale_y_continuous(labels = label_number(accuracy = 0.0001)) +
  # Labs
  labs(
    title = "C. Distribution of Veterans Across States",
    subtitle = glue(
      "Most states have fewer than 1,000; top 5 hold {percent(top5_share, accuracy = 1)} of all veterans"
    ),
    x = "Living WWII veterans (count)", y = "Density"
  ) +
  # Theme
  theme(plot.margin = margin(5, 5, 5, 5))

### |-  panel 4 plot ----
# D) Box + jitter
panel_4 <-
  ggplot(panel_4_data, aes(region, veterans_per_100k, color = region)) +
  # Geoms
  geom_boxplot(width = 0.58, alpha = 0.28, linewidth = 0.8, outlier.shape = NA) +
  geom_jitter(width = 0.15, size = 2.2, alpha = 0.75) +
  geom_hline(
    yintercept = national_mean_per_100k, linetype = "dashed",
    color = colors$palette$gray_dark, linewidth = 0.6
  ) +
  geom_label_repel(
    data = filter(panel_4_data, state == "New Hampshire"),
    aes(label = state),
    seed = 2025, size = 3, label.size = 0.25,
    fill = alpha("white", 0.9), color = colors$palette$gray_dark,
    nudge_y = 2, nudge_x = 0.2
  ) +
  # Scales
  scale_color_manual(values = c(
    "Northeast" = colors$palette$box_northeast,
    "West" = colors$palette$box_west,
    "South" = colors$palette$box_south,
    "Midwest" = colors$palette$box_midwest,
    "Territory" = colors$palette$box_territory
  ), guide = "none") +
  scale_x_discrete(limits = region_levels, labels = label_map[region_levels]) +
  coord_cartesian(ylim = c(0, NA)) +
  # Labs
  labs(
    title = "D. Regional Distribution of Veterans per 100k",
    subtitle = "Northeast has highest rates; South has many states but lower median (†)",
    x = "Region", y = "Veterans per 100k residents"
  ) +
  # Theme
  theme(
    plot.margin = margin(5, 5, 5, 5),
    axis.text.x = element_text(lineheight = 1.1)
    )

### |-  combined plot ----
combined_plots <- (panel_1 | panel_2) / (panel_3 | panel_4) +
  plot_layout(heights = c(1.2, 0.8), widths = c(1, 1))

combined_plots <- combined_plots +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    # tag_levels = "A",
    theme = theme(
      plot.title = element_text(
        size = rel(2.4),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.1,
        margin = margin(t = 5, b = 5)
      ),
      plot.subtitle = element_markdown(
        size = rel(1.2),
        family = fonts$subtitle,
        color = alpha(colors$subtitle, 0.9),
        lineheight = 1.2,
        margin = margin(t = 5, b = 15)
      ),
      plot.caption = element_markdown(
        size = rel(0.65),
        family = fonts$caption,
        color = colors$caption,
        hjust = 0,
        margin = margin(t = 10)
      )
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  plot = combined_plots,
  type = "makeovermonday",
  year = current_year,
  week = current_week,
  width = 14,
  height = 10
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in `r create_link(project_file, repo_file)`.
For the full repository, `r create_link("click here", repo_main)`.
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data:
- Makeover Monday `r current_year` Week `r current_week`: `r create_link("Living WWII Veterans by State 2025", data_main)`
2. Article
- `r create_link("Living WWII Veterans by State 2025", data_secondary)`
3. Citation:
- National WWII Museum. (2025). *WWII Veteran Statistics*. Retrieved from https://www.nationalww2museum.org/war/wwii-veteran-statistics
- US Census Bureau. (2023). *Annual Estimates of the Resident Population*. Retrieved via tidycensus package.
:::
#### 11. Custom Functions Documentation
::: {.callout-note collapse="true"}
##### 📦 Custom Helper Functions
This analysis uses custom functions from my personal module library for efficiency and consistency across projects.
**Functions Used:**
- **`fonts.R`**: `setup_fonts()`, `get_font_families()` - Font management with showtext
- **`social_icons.R`**: `create_social_caption()` - Generates formatted social media captions
- **`image_utils.R`**: `save_plot()` - Consistent plot saving with naming conventions
- **`base_theme.R`**: `create_base_theme()`, `extend_weekly_theme()`, `get_theme_colors()` - Custom ggplot2 themes
**Why custom functions?**\
These utilities standardize theming, fonts, and output across all my data visualizations. The core analysis (data tidying and visualization logic) uses only standard tidyverse packages.
**Source Code:**\
View all custom functions → [GitHub: R/utils](https://github.com/poncest/personal-website/tree/master/R)
:::

