---
title: "Preserving Public Health Knowledge: CDC Dataset Categories at Risk"
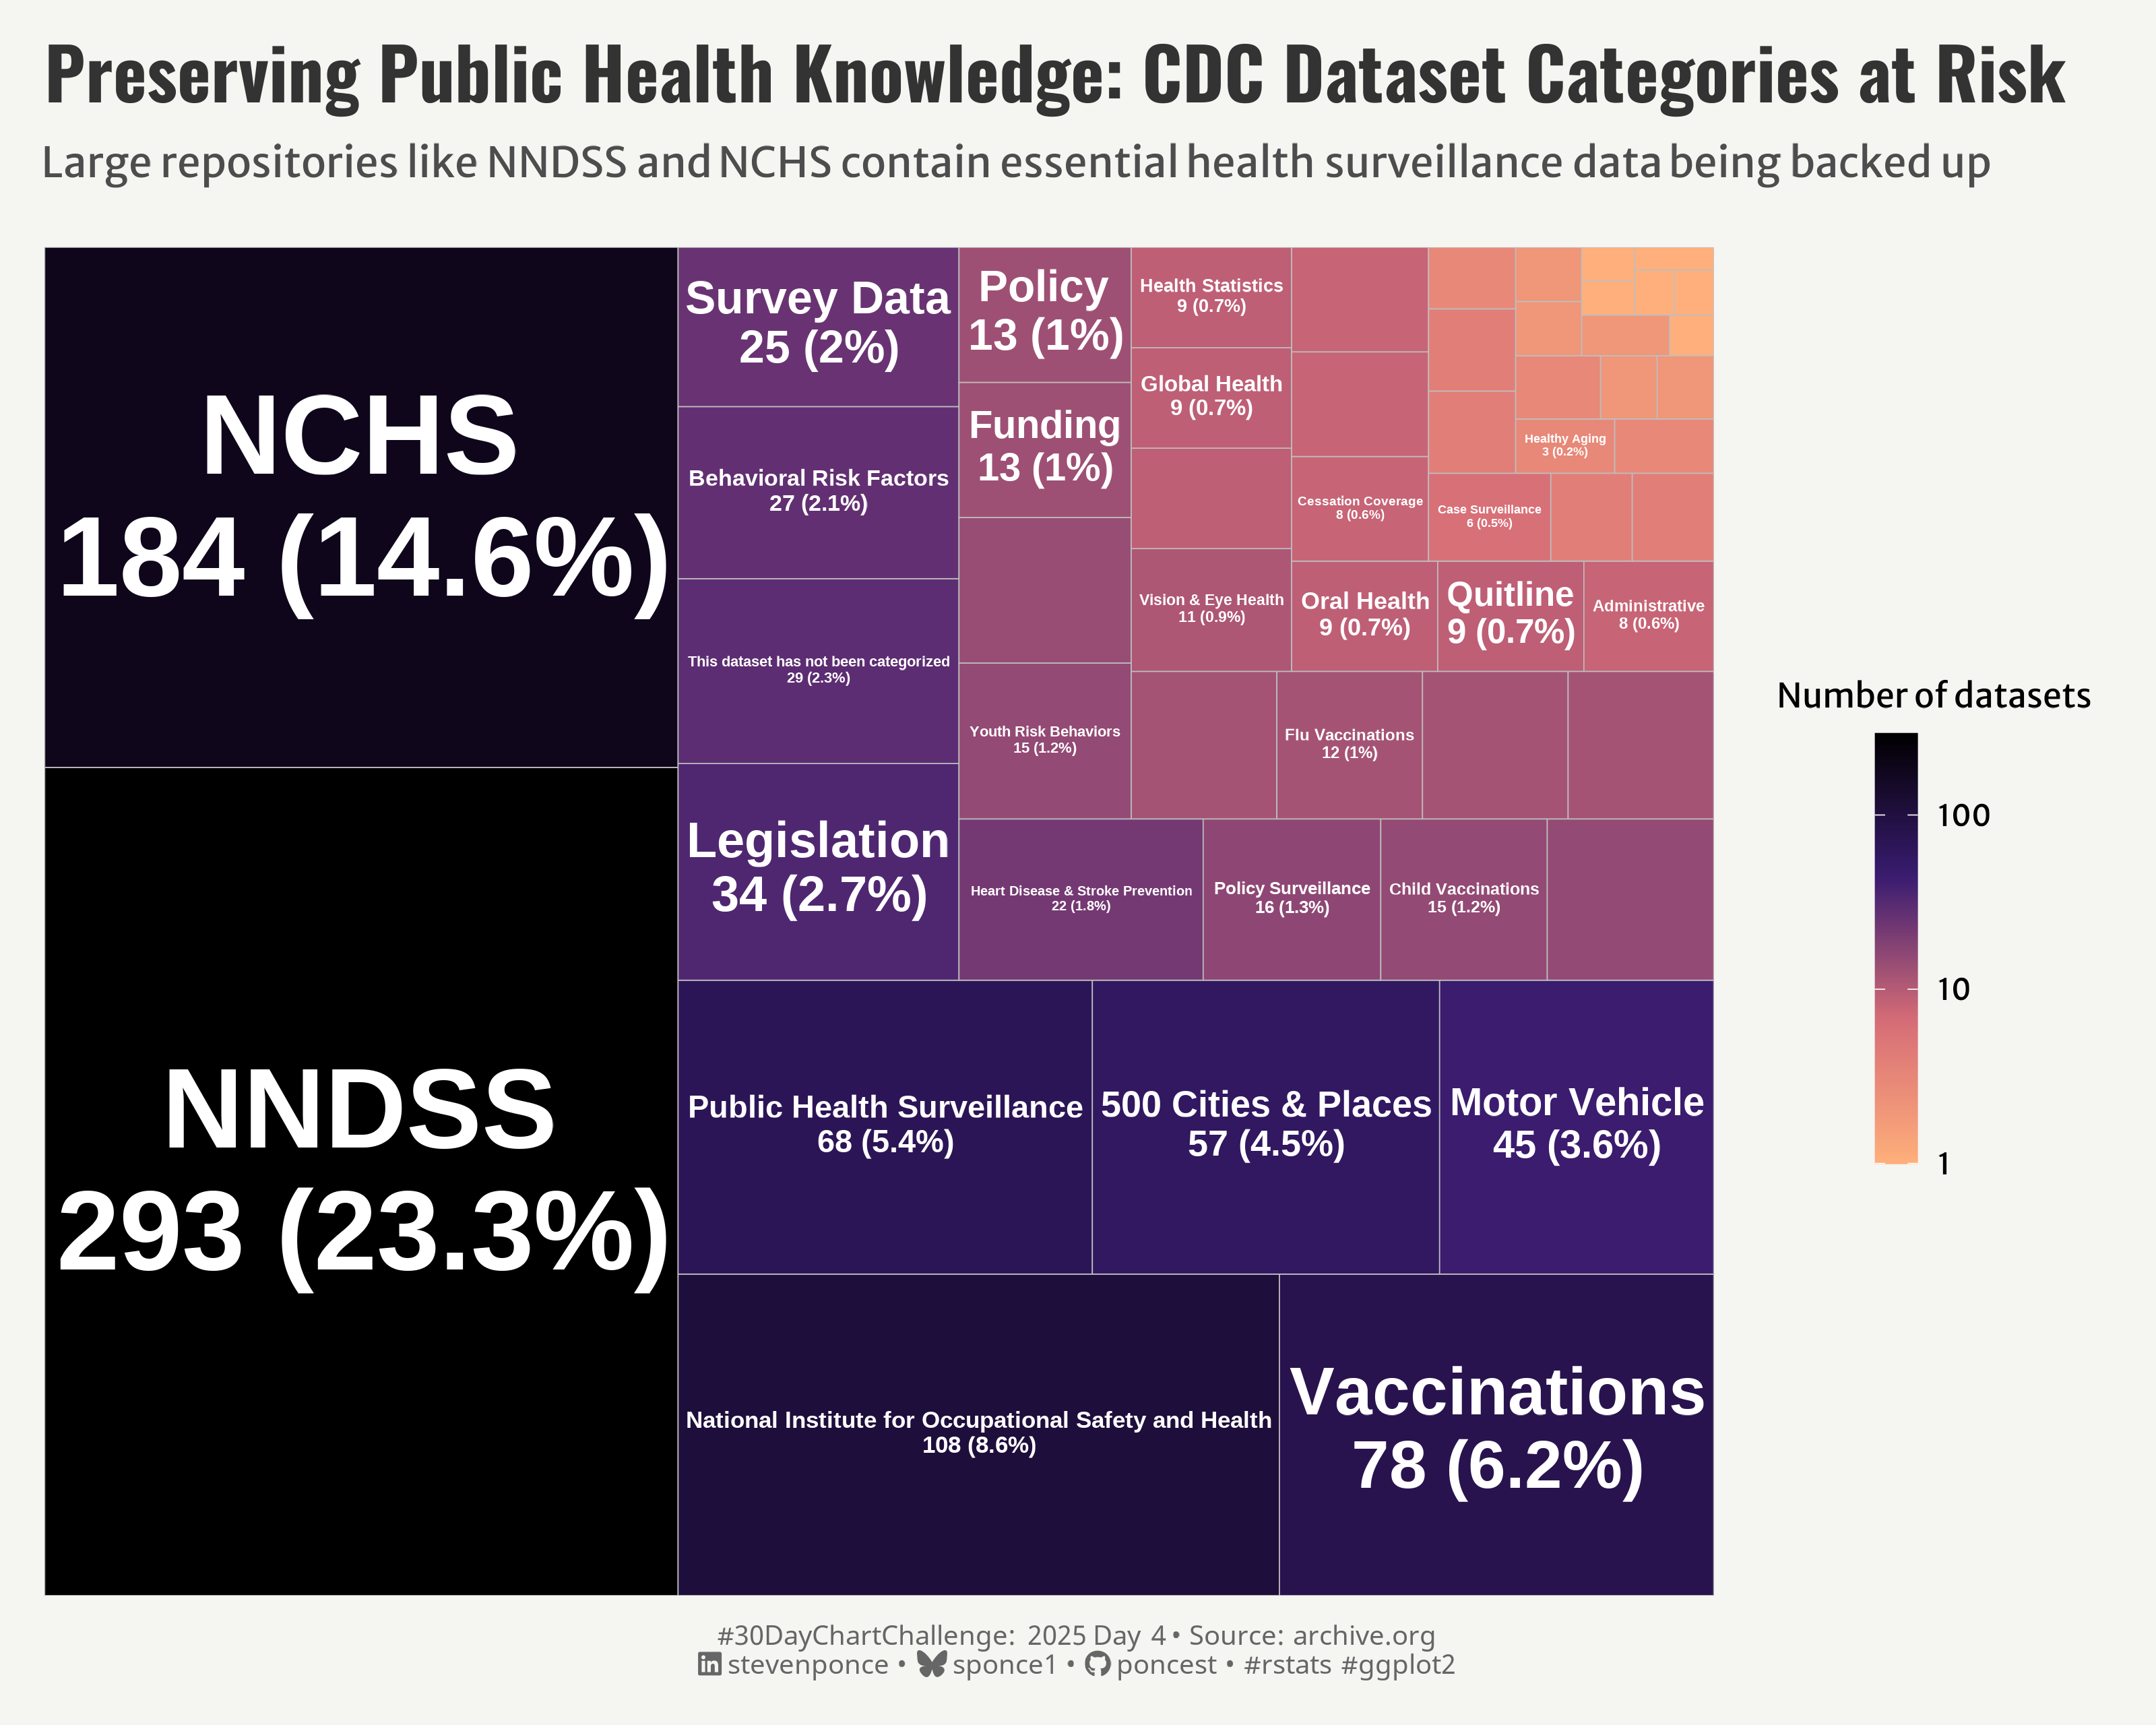
subtitle: "Large repositories like NNDSS and NCHS contain essential health surveillance data being backed up"
description: "A treemap visualization for Day 4 of the #30DayChartChallenge 2025, comparing the sizes of CDC dataset categories being preserved by Archive.org amid concerns of data removal. The visualization highlights how two categories—NNDSS and NCHS—account for nearly 40% of all archived CDC datasets, underscoring what scientific resources are being protected from potential loss."
author: "Steven Ponce"
date: "2025-04-04"
categories: ["30DayChartChallenge", "2025"]
tags: [
"treemap",
"ggplot2",
"public health",
"data preservation",
"CDC",
"archive.org",
"big-vs-small",
"health surveillance",
"data rescue",
"NNDSS",
"NCHS"
]
image: "thumbnails/30dcc_2025_04.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
# filters:
# - social-share
# share:
# permalink: "https://stevenponce.netlify.app/data_visualizations/30DayChartChallenge/2025/30dcc_2025_04.html"
# description: "Day 4 of #30DayChartChallenge: Visualizing the size disparities among CDC dataset categories being preserved by Archive.org. See which public health data collections are most at risk and which contain the most information."
# twitter: true
# linkedin: true
# email: true
# facebook: false
# reddit: false
# stumble: false
# tumblr: false
# mastodon: true
# bsky: true
---
{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"
## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
pacman::p_load(
  tidyverse,      # Easily Install and Load the 'Tidyverse'
  ggtext,         # Improved Text Rendering Support for 'ggplot2'
  showtext,       # Using Fonts More Easily in R Graphs
  janitor,        # Simple Tools for Examining and Cleaning Dirty Data
  skimr,          # Compact and Flexible Summaries of Data
  scales,         # Scale Functions for Visualization
  lubridate,      # Make Dealing with Dates a Little Easier
  treemapify,     # Draw Treemaps in 'ggplot2'
  camcorder       # Record Your Plot History
)
})

### |- figure size ----
gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  = 10,
    height = 8,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
tt <- tidytuesdayR::tt_load(2025, week = 6)

cdc_datasets <- tt$cdc_datasets |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false
glimpse(cdc_datasets)
skim(cdc_datasets)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false
### |- Tidy ----
# Count datasets by category
category_counts <- cdc_datasets |>
  count(category) |>
  arrange(desc(n)) |>
  filter(!is.na(category)) |>
  mutate(
    category = if_else(is.na(category), "Uncategorized", category),
    percent = n / sum(n) * 100,
    label = paste0(category, "\n", n, " (", round(percent, 1), "%)")
    )
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false
### |- plot aesthetics ----
colors <- get_theme_colors(palette =  colorRampPalette(c("#FFAF7B", "#D76D77", "#3A1C71", "black"))(30)
  )

### |-  titles and caption ----
# text
title_text    <- str_glue("Preserving Public Health Knowledge: CDC Dataset Categories at Risk")
subtitle_text <- str_glue("Large repositories like NNDSS and NCHS contain essential health surveillance data being backed up")

# Create caption
caption_text <- create_dcc_caption(
  dcc_year = 2025,
  dcc_day = 04,
  source_text =  "archive.org"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # Text styling
    plot.title = element_text(face = "bold", family = fonts$title, size = rel(1.14), margin = margin(b = 10)),
    plot.subtitle = element_text(family = fonts$subtitle, color = colors$text, size = rel(0.78), margin = margin(b = 20)),

    # Axis elements
    axis.title.y = element_text(color = colors$text, size = rel(0.8),
                              hjust = 1, vjust = 0.5, angle = 90),
    axis.title.x = element_blank(),
    axis.text.x = element_text(color = colors$text, size = rel(0.7)),
    axis.text.y = ggtext::element_markdown(),

    # Grid elements
    panel.grid.major = element_blank(),
    panel.grid.minor = element_blank(),

    # Legend elements
    legend.position = "right",
    legend.title = element_text(family = fonts$text, size = rel(0.8)),
    legend.text = element_text(family = fonts$text, size = rel(0.7)),

    # Plot margins
    plot.margin = margin(t = 10, r = 15, b = 10, l = 15),
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false
### |-  Plot ----
p <- ggplot(category_counts, aes(area = n, fill = n, label = label)) +
  # Geoms
  geom_treemap() +
  geom_treemap_text(
    colour = "white",
    place = "centre",
    grow = TRUE,
    min.size = 4,
    fontface = "bold",
    family = "sans"
  ) +
  # Scales
  scale_fill_gradientn(
    colors = colors$palette,
    trans = "log10",
    labels = comma_format(),
    breaks = c(1, 10, 100, 300),
    guide = guide_colorbar(
      direction = "vertical",
      barwidth = 1,
      barheight = 10,
      title.position = "top",
      title.hjust = 0.5
    )
  ) +
  # Labs
  labs(
    title = title_text,
    subtitle = subtitle_text,
    fill = "Number of datasets",
    caption = caption_text
  ) +
  # Theme
  theme(
    plot.title = element_text(
      size = rel(1.7),
      family = fonts$title,
      face  = "bold",
      color = colors$title,
      margin  = margin(t = 5, b = 5)
    ),
    plot.subtitle = element_markdown(
      size  = rel(1),
      family  = fonts$subtitle,
      color = colors$subtitle,
      lineheight = 1.1,
      margin  = margin(t = 5, b = 20)
    ),
    plot.caption = element_markdown(
      size  = rel(.65),
      family  = fonts$caption,
      color = colors$caption,
      lineheight  = 0.65,
      hjust = 0.5,
      halign  = 0.5,
      margin  = margin(t = 10, b = 5)
    ),
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false
### |-  plot image ----

save_plot(
  p,
  type = "30daychartchallenge",
  year = 2025,
  day = 04,
  width = 10,
  height = 8
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`30dcc_2025_04.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/30dcc_2025_04.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 week 06: [CDC Datasets](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-02-11)
:::
