---
title: "The Energy Transition Is Uneven"
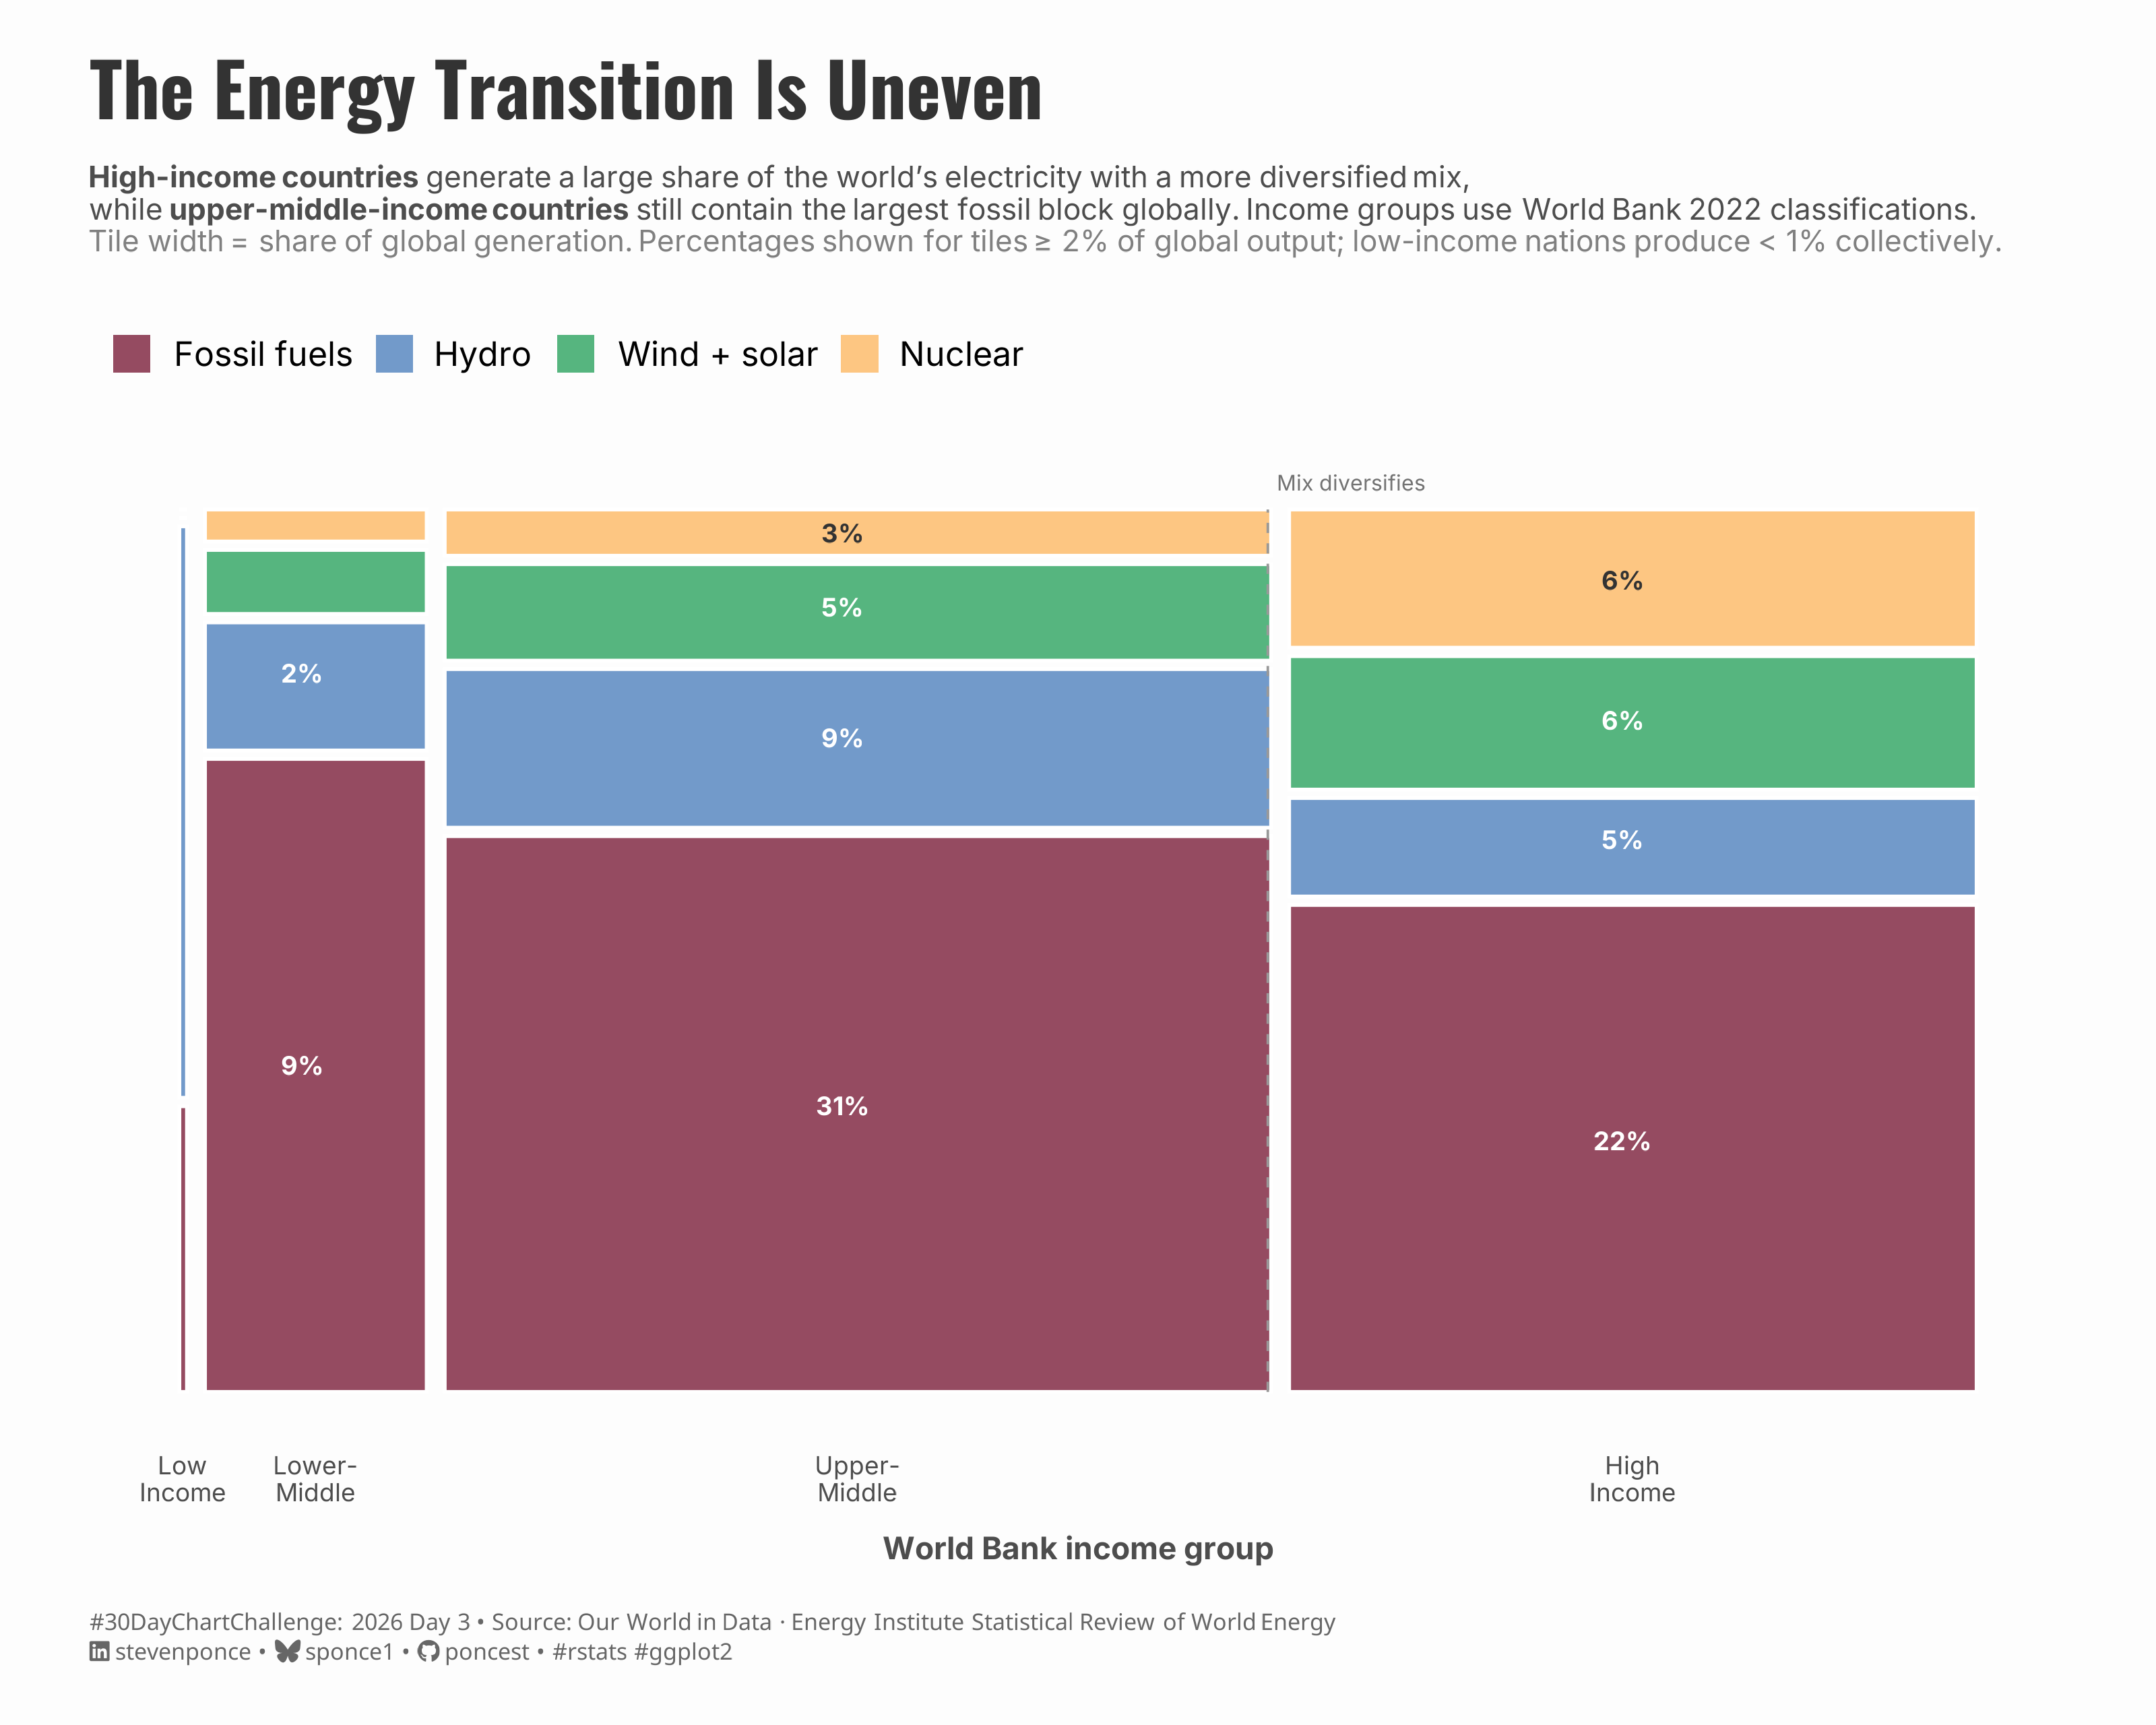
subtitle: "High-income countries generate a large share of the world's electricity with a more diversified mix, while upper-middle-income countries still contain the largest fossil block globally. Income groups use World Bank 2022 classifications."
description: "Mosaic chart exploring how electricity generation sources vary across World Bank income groups in 2022. Upper-middle-income countries — led by China — produce the largest share of global electricity, with fossil fuels dominating their mix. High-income countries show a more diversified portfolio including nuclear, wind, and solar. Built with R, ggplot2, and ggmosaic."
date: "2026-04-03"
author:
- name: "Steven Ponce"
url: "https://stevenponce.netlify.app"
citation:
url: "https://stevenponce.netlify.app/data_visualizations/30DayChartChallenge/2026/30dcc_2026_03.html"
categories: ["30DayChartChallenge", "2026"]
tags: [
"30DayChartChallenge",
"Comparisons",
"Mosaic",
"Energy",
"Electricity",
"Climate",
"Income Inequality",
"World Bank",
"Our World in Data",
"ggmosaic",
"ggplot2"
]
image: "thumbnails/30dcc_2026_03.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
{#fig-1}
### [**Steps to Create this Graphic**]{.mark}
#### [1. Load Packages & Setup]{.smallcaps}
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
pacman::p_load(
  tidyverse, ggtext, showtext,
  janitor, scales, glue, ggmosaic
  )
})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
  width  = 10,
  height = 8,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### [2. Read in the Data]{.smallcaps}
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

### |- OWID energy data ----
# Download: https://raw.githubusercontent.com/owid/energy-data/master/owid-energy-data.csv
energy_raw <- read_csv(
  here::here("data/30DayChartChallenge/2026/owid-energy-data.csv")
)

### |- World Bank income classification ----
# Source: World Bank Country and Lending Groups (FY2024)
# Full list: https://datahelpdesk.worldbank.org/knowledgebase/articles/906519
# Download:  https://databank.worldbank.org/data/download/site-content/CLASS.xlsx
# Note: Subset of ~130 major electricity-producing countries used here.
#       Join key: wb_income$country → energy_2022$country

### |- World Bank income classification ----
wb_income <- tribble(
  ~country,                       ~income_group,
  # Low income
  "Afghanistan",                  "Low income",
  "Burkina Faso",                 "Low income",
  "Burundi",                      "Low income",
  "Central African Republic",     "Low income",
  "Chad",                         "Low income",
  "Democratic Republic of Congo", "Low income",
  "Eritrea",                      "Low income",
  "Ethiopia",                     "Low income",
  "Guinea",                       "Low income",
  "Guinea-Bissau",                "Low income",
  "Liberia",                      "Low income",
  "Madagascar",                   "Low income",
  "Malawi",                       "Low income",
  "Mali",                         "Low income",
  "Mozambique",                   "Low income",
  "Niger",                        "Low income",
  "Rwanda",                       "Low income",
  "Sierra Leone",                 "Low income",
  "Somalia",                      "Low income",
  "South Sudan",                  "Low income",
  "Sudan",                        "Low income",
  "Syria",                        "Low income",
  "Togo",                         "Low income",
  "Uganda",                       "Low income",
  "Yemen",                        "Low income",
  "Zimbabwe",                     "Low income",
  # Lower-middle income
  "Bangladesh",                   "Lower-middle income",
  "Bolivia",                      "Lower-middle income",
  "Cambodia",                     "Lower-middle income",
  "Cameroon",                     "Lower-middle income",
  "Congo",                        "Lower-middle income",
  "Cote d'Ivoire",                "Lower-middle income",
  "Egypt",                        "Lower-middle income",
  "El Salvador",                  "Lower-middle income",
  "Ghana",                        "Lower-middle income",
  "Haiti",                        "Lower-middle income",
  "Honduras",                     "Lower-middle income",
  "India",                        "Lower-middle income",
  "Indonesia",                    "Lower-middle income",
  "Kenya",                        "Lower-middle income",
  "Kyrgyzstan",                   "Lower-middle income",
  "Laos",                         "Lower-middle income",
  "Lesotho",                      "Lower-middle income",
  "Mauritania",                   "Lower-middle income",
  "Morocco",                      "Lower-middle income",
  "Myanmar",                      "Lower-middle income",
  "Nepal",                        "Lower-middle income",
  "Nicaragua",                    "Lower-middle income",
  "Nigeria",                      "Lower-middle income",
  "Pakistan",                     "Lower-middle income",
  "Papua New Guinea",             "Lower-middle income",
  "Philippines",                  "Lower-middle income",
  "Senegal",                      "Lower-middle income",
  "Sri Lanka",                    "Lower-middle income",
  "Tanzania",                     "Lower-middle income",
  "Tunisia",                      "Lower-middle income",
  "Ukraine",                      "Lower-middle income",
  "Uzbekistan",                   "Lower-middle income",
  "Vietnam",                      "Lower-middle income",
  "Zambia",                       "Lower-middle income",
  # Upper-middle income
  "Albania",                      "Upper-middle income",
  "Algeria",                      "Upper-middle income",
  "Argentina",                    "Upper-middle income",
  "Armenia",                      "Upper-middle income",
  "Azerbaijan",                   "Upper-middle income",
  "Belarus",                      "Upper-middle income",
  "Belize",                       "Upper-middle income",
  "Bosnia and Herzegovina",       "Upper-middle income",
  "Botswana",                     "Upper-middle income",
  "Brazil",                       "Upper-middle income",
  "Bulgaria",                     "Upper-middle income",
  "China",                        "Upper-middle income",
  "Colombia",                     "Upper-middle income",
  "Costa Rica",                   "Upper-middle income",
  "Cuba",                         "Upper-middle income",
  "Dominican Republic",           "Upper-middle income",
  "Ecuador",                      "Upper-middle income",
  "Equatorial Guinea",            "Upper-middle income",
  "Fiji",                         "Upper-middle income",
  "Gabon",                        "Upper-middle income",
  "Georgia",                      "Upper-middle income",
  "Guatemala",                    "Upper-middle income",
  "Iran",                         "Upper-middle income",
  "Iraq",                         "Upper-middle income",
  "Jamaica",                      "Upper-middle income",
  "Jordan",                       "Upper-middle income",
  "Kazakhstan",                   "Upper-middle income",
  "Kosovo",                       "Upper-middle income",
  "Libya",                        "Upper-middle income",
  "Malaysia",                     "Upper-middle income",
  "Maldives",                     "Upper-middle income",
  "Mexico",                       "Upper-middle income",
  "Moldova",                      "Upper-middle income",
  "Montenegro",                   "Upper-middle income",
  "Namibia",                      "Upper-middle income",
  "North Macedonia",              "Upper-middle income",
  "Paraguay",                     "Upper-middle income",
  "Peru",                         "Upper-middle income",
  "Russia",                       "Upper-middle income",
  "Serbia",                       "Upper-middle income",
  "South Africa",                 "Upper-middle income",
  "Thailand",                     "Upper-middle income",
  "Turkmenistan",                 "Upper-middle income",
  "Turkey",                       "Upper-middle income",
  "Venezuela",                    "Upper-middle income",
  # High income
  "Australia",                    "High income",
  "Austria",                      "High income",
  "Bahrain",                      "High income",
  "Belgium",                      "High income",
  "Canada",                       "High income",
  "Chile",                        "High income",
  "Croatia",                      "High income",
  "Cyprus",                       "High income",
  "Czech Republic",               "High income",
  "Denmark",                      "High income",
  "Estonia",                      "High income",
  "Finland",                      "High income",
  "France",                       "High income",
  "Germany",                      "High income",
  "Greece",                       "High income",
  "Hungary",                      "High income",
  "Iceland",                      "High income",
  "Ireland",                      "High income",
  "Israel",                       "High income",
  "Italy",                        "High income",
  "Japan",                        "High income",
  "South Korea",                  "High income",
  "Kuwait",                       "High income",
  "Latvia",                       "High income",
  "Lithuania",                    "High income",
  "Luxembourg",                   "High income",
  "Malta",                        "High income",
  "Netherlands",                  "High income",
  "New Zealand",                  "High income",
  "Norway",                       "High income",
  "Oman",                         "High income",
  "Poland",                       "High income",
  "Portugal",                     "High income",
  "Qatar",                        "High income",
  "Romania",                      "High income",
  "Saudi Arabia",                 "High income",
  "Singapore",                    "High income",
  "Slovakia",                     "High income",
  "Slovenia",                     "High income",
  "Spain",                        "High income",
  "Sweden",                       "High income",
  "Switzerland",                  "High income",
  "Trinidad and Tobago",          "High income",
  "United Arab Emirates",         "High income",
  "United Kingdom",               "High income",
  "United States",                "High income",
  "Uruguay",                      "High income"
)
```
#### [3. Examine the Data]{.smallcaps}
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(energy_raw)
```
#### [4. Tidy Data]{.smallcaps}
```{r}
#| label: tidy
#| warning: false

### |- Filter to 2022 and relevant columns ----
energy_2022 <- energy_raw |>
  filter(year == 2022) |>
  select(
    country,
    coal_electricity, oil_electricity, gas_electricity,
    hydro_electricity, wind_electricity, solar_electricity,
    nuclear_electricity
  ) |>
  filter(!str_detect(
    country,
    "World|Africa|Asia|Europe|America|OECD|income|Non-OECD|Asia Pacific|Middle East|CIS|G20|European Union|High-income|Low-income|Lower-middle|Upper-middle|OPEC|Eurasia"
  ))

### |- Join World Bank income classification ----
energy_income <- energy_2022 |>
  inner_join(wb_income, by = "country")

### |- Compute energy source totals per country ----
energy_sources <- energy_income |>
  mutate(
    fossil            = coal_electricity + oil_electricity + gas_electricity,
    hydro             = hydro_electricity,
    modern_renewables = wind_electricity + solar_electricity,
    nuclear           = nuclear_electricity
  ) |>
  select(country, income_group, fossil, hydro, modern_renewables, nuclear) |>
  mutate(across(fossil:nuclear, ~ replace_na(.x, 0)))

### |- Pivot to long format ----
energy_long <- energy_sources |>
  pivot_longer(
    cols      = fossil:nuclear,
    names_to  = "source",
    values_to = "twh"
  )

### |- Factor ordering ----
income_order <- c(
  "Low income", "Lower-middle income",
  "Upper-middle income", "High income"
)
source_order <- c("fossil", "hydro", "modern_renewables", "nuclear")

### |- Aggregate to income group level ----
energy_agg <- energy_long |>
  mutate(
    income_group = factor(income_group, levels = income_order),
    source       = factor(source, levels = source_order)
  ) |>
  group_by(income_group, source) |>
  summarise(total_twh = sum(twh), .groups = "drop") |>
  tidyr::complete(income_group, source, fill = list(total_twh = 0)) |>
  group_by(income_group) |>
  mutate(
    group_total = sum(total_twh),
    share       = if_else(group_total > 0, total_twh / group_total, 0)
  ) |>
  ungroup()

### |- Pre-compute tile coordinates for manual labels ----
group_totals <- energy_agg |>
  distinct(income_group, group_total) |>
  arrange(income_group) |>
  mutate(
    grand_total = sum(group_total),
    x_width     = group_total / grand_total,
    x_max       = cumsum(x_width),
    x_min       = x_max - x_width,
    x_mid       = (x_min + x_max) / 2
  )

grand_total <- sum(group_totals$group_total)

low_income_xmax <- group_totals |>
  filter(income_group == "Low income") |>
  pull(x_max)

upper_middle_xmax <- group_totals |>
  filter(income_group == "Upper-middle income") |>
  pull(x_max)

tile_coords <- energy_agg |>
  arrange(income_group, source) |>
  group_by(income_group) |>
  mutate(
    y_max = cumsum(share),
    y_min = y_max - share,
    y_mid = (y_min + y_max) / 2
  ) |>
  ungroup() |>
  left_join(
    group_totals |> select(income_group, x_min, x_max, x_mid, x_width),
    by = "income_group"
  ) |>
  mutate(
    global_share = group_total / grand_total * share,
    label        = if_else(global_share >= 0.018,
                           percent(global_share, accuracy = 1), ""),
    label_color  = if_else(source == "nuclear", "gray20", "white")
  )

### |- Plot data ----
set.seed(2026)
mosaic_data <- energy_agg |>
  mutate(units = round(total_twh / 10)) |>
  filter(units > 0) |>
  uncount(units)
```
#### [5. Visualization Parameters]{.smallcaps}
```{r}
#| label: params
#| include: true
#| warning: false

### |- plot aesthetics ----
colors <- get_theme_colors(
  palette = c(
    "fossil"            = "#7A1E3A",
    "hydro"             = "#4F81BD",
    "modern_renewables" = "#2CA25F",
    "nuclear"           = "#FDB863"
  )
)

### |- titles and caption ----
title_text <- str_glue("The Energy Transition Is Uneven")

subtitle_text <- str_glue(
  "**High-income countries** generate a large share of the world's electricity with a more diversified mix,<br>",
  "while **upper-middle-income countries** still contain the largest fossil block globally. ",
  "Income groups use World Bank 2022 classifications.<br>",
  "<span style='color:#808080;'>Tile width = share of global generation. ",
  "Percentages shown for tiles ≥ 2% of global output; low-income nations produce < 1% collectively.</span>"
)

caption_text <- create_dcc_caption(
  dcc_year    = 2026,
  dcc_day     = 03,
  source_text = "Our World in Data · Energy Institute Statistical Review of World Energy"
)

### |- fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----
base_theme <- create_base_theme(colors)

weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    plot.title = element_text(
      face = "bold", family = fonts$title, color = colors$title,
      size = rel(1.75), margin = margin(b = 6)
    ),
    plot.subtitle = element_markdown(
      family = fonts$subtitle, size = rel(0.70), color = colors$subtitle,
      lineheight = 1.1, margin = margin(t = 5, b = 18)
    ),
    plot.caption = element_markdown(
      family = fonts$caption, , size = rel(0.55), color = colors$caption,
      margin = margin(t = 16), hjust = 0, lineheight = 1.3,
    ),

    # Legend
    legend.position = "top",
    legend.justification = "left",
    legend.title = element_blank(),
    legend.text = element_text(family = fonts$text, size = rel(0.8)),
    legend.key.size = unit(0.5, "cm"),
    legend.spacing.x = unit(0.35, "cm"),

    # Axes
    axis.title.x = element_text(
      family = fonts$text, size = rel(0.8),
      margin = margin(t = 10), color = "gray30"
    ),
    axis.title.y = element_blank(),
    axis.text.x = element_text(
      family = fonts$text, size = rel(0.75), color = "gray30"
    ),
    axis.text.y = element_blank(),
    axis.ticks = element_blank(),

    # Panel
    panel.grid.major = element_blank(),
    panel.grid.minor = element_blank(),
    panel.border = element_blank(),
    plot.margin = margin(20, 30, 20, 30)
  )
)

theme_set(weekly_theme)
```
#### [6. Plot]{.smallcaps}
```{r}
#| label: plot
#| warning: false

### |- main plot ----
set.seed(2026)

p <- ggplot(mosaic_data) +
  # Geoms
  geom_mosaic(
    aes(
      x    = product(source, income_group),
      fill = source
    ),
    color     = "white",
    linewidth = 0.6,
    na.rm     = TRUE
  ) +
  geom_text(
    data        = tile_coords |> filter(label != ""),
    aes(x = x_mid, y = y_mid, label = label, color = label_color),
    size        = 3,
    fontface    = "bold",
    inherit.aes = FALSE
  ) +
  # Annotate
  annotate(
    "segment",
    x    = upper_middle_xmax,
    xend = upper_middle_xmax,
    y    = 0,
    yend = 1,
    color     = "gray60",
    linewidth = 0.4,
    linetype  = "dashed"
  ) +
  annotate(
    "text",
    x     = upper_middle_xmax + 0.005,
    y     = 1.03,
    label = "Mix diversifies",
    hjust = 0,
    size  = 2.5,
    color = "gray45"
  ) +
  # Scales
  scale_color_identity() +
  scale_fill_manual(
    values = colors$palette,
    labels = c(
      "fossil"            = "Fossil fuels",
      "hydro"             = "Hydro",
      "modern_renewables" = "Wind + solar",
      "nuclear"           = "Nuclear"
    )
  ) +
  scale_x_productlist(
    labels = c(
      "Low income"          = "Low\nIncome",
      "Lower-middle income" = "Lower-\nMiddle",
      "Upper-middle income" = "Upper-\nMiddle",
      "High income"         = "High\nIncome"
    )
  ) +
  scale_y_productlist(labels = NULL) +
  coord_cartesian(clip = "off") +
  # Labs
  labs(
    title    = title_text,
    subtitle = subtitle_text,
    caption  = caption_text,
    x        = "World Bank income group"
  ) +
  guides(
    fill = guide_legend(
      nrow         = 1,
      override.aes = list(color = NA)
    )
  )
```
#### [7. Save]{.smallcaps}
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot(
  p,
  type = "30daychartchallenge",
  year = 2026,
  day = 03,
  width = 10,
  height = 8
  )
```
#### [8. Session Info]{.smallcaps}
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### [9. GitHub Repository]{.smallcaps}
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`30dcc_2026_03.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2026/30dcc_2026_03.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### [10. References]{.smallcaps}
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- Our World in Data. (2023). *Electricity Mix*. Based on data from Ember and the
Energy Institute Statistical Review of World Energy.
Retrieved from https://raw.githubusercontent.com/owid/energy-data/master/owid-energy-data.csv
- Ember. (2023). *Yearly Electricity Data*. Retrieved from https://ember-energy.org
- Energy Institute. (2023). *Statistical Review of World Energy*.
Retrieved from https://www.energyinst.org/statistical-review
:::
#### [11. Custom Functions Documentation]{.smallcaps}
::: {.callout-note collapse="true"}
##### 📦 Custom Helper Functions
This analysis uses custom functions from my personal module library for efficiency and consistency across projects.
**Functions Used:**
- **`fonts.R`**: `setup_fonts()`, `get_font_families()` - Font management with showtext
- **`social_icons.R`**: `create_social_caption()` - Generates formatted social media captions
- **`image_utils.R`**: `save_plot()` - Consistent plot saving with naming conventions
- **`base_theme.R`**: `create_base_theme()`, `extend_weekly_theme()`, `get_theme_colors()` - Custom ggplot2 themes
**Why custom functions?**\
These utilities standardize theming, fonts, and output across all my data visualizations. The core analysis (data tidying and visualization logic) uses only standard tidyverse packages.
**Source Code:**\
View all custom functions → [GitHub: R/utils](https://github.com/poncest/personal-website/tree/master/R)
:::
