---
title: "The Energy Transition Looks Different at Every Scale"
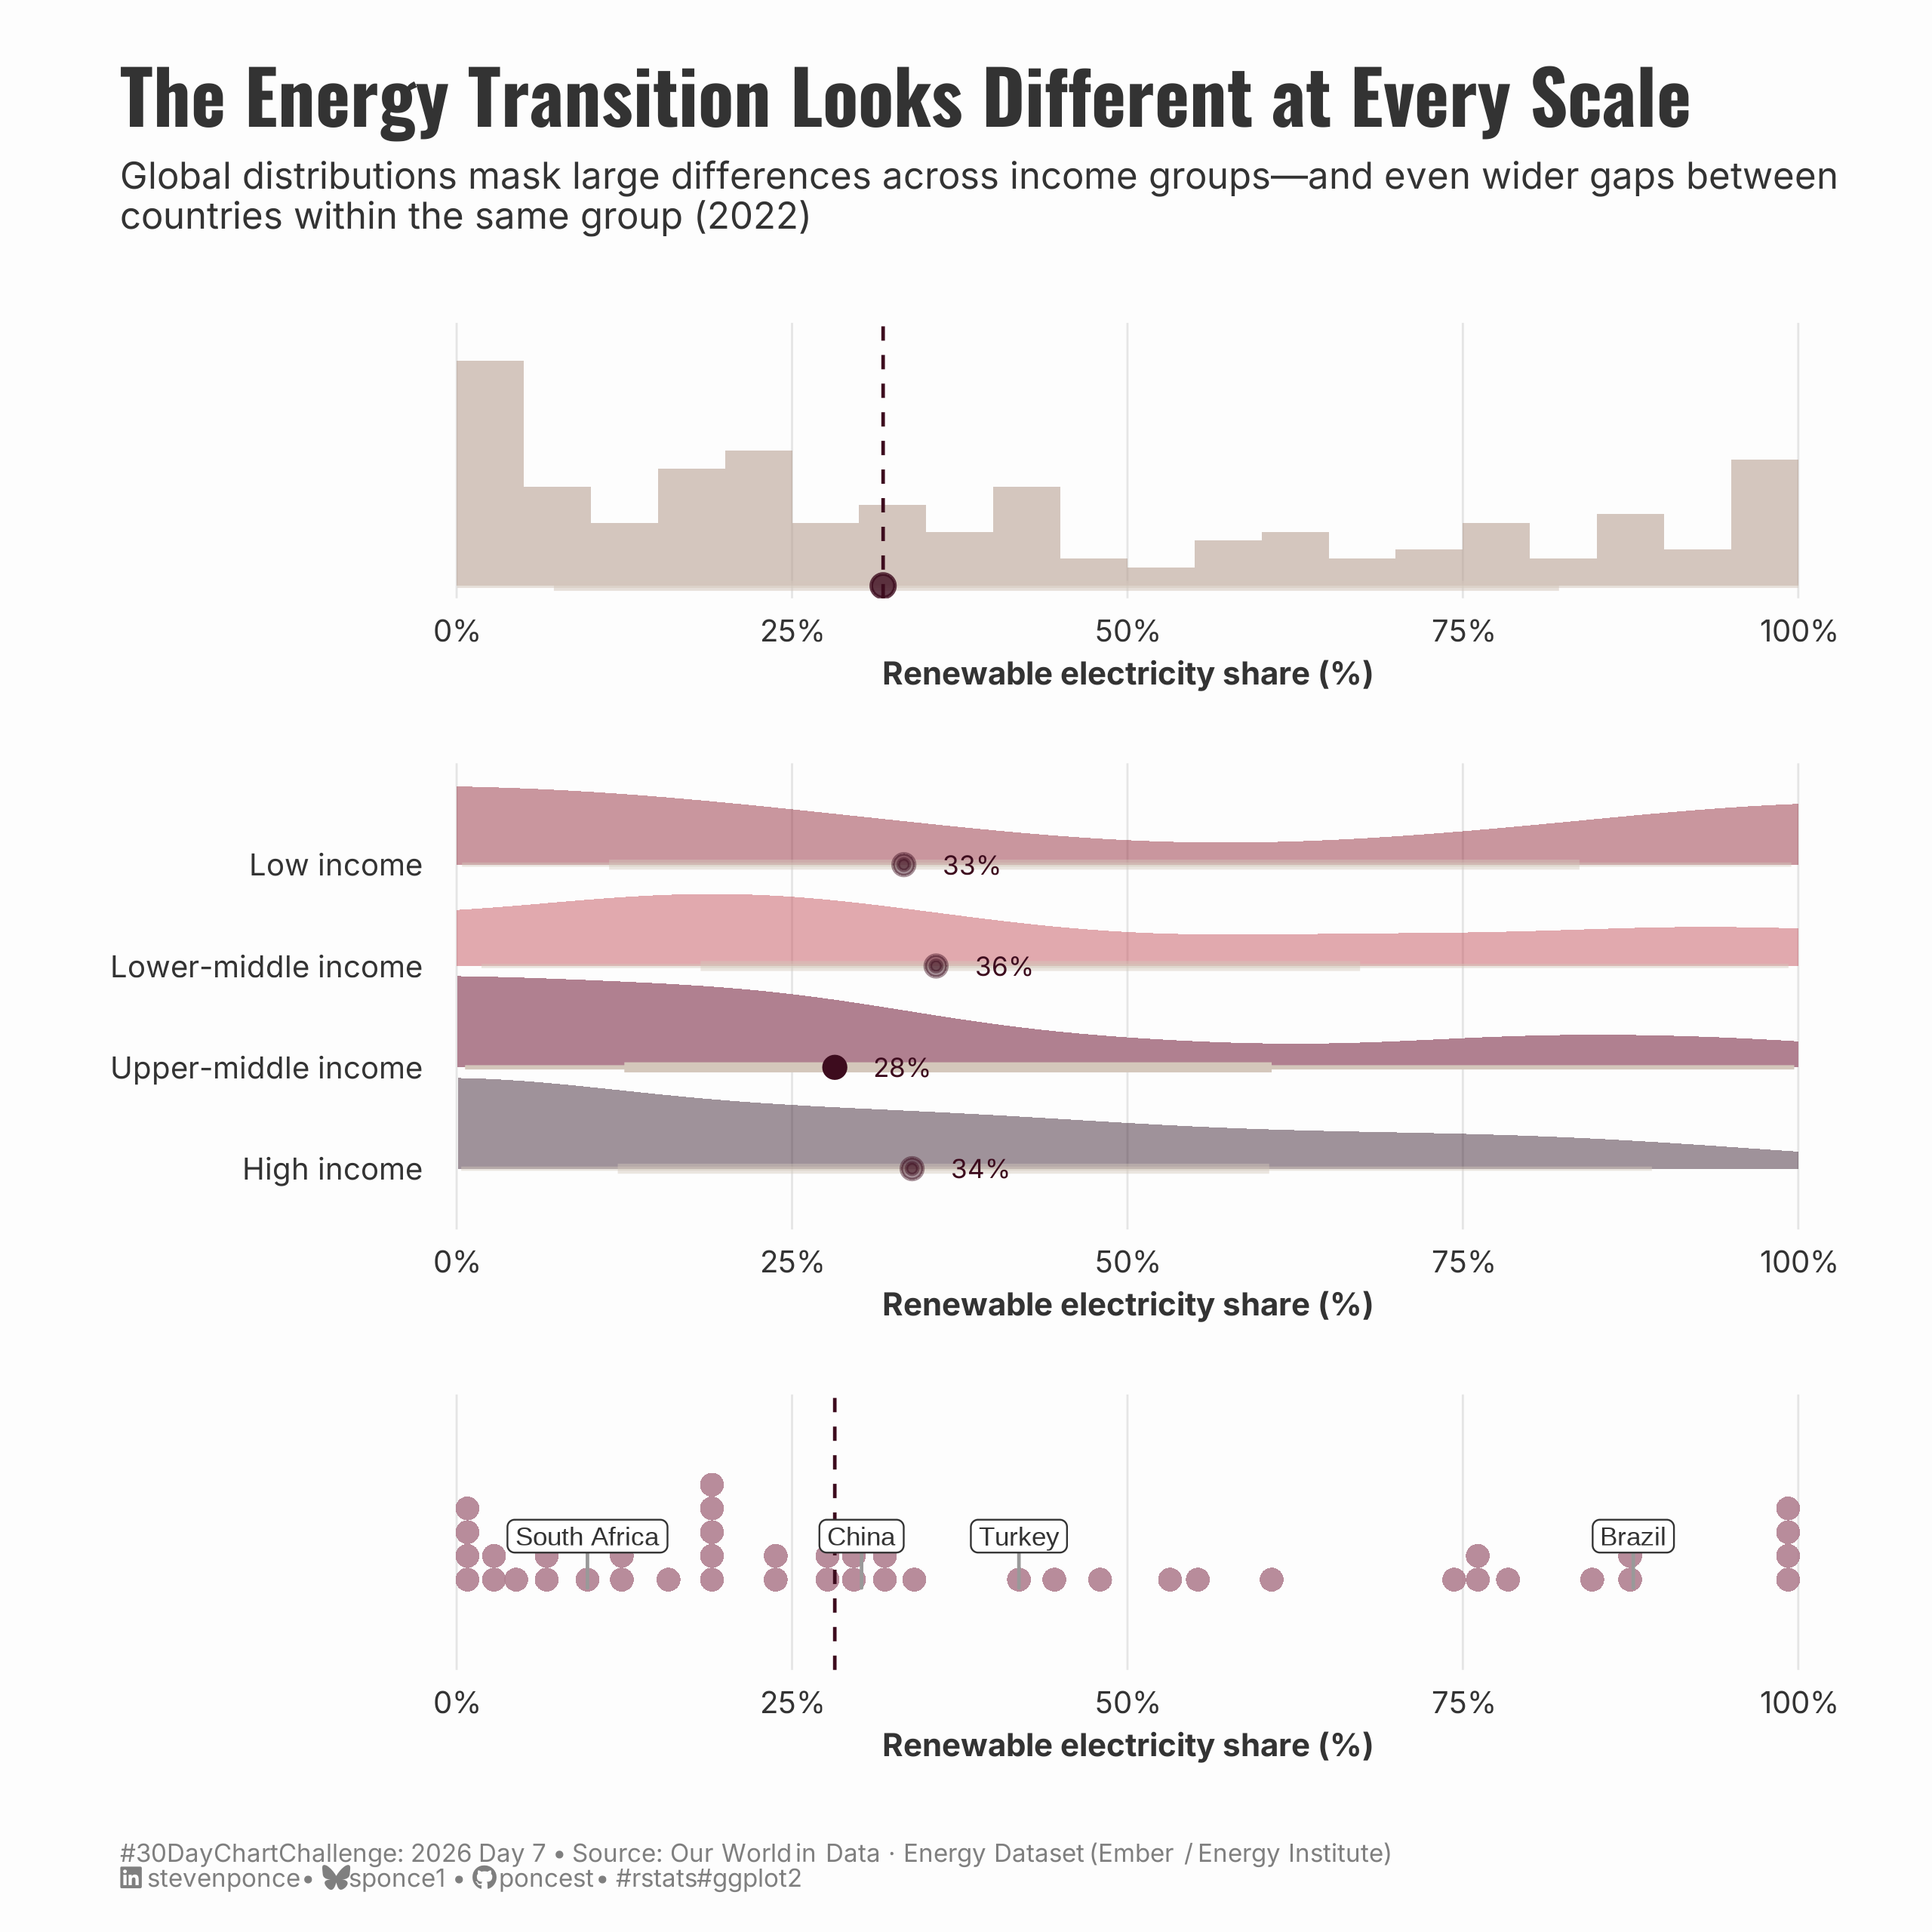
subtitle: "Global distributions mask large differences across income groups—and even wider gaps between countries within the same group (2022)"
description: "Renewable electricity share varies widely across countries—but global averages hide the real story. This multiscale distribution chart zooms from a global histogram to income-group density slabs to a country-level dot plot of upper-middle income nations, revealing that the energy transition is most uneven precisely where it matters most. Built with ggdist and patchwork in R."
date: "2026-04-07"
author:
- name: "Steven Ponce"
url: "https://stevenponce.netlify.app"
citation:
url: "https://stevenponce.netlify.app/data_visualizations/30DayChartChallenge/2026/30dcc_2026_07.html"
categories: ["30DayChartChallenge", "2026"]
tags: [
"30DayChartChallenge",
"Distributions",
"Multiscale",
"ggdist",
"patchwork",
"Energy",
"Renewable Energy",
"Electricity",
"Income Inequality",
"World Bank",
"Our World in Data",
"Small Multiples",
"Dot Plot",
"Density Plot",
"Histogram"
]
image: "thumbnails/30dcc_2026_07.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
{#fig-1}
### [**Steps to Create this Graphic**]{.mark}
#### [1. Load Packages & Setup]{.smallcaps}
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
pacman::p_load(
  tidyverse, ggtext, showtext, patchwork,
  janitor, scales, glue, ggdist, ggrepel, grid
  )
})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
  width  = 8,
  height = 8,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### [2. Read in the Data]{.smallcaps}
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

### |- RSF 2025 ----
energy_raw<- read_csv(
  here::here("data/30DayChartChallenge/2026/owid-energy-data.csv"),
  show_col_types = FALSE
)

# World Bank FY2024 income classification — hardcoded tribble
# Source: https://databank.worldbank.org/data/download/site-content/CLASS.xlsx
wb_income <- tribble(
  ~country,                          ~income_group,
  "Afghanistan",                     "Low income",
  "Albania",                         "Upper-middle income",
  "Algeria",                         "Lower-middle income",
  "Angola",                          "Lower-middle income",
  "Argentina",                       "Upper-middle income",
  "Armenia",                         "Upper-middle income",
  "Azerbaijan",                      "Upper-middle income",
  "Bangladesh",                      "Lower-middle income",
  "Belarus",                         "Upper-middle income",
  "Belize",                          "Upper-middle income",
  "Benin",                           "Low income",
  "Bhutan",                          "Lower-middle income",
  "Bolivia",                         "Lower-middle income",
  "Bosnia and Herzegovina",          "Upper-middle income",
  "Botswana",                        "Upper-middle income",
  "Brazil",                          "Upper-middle income",
  "Bulgaria",                        "Upper-middle income",
  "Cabo Verde",                      "Lower-middle income",
  "Cambodia",                        "Lower-middle income",
  "Cameroon",                        "Lower-middle income",
  "Central African Republic",        "Low income",
  "Chad",                            "Low income",
  "China",                           "Upper-middle income",
  "Colombia",                        "Upper-middle income",
  "Comoros",                         "Lower-middle income",
  "Congo",                           "Lower-middle income",
  "Costa Rica",                      "Upper-middle income",
  "Cote d'Ivoire",                   "Lower-middle income",
  "Cuba",                            "Upper-middle income",
  "Dem. Rep. Congo",                 "Low income",
  "Dominican Republic",              "Upper-middle income",
  "Ecuador",                         "Upper-middle income",
  "Egypt",                           "Lower-middle income",
  "El Salvador",                     "Lower-middle income",
  "Equatorial Guinea",               "Upper-middle income",
  "Eritrea",                         "Low income",
  "Eswatini",                        "Lower-middle income",
  "Ethiopia",                        "Low income",
  "Fiji",                            "Upper-middle income",
  "Gabon",                           "Upper-middle income",
  "Gambia",                          "Low income",
  "Georgia",                         "Upper-middle income",
  "Ghana",                           "Lower-middle income",
  "Guatemala",                       "Upper-middle income",
  "Guinea",                          "Low income",
  "Guinea-Bissau",                   "Low income",
  "Guyana",                          "Upper-middle income",
  "Haiti",                           "Low income",
  "Honduras",                        "Lower-middle income",
  "India",                           "Lower-middle income",
  "Indonesia",                       "Upper-middle income",
  "Iran",                            "Lower-middle income",
  "Iraq",                            "Upper-middle income",
  "Jamaica",                         "Upper-middle income",
  "Jordan",                          "Upper-middle income",
  "Kazakhstan",                      "Upper-middle income",
  "Kenya",                           "Lower-middle income",
  "Kyrgyzstan",                      "Lower-middle income",
  "Laos",                            "Lower-middle income",
  "Lebanon",                         "Lower-middle income",
  "Lesotho",                         "Lower-middle income",
  "Liberia",                         "Low income",
  "Libya",                           "Upper-middle income",
  "Madagascar",                      "Low income",
  "Malawi",                          "Low income",
  "Malaysia",                        "Upper-middle income",
  "Maldives",                        "Upper-middle income",
  "Mali",                            "Low income",
  "Marshall Islands",                "Upper-middle income",
  "Mauritania",                      "Lower-middle income",
  "Mauritius",                       "Upper-middle income",
  "Mexico",                          "Upper-middle income",
  "Micronesia",                      "Lower-middle income",
  "Mongolia",                        "Lower-middle income",
  "Montenegro",                      "Upper-middle income",
  "Morocco",                         "Lower-middle income",
  "Mozambique",                      "Low income",
  "Myanmar",                         "Lower-middle income",
  "Namibia",                         "Upper-middle income",
  "Nepal",                           "Lower-middle income",
  "Nicaragua",                       "Lower-middle income",
  "Niger",                           "Low income",
  "Nigeria",                         "Lower-middle income",
  "North Macedonia",                 "Upper-middle income",
  "Pakistan",                        "Lower-middle income",
  "Papua New Guinea",                "Lower-middle income",
  "Paraguay",                        "Upper-middle income",
  "Peru",                            "Upper-middle income",
  "Philippines",                     "Lower-middle income",
  "Rwanda",                          "Low income",
  "Samoa",                           "Lower-middle income",
  "Sao Tome and Principe",           "Lower-middle income",
  "Senegal",                         "Lower-middle income",
  "Serbia",                          "Upper-middle income",
  "Sierra Leone",                    "Low income",
  "Solomon Islands",                 "Lower-middle income",
  "Somalia",                         "Low income",
  "South Africa",                    "Upper-middle income",
  "South Sudan",                     "Low income",
  "Sri Lanka",                       "Lower-middle income",
  "Sudan",                           "Low income",
  "Suriname",                        "Upper-middle income",
  "Syrian Arab Republic",            "Low income",
  "Tajikistan",                      "Lower-middle income",
  "Tanzania",                        "Low income",
  "Thailand",                        "Upper-middle income",
  "Timor-Leste",                     "Lower-middle income",
  "Togo",                            "Low income",
  "Tonga",                           "Upper-middle income",
  "Tunisia",                         "Lower-middle income",
  "Turkey",                          "Upper-middle income",
  "Turkmenistan",                    "Upper-middle income",
  "Tuvalu",                          "Upper-middle income",
  "Uganda",                          "Low income",
  "Ukraine",                         "Lower-middle income",
  "Uzbekistan",                      "Lower-middle income",
  "Vanuatu",                         "Lower-middle income",
  "Venezuela",                       "Upper-middle income",
  "Vietnam",                         "Lower-middle income",
  "West Bank and Gaza",              "Lower-middle income",
  "Yemen",                           "Low income",
  "Zambia",                          "Lower-middle income",
  "Zimbabwe",                        "Lower-middle income",
  # High income
  "Australia",                       "High income",
  "Austria",                         "High income",
  "Bahrain",                         "High income",
  "Belgium",                         "High income",
  "Canada",                          "High income",
  "Chile",                           "High income",
  "Croatia",                         "High income",
  "Cyprus",                          "High income",
  "Czech Republic",                  "High income",
  "Denmark",                         "High income",
  "Estonia",                         "High income",
  "Finland",                         "High income",
  "France",                          "High income",
  "Germany",                         "High income",
  "Greece",                          "High income",
  "Hong Kong",                       "High income",
  "Hungary",                         "High income",
  "Iceland",                         "High income",
  "Ireland",                         "High income",
  "Israel",                          "High income",
  "Italy",                           "High income",
  "Japan",                           "High income",
  "Kuwait",                          "High income",
  "Latvia",                          "High income",
  "Lithuania",                       "High income",
  "Luxembourg",                      "High income",
  "Malta",                           "High income",
  "Netherlands",                     "High income",
  "New Zealand",                     "High income",
  "Norway",                          "High income",
  "Oman",                            "High income",
  "Poland",                          "High income",
  "Portugal",                        "High income",
  "Qatar",                           "High income",
  "Romania",                         "High income",
  "Saudi Arabia",                    "High income",
  "Singapore",                       "High income",
  "Slovakia",                        "High income",
  "Slovenia",                        "High income",
  "South Korea",                     "High income",
  "Spain",                           "High income",
  "Sweden",                          "High income",
  "Switzerland",                     "High income",
  "Taiwan",                          "High income",
  "Trinidad and Tobago",             "High income",
  "United Arab Emirates",            "High income",
  "United Kingdom",                  "High income",
  "United States",                   "High income",
  "Uruguay",                         "High income"
)
```
#### [3. Examine the Data]{.smallcaps}
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(energy_raw)
```
#### [4. Tidy Data]{.smallcaps}
```{r}
#| label: tidy
#| warning: false

### |- filter to 2022, countries only, join income classification ----
energy_2022 <- energy_raw |>
  filter(
    year == 2022,
    !country %in% c(
      "World", "Asia", "Europe", "Africa", "North America",
      "South America", "Oceania", "European Union (27)",
      "High-income countries", "Low-income countries",
      "Lower-middle-income countries", "Upper-middle-income countries",
      "OECD (Ember)", "Non-OECD (Ember)"
    )
  ) |>
  select(country, year, renewables_share_elec) |>
  filter(!is.na(renewables_share_elec)) |>
  left_join(wb_income, by = "country")

### |- panel 1: global distribution (all countries with income classification) ----
p1_data <- energy_2022 |>
  filter(!is.na(income_group)) |>
  mutate(group = "Global")

### |- panel 2: by income group ----
income_order <- c(
  "Low income",
  "Lower-middle income",
  "Upper-middle income",
  "High income"
)

p2_data <- energy_2022 |>
  filter(!is.na(income_group)) |>
  mutate(income_group = factor(income_group, levels = income_order))

### |- panel 3: upper-middle income countries, labeled highlights ----
label_countries <- c("Brazil", "South Africa", "China", "Turkey")

p3_data <- energy_2022 |>
  filter(income_group == "Upper-middle income") |>
  arrange(renewables_share_elec) |>
  mutate(
    country_label = if_else(country %in% label_countries, country, NA_character_),
    rank          = row_number()
  )

### |- compute medians for annotations ----
group_medians <- p2_data |>
  group_by(income_group) |>
  summarise(
    median_val = median(renewables_share_elec, na.rm = TRUE),
    .groups = "drop"
  )

global_median <- median(p1_data$renewables_share_elec, na.rm = TRUE)
p3_median <- median(p3_data$renewables_share_elec, na.rm = TRUE)
```
#### [5. Visualization Parameters]{.smallcaps}
```{r}
#| label: params
#| include: true
#| warning: false

### |- plot aesthetics ----
colors <- get_theme_colors(
  palette = list(
    "Low income"           = "#8B1A2A",
    "Lower-middle income"  = "#C0434E",
    "Upper-middle income"  = "#B08090",
    "High income"          = "#2E1122",
    "iqr_band"             = "#D4C7BB",
    "median_dot_fill"      = "#FFFFFF",
    "median_dot_stroke"    = "#3D0C1E",
    "median_label"         = "#3D0C1E",
    "label_text"           = "gray20",
    "global_ref"           = "#B29A8B"
  )
)

### |- titles and caption ----
title_text <- "The Energy Transition Looks Different at Every Scale"

subtitle_text <- "Global distributions mask large differences across income groups—and even wider gaps between\ncountries within the same group (2022)"

caption_text <- create_dcc_caption(
  dcc_year    = 2026,
  dcc_day     = 07,
  source_text = "Our World in Data · Energy Dataset (Ember / Energy Institute)"
)

### |- fonts ----
setup_fonts()
fonts <- get_font_families()

### |- base theme ----
base_theme <- create_base_theme(colors)

weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    plot.background = element_rect(fill = colors$palette$bg, color = NA),
    panel.background = element_rect(fill = colors$palette$bg, color = NA),
    panel.grid.major.x = element_line(color = "gray90", linewidth = 0.3),
    panel.grid.major.y = element_blank(),
    panel.grid.minor = element_blank(),
    axis.ticks = element_blank(),
    axis.text = element_text(
      family = fonts$body,
      size   = 9,
      color  = colors$palette$label_text
    ),
    axis.title = element_text(
      family = fonts$body,
      size   = 9.5,
      color  = colors$palette$label_text
    ),
    strip.text = element_blank(),
    panel.spacing = unit(12, "pt"),
    plot.margin = margin(10, 16, 10, 16)
  )
)

theme_set(weekly_theme)
```
#### [6. Plot]{.smallcaps}
```{r}
#| label: plot
#| warning: false

### |- panel 1: global histinterval ----
p1 <- ggplot(p1_data, aes(x = renewables_share_elec, y = 0)) +
  stat_histinterval(
    fill           = colors$palette$global_ref,
    slab_color     = NA,
    alpha          = 0.55,
    point_color    = colors$palette$median_dot_stroke,
    interval_color = colors$palette$iqr_band,
    point_size     = 2.8,
    breaks         = 20
  ) +
  geom_vline(
    xintercept = global_median,
    linetype   = "dashed",
    color      = colors$palette$median_dot_stroke,
    linewidth  = 0.5
  ) +
  annotate(
    "text",
    x      = global_median + 2,
    y      = Inf,
    label  = glue("Median: {round(global_median, 1)}%"),
    hjust  = 0,
    vjust  = 1.4,
    size   = 3,
    family = fonts$body,
    color  = colors$palette$median_label
  ) +
  annotate(
    "text",
    x        = 97,
    y        = Inf,
    label    = "GLOBAL",
    hjust    = 1,
    vjust    = 1.4,
    size     = 3.2,
    fontface = "bold",
    family   = fonts$body,
    color    = colors$palette$label_text
  ) +
  scale_x_continuous(
    limits = c(0, 100),
    breaks = c(0, 25, 50, 75, 100),
    labels = label_percent(scale = 1, suffix = "%"),
    expand = c(0.01, 0)
  ) +
  labs(
    x = "Renewable electricity share (%)",
    y = NULL
  ) +
  theme(
    axis.text.y  = element_blank(),
    axis.title.y = element_blank()
  )

### |- panel 2: by income group — halfeye ----
p2 <- ggplot(p2_data, aes(x = renewables_share_elec, y = fct_rev(income_group))) +
  stat_halfeye(
    aes(
      fill  = income_group,
      alpha = income_group == "Upper-middle income"
    ),
    .width = c(0.5, 0.9),
    point_color = colors$palette$median_dot_stroke,
    point_fill = colors$palette$median_dot_fill,
    interval_color = colors$palette$iqr_band,
    slab_color = NA,
    normalize = "all",
    scale = 0.9
  ) +
  scale_fill_manual(
    values = c(
      "Low income"           = colors$palette$`Low income`,
      "Lower-middle income"  = colors$palette$`Lower-middle income`,
      "Upper-middle income"  = colors$palette$`Upper-middle income`,
      "High income"          = colors$palette$`High income`
    )
  ) +
  scale_alpha_manual(
    values = c("TRUE" = 1, "FALSE" = 0.45),
    guide  = "none"
  ) +
  geom_text(
    data = group_medians,
    aes(
      x = median_val + 3,
      y = fct_rev(income_group),
      label = glue("{round(median_val, 0)}%")
    ),
    hjust = 0,
    size = 2.8,
    family = fonts$body,
    color = colors$palette$median_label,
    inherit.aes = FALSE
  ) +
  annotate(
    "text",
    x        = 95,
    y        = 4.45,
    label    = "BY INCOME GROUP",
    hjust    = 1,
    size     = 3.2,
    fontface = "bold",
    family   = fonts$body,
    color    = colors$palette$label_text
  ) +
  scale_x_continuous(
    limits = c(0, 100),
    breaks = c(0, 25, 50, 75, 100),
    labels = label_percent(scale = 1, suffix = "%"),
    expand = c(0.01, 0)
  ) +
  labs(
    x = "Renewable electricity share (%)",
    y = NULL
  ) +
  guides(fill = "none")

### |- panel 3: upper-middle income — quantile dot plot ----
p3 <- ggplot(p3_data, aes(x = renewables_share_elec, y = 0)) +
  stat_dots(
    fill   = colors$palette$`Upper-middle income`,
    color  = NA,
    alpha  = 0.9,
    size   = 2.4,
    layout = "bin"
  ) +
  geom_vline(
    xintercept = p3_median,
    linetype   = "dashed",
    color      = colors$palette$median_dot_stroke,
    linewidth  = 0.5
  ) +
  annotate(
    "text",
    x      = p3_median + 2,
    y      = 1.18,
    label  = glue("Median: {round(p3_median, 1)}%"),
    hjust  = 0,
    size   = 2.8,
    family = fonts$body,
    color  = colors$palette$median_label
  ) +
  geom_label_repel(
    data = p3_data |> filter(!is.na(country_label)),
    aes(x = renewables_share_elec, y = 0, label = country_label),
    nudge_y = 0.42,
    size = 2.8,
    family = fonts$body,
    color = colors$palette$label_text,
    fill = colors$palette$bg,
    label.size = 0.2,
    label.padding = unit(0.15, "lines"),
    min.segment.length = 0.3,
    segment.color = "gray60",
    inherit.aes = FALSE
  ) +
  annotate(
    "text",
    x        = 95,
    y        = 1.1,
    label    = "UPPER-MIDDLE INCOME",
    hjust    = 1,
    size     = 3.2,
    fontface = "bold",
    family   = fonts$body,
    color    = colors$palette$label_text
  ) +
  scale_x_continuous(
    limits = c(0, 100),
    breaks = c(0, 25, 50, 75, 100),
    labels = label_percent(scale = 1, suffix = "%"),
    expand = c(0.01, 0)
  ) +
  scale_y_continuous(
    limits = c(-0.5, 1.4)
  ) +
  labs(
    x = "Renewable electricity share (%)",
    y = NULL
  ) +
  theme(
    axis.text.y  = element_blank(),
    axis.title.y = element_blank()
  )

### |- combined plots ----
combined_plots <- p1 / p2 / p3 +
  plot_layout(heights = c(1.3, 2.2, 1.3)) +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        family = fonts$title,
        face   = "bold",
        size   = 22,
        color  = colors$palette$label_text,
        margin = margin(b = 6)
      ),
      plot.subtitle = element_text(
        family = fonts$body,
        size   = 11,
        color  = colors$palette$label_text,
        margin = margin(b = 16)
      ),
      plot.caption = element_markdown(
        family = fonts$body,
        size   = 7.5,
        color  = "gray50",
        margin = margin(t = 12),
        hjust = 0,
      ),
      plot.background = element_rect(fill = colors$palette$bg, color = NA),
      plot.margin = margin(20, 20, 12, 20)
    )
  )
```
#### [7. Save]{.smallcaps}
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  combined_plots,
  type = "30daychartchallenge",
  year = 2026,
  day = 07,
  width = 8,
  height = 8
  )
```
#### [8. Session Info]{.smallcaps}
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### [9. GitHub Repository]{.smallcaps}
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`30dcc_2026_07.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2026/30dcc_2026_07.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### [10. References]{.smallcaps}
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- Our World in Data. (2024). *Energy Dataset*.
Retrieved April 2026 from https://github.com/owid/energy-data
- Ember & Energy Institute. (2024). *Yearly Electricity Data*.
Retrieved April 2026 from https://ember-climate.org/data/data-tools/data-explorer/
- World Bank. (2024). *World Bank Country and Lending Groups — FY2024 Income Classification*.
Retrieved April 2026 from https://databank.worldbank.org/data/download/site-content/CLASS.xlsx
:::
#### [11. Custom Functions Documentation]{.smallcaps}
::: {.callout-note collapse="true"}
##### 📦 Custom Helper Functions
This analysis uses custom functions from my personal module library for efficiency and consistency across projects.
**Functions Used:**
- **`fonts.R`**: `setup_fonts()`, `get_font_families()` - Font management with showtext
- **`social_icons.R`**: `create_social_caption()` - Generates formatted social media captions
- **`image_utils.R`**: `save_plot()` - Consistent plot saving with naming conventions
- **`base_theme.R`**: `create_base_theme()`, `extend_weekly_theme()`, `get_theme_colors()` - Custom ggplot2 themes
**Why custom functions?**\
These utilities standardize theming, fonts, and output across all my data visualizations. The core analysis (data tidying and visualization logic) uses only standard tidyverse packages.
**Source Code:**\
View all custom functions → [GitHub: R/utils](https://github.com/poncest/personal-website/tree/master/R)
:::
