---
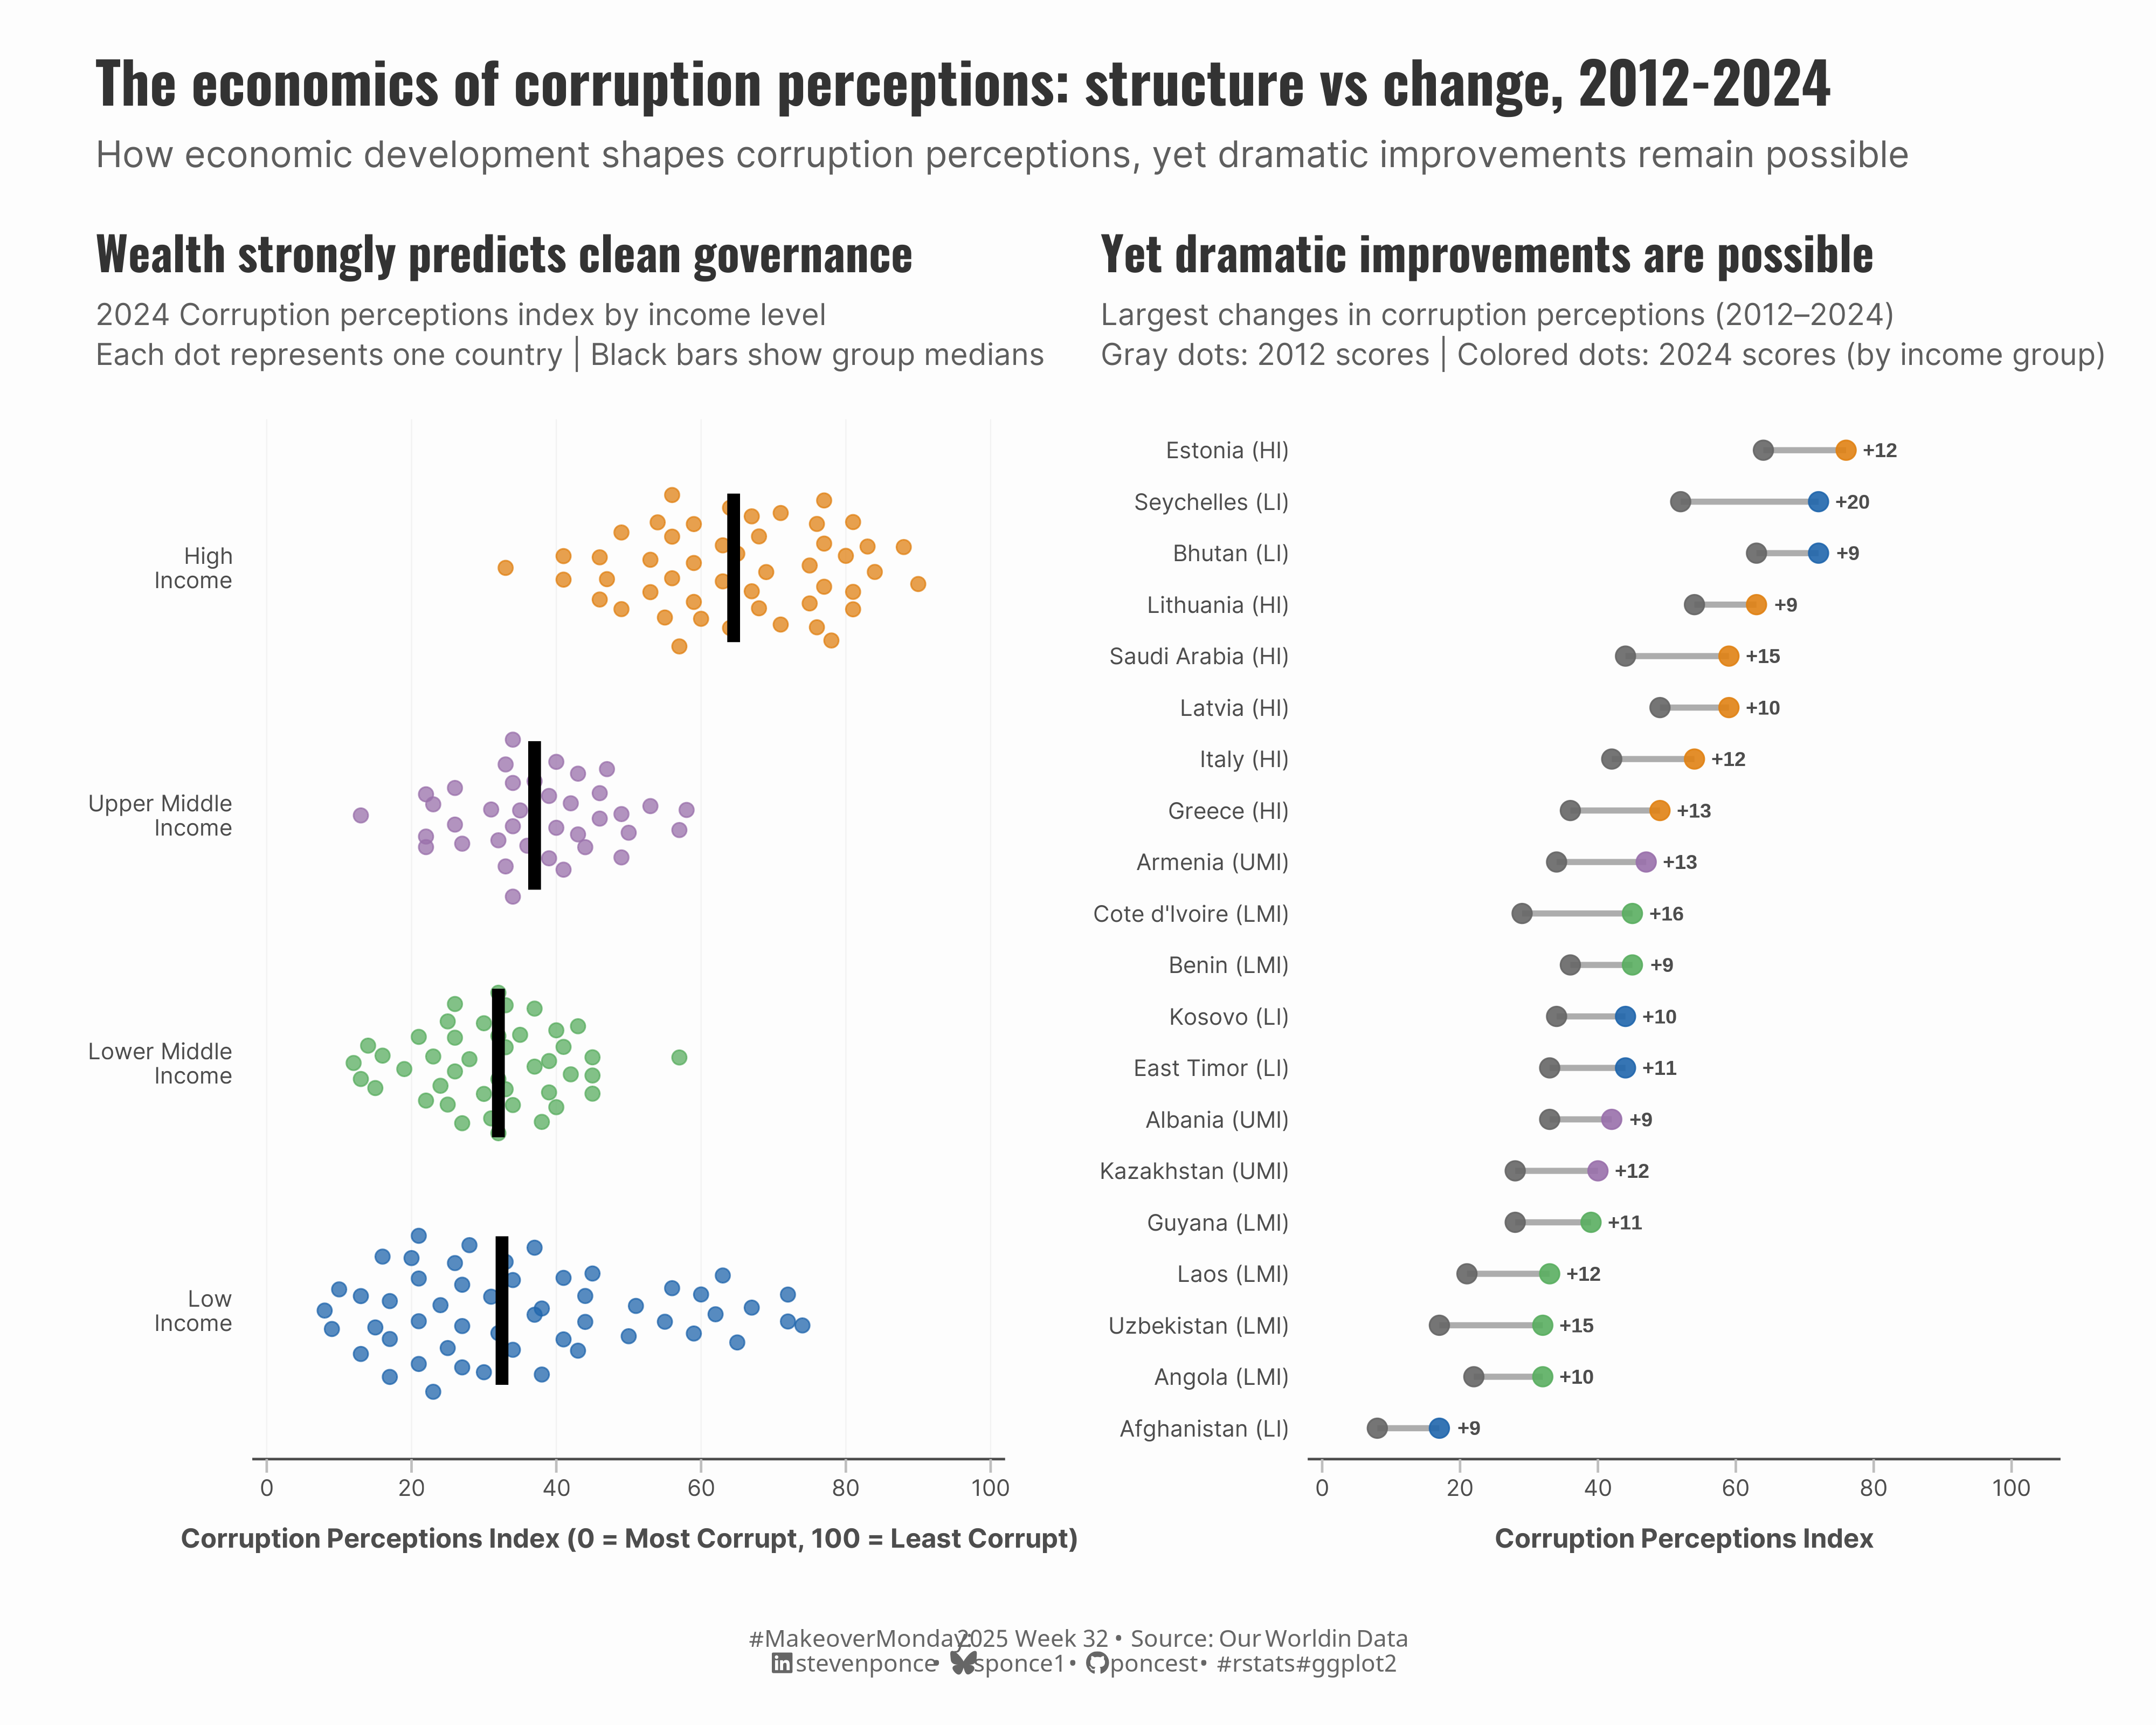
title: "The economics of corruption perceptions: structure vs change, 2012-2024"
subtitle: "How economic development shapes corruption perceptions, yet dramatic improvements remain possible"
description: "A comprehensive analysis of global corruption perceptions revealing how economic development strongly predicts governance quality, while individual countries can still achieve dramatic improvements. Using World Bank income classifications and 13 years of Transparency International data, this Makeover Monday project transforms a static table into an engaging dual-chart story showing both structural patterns and exceptional cases of anti-corruption progress across 180+ countries."
author: "Steven Ponce"
date: "2025-08-05"
categories: ["MakeoverMonday", "2025"]
tags: [
"corruption-perceptions-index",
"transparency-international",
"world-bank-income-groups",
"governance-analysis",
"economic-development",
"beeswarm-plot",
"dumbbell-chart",
"ggplot2",
"data-transformation",
"comparative-analysis",
"global-governance",
"anti-corruption",
"policy-insights"
]
image: "thumbnails/mm_2025_32.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
```{r}
#| label: setup-links
#| include: false
# CENTRALIZED LINK MANAGEMENT
## Project-specific info
current_year <- 2025
current_week <- 32
project_file <- "mm_2025_32.qmd"
project_image <- "mm_2025_32.png"
## Data Sources
data_main <- "https://data.world/makeovermonday/corruption"
data_secondary <- "https://ourworldindata.org/grapher/ti-corruption-perception-index?tab=table&time=earliest..2024&country=~NZL"
## Repository Links
repo_main <- "https://github.com/poncest/personal-website/"
repo_file <- paste0("https://github.com/poncest/personal-website/blob/master/data_visualizations/MakeoverMonday/", current_year, "/", project_file)
## External Resources/Images
chart_original <- "https://raw.githubusercontent.com/poncest/MakeoverMonday/refs/heads/master/2025/Week_32/original_chart.png"
## Organization/Platform Links
org_primary <- "https://ourworldindata.org/grapher/ti-corruption-perception-index?tab=table&time=earliest..2024&country=~NZL"
org_secondary <- "https://ourworldindata.org/"
# Helper function to create markdown links
create_link <- function(text, url) {
paste0("[", text, "](", url, ")")
}
# Helper function for citation-style links
create_citation_link <- function(text, url, title = NULL) {
if (is.null(title)) {
paste0("[", text, "](", url, ")")
} else {
paste0("[", text, "](", url, ' "', title, '")')
}
}
```
### Original
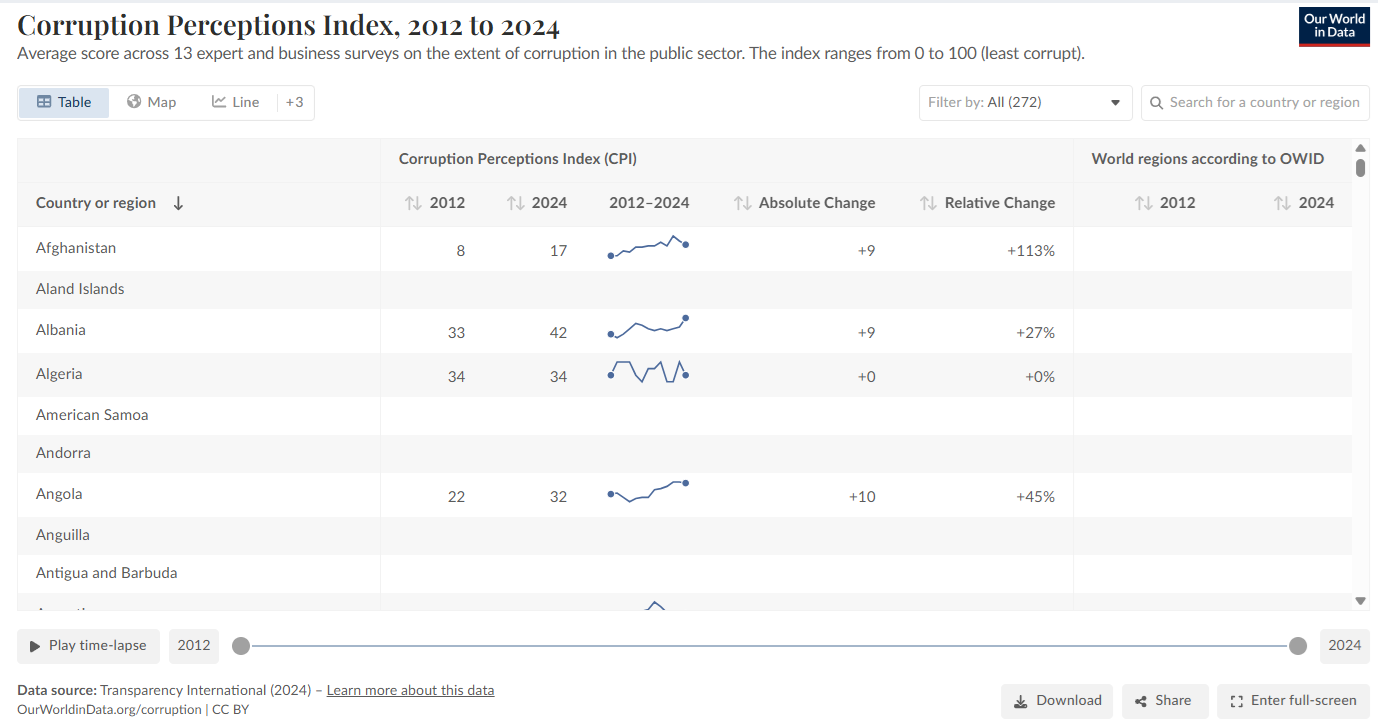
The original visualization **Corruption Perceptions Index (CPI)** comes from `r create_link("Our orld in Data", data_secondary)`
<!--  -->
### Makeover
{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
  if (!require("pacman")) install.packages("pacman")
  pacman::p_load(
tidyverse,      # Easily Install and Load the 'Tidyverse'
  ggtext,         # Improved Text Rendering Support for 'ggplot2'
  showtext,       # Using Fonts More Easily in R Graphs
  scales,         # Scale Functions for Visualization
  glue,           # Interpreted String Literals
  ggbeeswarm,     # Categorical Scatter (Violin Point) Plots
  patchwork       # The Composer of Plots
  )
})

### |- figure size ----
camcorder::gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  =  12,
    height =  10,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
#|
cpi_raw <- readxl::read_excel(
  here::here('data/MakeoverMonday/2025/Corruption Perception Index.xlsx')) |>
  janitor::clean_names()
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(cpi_raw)
skimr::skim(cpi_raw)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

# Data cleaning and preparation
cpi_clean <- cpi_raw |>
  filter(!is.na(corruption_perceptions_index)) |>
  filter(year >= 2012, year <= 2024)

# Helper function to assign World Bank income groups (FY2024 classification)
create_income_groups <- function(data) {
  data |>
    mutate(
      income_group = case_when(
        # ---- High Income Countries (based on WB FY2024) ----
        code %in% c(
          # Western Europe & North America
          "DNK", "NOR", "SWE", "CHE", "SGP", "NZL", "FIN", "DEU", "NLD",
          "LUX", "AUT", "AUS", "CAN", "USA", "GBR", "BEL", "JPN", "FRA",
          "IRL", "ISL", "ESP", "ITA", "KOR", "ISR",
          # Eastern Europe (High Income)
          "SVN", "CZE", "EST", "SVK", "PRT", "POL", "LTU", "LVA", "HUN",
          "HRV", "GRC", "CYP", "MLT",
          # Other High Income
          "URY", "CHL", "PAN", "ARE", "QAT", "KWT", "BHR", "OMN",
          "SAU", "BRB", "TTO"
        ) ~ "High\nIncome",

        # ---- Upper Middle Income ----
        code %in% c(
          # Latin America
          "ARG", "MYS", "THA", "MEX", "CRI", "BRA", "COL", "PER", "ECU", "DOM",
          # Europe & Central Asia
          "ROU", "BGR", "TUR", "MNE", "SRB", "MKD", "ALB", "BIH", "ARM", "GEO",
          "AZE", "KAZ", "BLR",
          # Other Upper Middle
          "CHN", "RUS", "ZAF", "BWA", "NAM", "JAM", "LBN", "JOR", "TUN",
          "DZA", "IRQ", "IRN", "LBY", "GAB"
        ) ~ "Upper Middle\nIncome",

        # ---- Lower Middle Income ----
        code %in% c(
          # South & East Asia
          "IND", "IDN", "PHL", "VNM", "BGD", "PAK", "LKA", "NPL", "KHM",
          "LAO", "MMR", "MNG",
          # Europe & Central Asia
          "UZB", "KGZ", "TJK", "UKR", "MDA",
          # Middle East & North Africa
          "MAR", "EGY", "PSE", "SYR", "YEM", "SDN", "DJI",
          # Latin America
          "BOL", "PRY", "GTM", "HND", "NIC", "SLV", "GUY", "SUR",
          # Sub-Saharan Africa
          "KEN", "TZA", "UGA", "RWA", "ZMB", "AGO", "CIV", "GHA",
          "CMR", "SEN", "NGA", "BEN"
        ) ~ "Lower Middle\nIncome",

        # ---- Default: Low Income ----
        TRUE ~ "Low\nIncome"
      ),
      # Create ordered factor for logical display
      income_group = factor(
        income_group,
        levels = c("Low\nIncome", "Lower Middle\nIncome",
                   "Upper Middle\nIncome", "High\nIncome"),
        ordered = TRUE
      )
    )
}

# Apply income classification
cpi_with_income <- cpi_clean |>
  create_income_groups()

# Calculate country trends for dumbbell chart
country_trends <- cpi_with_income |>
  group_by(entity) |>
  filter(any(year == 2012) & any(year == 2024)) |>
  summarise(
    trend = corruption_perceptions_index[year == 2024][1] - corruption_perceptions_index[year == 2012][1],
    latest_score = corruption_perceptions_index[year == 2024][1],
    earliest_score = corruption_perceptions_index[year == 2012][1],
    income_group = first(income_group),
    .groups = "drop"
  ) |>
  filter(!is.na(trend), !is.na(latest_score), !is.na(earliest_score))

# Beeswarm plot data
latest_data_income <- cpi_with_income |>
  filter(year == 2024) |>
  arrange(desc(corruption_perceptions_index))

# Dumbbell plot data
biggest_movers <- country_trends |>
  filter(abs(trend) >= 5) |>
  arrange(desc(trend)) |>
  slice_head(n = 20) |>
  mutate(
    income_abbrev = case_when(
      income_group == "High\nIncome" ~ "HI",
      income_group == "Upper Middle\nIncome" ~ "UMI",
      income_group == "Lower Middle\nIncome" ~ "LMI",
      income_group == "Low\nIncome" ~ "LI",
      TRUE ~ "Unknown"
    ),
    entity_with_income = glue("{entity} ({income_abbrev})"),
    entity_short = if_else(
      nchar(entity_with_income) > 25,
      glue("{str_sub(entity, 1, 18)}... ({income_abbrev})"),
      entity_with_income
    ),
    entity_short = fct_reorder(entity_short, latest_score)
  )
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
# Get base colors with custom palette
colors <- get_theme_colors(palette = list(
  "Low\nIncome" = "#2166AC",
  "Lower Middle\nIncome" = "#5AAE61",
  "Upper Middle\nIncome" = "#9970AB",
  "High\nIncome" = "#E08214"
))

### |-  titles and caption ----
title_text <- str_glue("The economics of corruption perceptions: structure vs change, 2012-2024")

subtitle_text <- str_glue(
  "How economic development shapes corruption perceptions, yet dramatic improvements remain possible"
)

# Create caption
caption_text <- create_mm_caption(
  mm_year = current_year,
  mm_week = current_week,
  source_text = paste0("Our World in Data")
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    plot.title = element_text(
      size = rel(1.4), family = fonts$title, face = "bold",
      color = colors$title, lineheight = 1.1, hjust = 0,
      margin = margin(t = 5, b = 10)
    ),
    plot.subtitle = element_text(
      size = rel(0.9), hjust = 0, family = fonts$subtitle,
      color = alpha(colors$subtitle, 0.9), lineheight = 1.1,
      margin = margin(t = 0, b = 20)
    ),

    # Legend formatting
    legend.position = "plot",
    legend.box.margin = margin(b = 10),
    legend.margin = margin(b = 5),
    legend.title = element_text(face = "bold"),

    # Axis formatting
    axis.ticks.y = element_blank(),
    axis.ticks.x = element_line(color = "gray", linewidth = 0.5),
    axis.ticks.length = unit(0.2, "cm"),
    axis.title.x = element_text(
      face = "bold", size = rel(0.85),
      margin = margin(t = 10)
    ),
    axis.title.y = element_text(
      face = "bold", size = rel(0.85),
      margin = margin(r = 10)
    ),
    axis.text.x = element_text(
      size = rel(0.85), family = fonts$subtitle,
      color = colors$text
    ),
    axis.text.y = element_text(
      size = rel(0.85), family = fonts$subtitle,
      color = colors$text
    ),

    # Grid lines
    panel.grid.major = element_line(color = "#ecf0f1", linewidth = 0.4),
    panel.grid.minor = element_blank(),

    # Margin
    plot.margin = margin(20, 20, 20, 20)
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |- P1  Income beeswarm plot----
beeswarm_plot <- ggplot(
  latest_data_income,
  aes(
    x = income_group, y = corruption_perceptions_index,
    color = income_group
  )
) +
  # Geoms
  geom_quasirandom(size = 2.5, alpha = 0.75, width = 0.35) +
  stat_summary(
    fun = median, geom = "crossbar", width = 0.6,
    color = "black", size = 1, alpha = 0.8
  ) +
  # Scales
  scale_color_manual(values = colors$palette, guide = "none") +
  scale_y_continuous(
    breaks = seq(0, 100, 20), limits = c(0, 100),
    expand = expansion(mult = c(0.02, 0.02))
  ) +
  coord_flip(clip = "off") +
  # Labs
  labs(
    title = "Wealth strongly predicts clean governance",
    subtitle = str_glue(
      "2024 Corruption perceptions index by income level\n",
      "Each dot represents one country | Black bars show group medians"
    ),
    x = NULL,
    y = "Corruption Perceptions Index (0 = Most Corrupt, 100 = Least Corrupt)",
  ) +
  # Theme
  theme(
    panel.grid.minor = element_blank(),
    panel.grid.major.y = element_blank(),
    panel.grid.major.x = element_line(color = "gray95", size = 0.25),
    axis.line.x = element_line(color = "gray30", size = 0.5),
  )
### |- P2  Dumbbell plot----
dumbbell_plot <- ggplot(biggest_movers, aes(y = entity_short)) +
  # Geoms
  geom_segment(aes(x = earliest_score, xend = latest_score),
               color = "gray60", size = 1.2, alpha = 0.8
  ) +
  geom_point(aes(x = earliest_score), color = "gray40", size = 3.5, alpha = 0.9) +
  geom_point(aes(x = latest_score, color = income_group), size = 3.5, alpha = 0.9) +
  geom_text(
    aes(
      x = pmax(earliest_score, latest_score) + 3,
      label = paste0(ifelse(trend > 0, "+", ""), round(trend))
    ),
    size = 3, fontface = "bold", color = "gray30", hjust = 0.1
  ) +
  # Scales
  scale_color_manual(values = colors$palette, guide = "none") +
  scale_x_continuous(
    breaks = seq(0, 100, 20), limits = c(0, 105),
    expand = expansion(mult = c(0.02, 0.02))
  ) +
  # Labs
  labs(
    title = "Yet dramatic improvements are possible",
    subtitle = str_glue(
      "Largest changes in corruption perceptions (2012–2024)\n",
      "Gray dots: 2012 scores | Colored dots: 2024 scores (by income group)"
    ),
    x = "Corruption Perceptions Index",
    y = NULL,
  ) +
  # Theme
  theme(
    panel.grid.minor = element_blank(),
    panel.grid.major = element_blank(),
    axis.line.x = element_line(color = "gray30", size = 0.5),
  )

### |-  combined plot ----
combined_plots <- beeswarm_plot | dumbbell_plot

combined_plots <- combined_plots +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        size = rel(1.7),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.1,
        margin = margin(t = 5, b = 5)
      ),
      plot.subtitle = element_text(
        size = rel(1.1),
        family = fonts$subtitle,
        color = alpha(colors$subtitle, 0.9),
        lineheight = 0.9,
        margin = margin(t = 5, b = 0)
      ),
      plot.caption = element_markdown(
        size = rel(0.70),
        family = fonts$caption,
        color = colors$caption,
        hjust = 0.5,
        margin = margin(t = 10)
      )
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  plot = combined_plots,
  type = "makeovermonday",
  year = current_year,
  week = current_week,
  width = 12.5,
  height = 10
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in `r create_link(project_file, repo_file)`.
For the full repository, `r create_link("click here", repo_main)`.
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data:
- Makeover Monday `r current_year` Week `r current_week`: `r create_link("Corruption Perceptions Index (CPI)", data_main)`
2. Article
- `r create_link("Corruption", data_secondary)`
:::