---
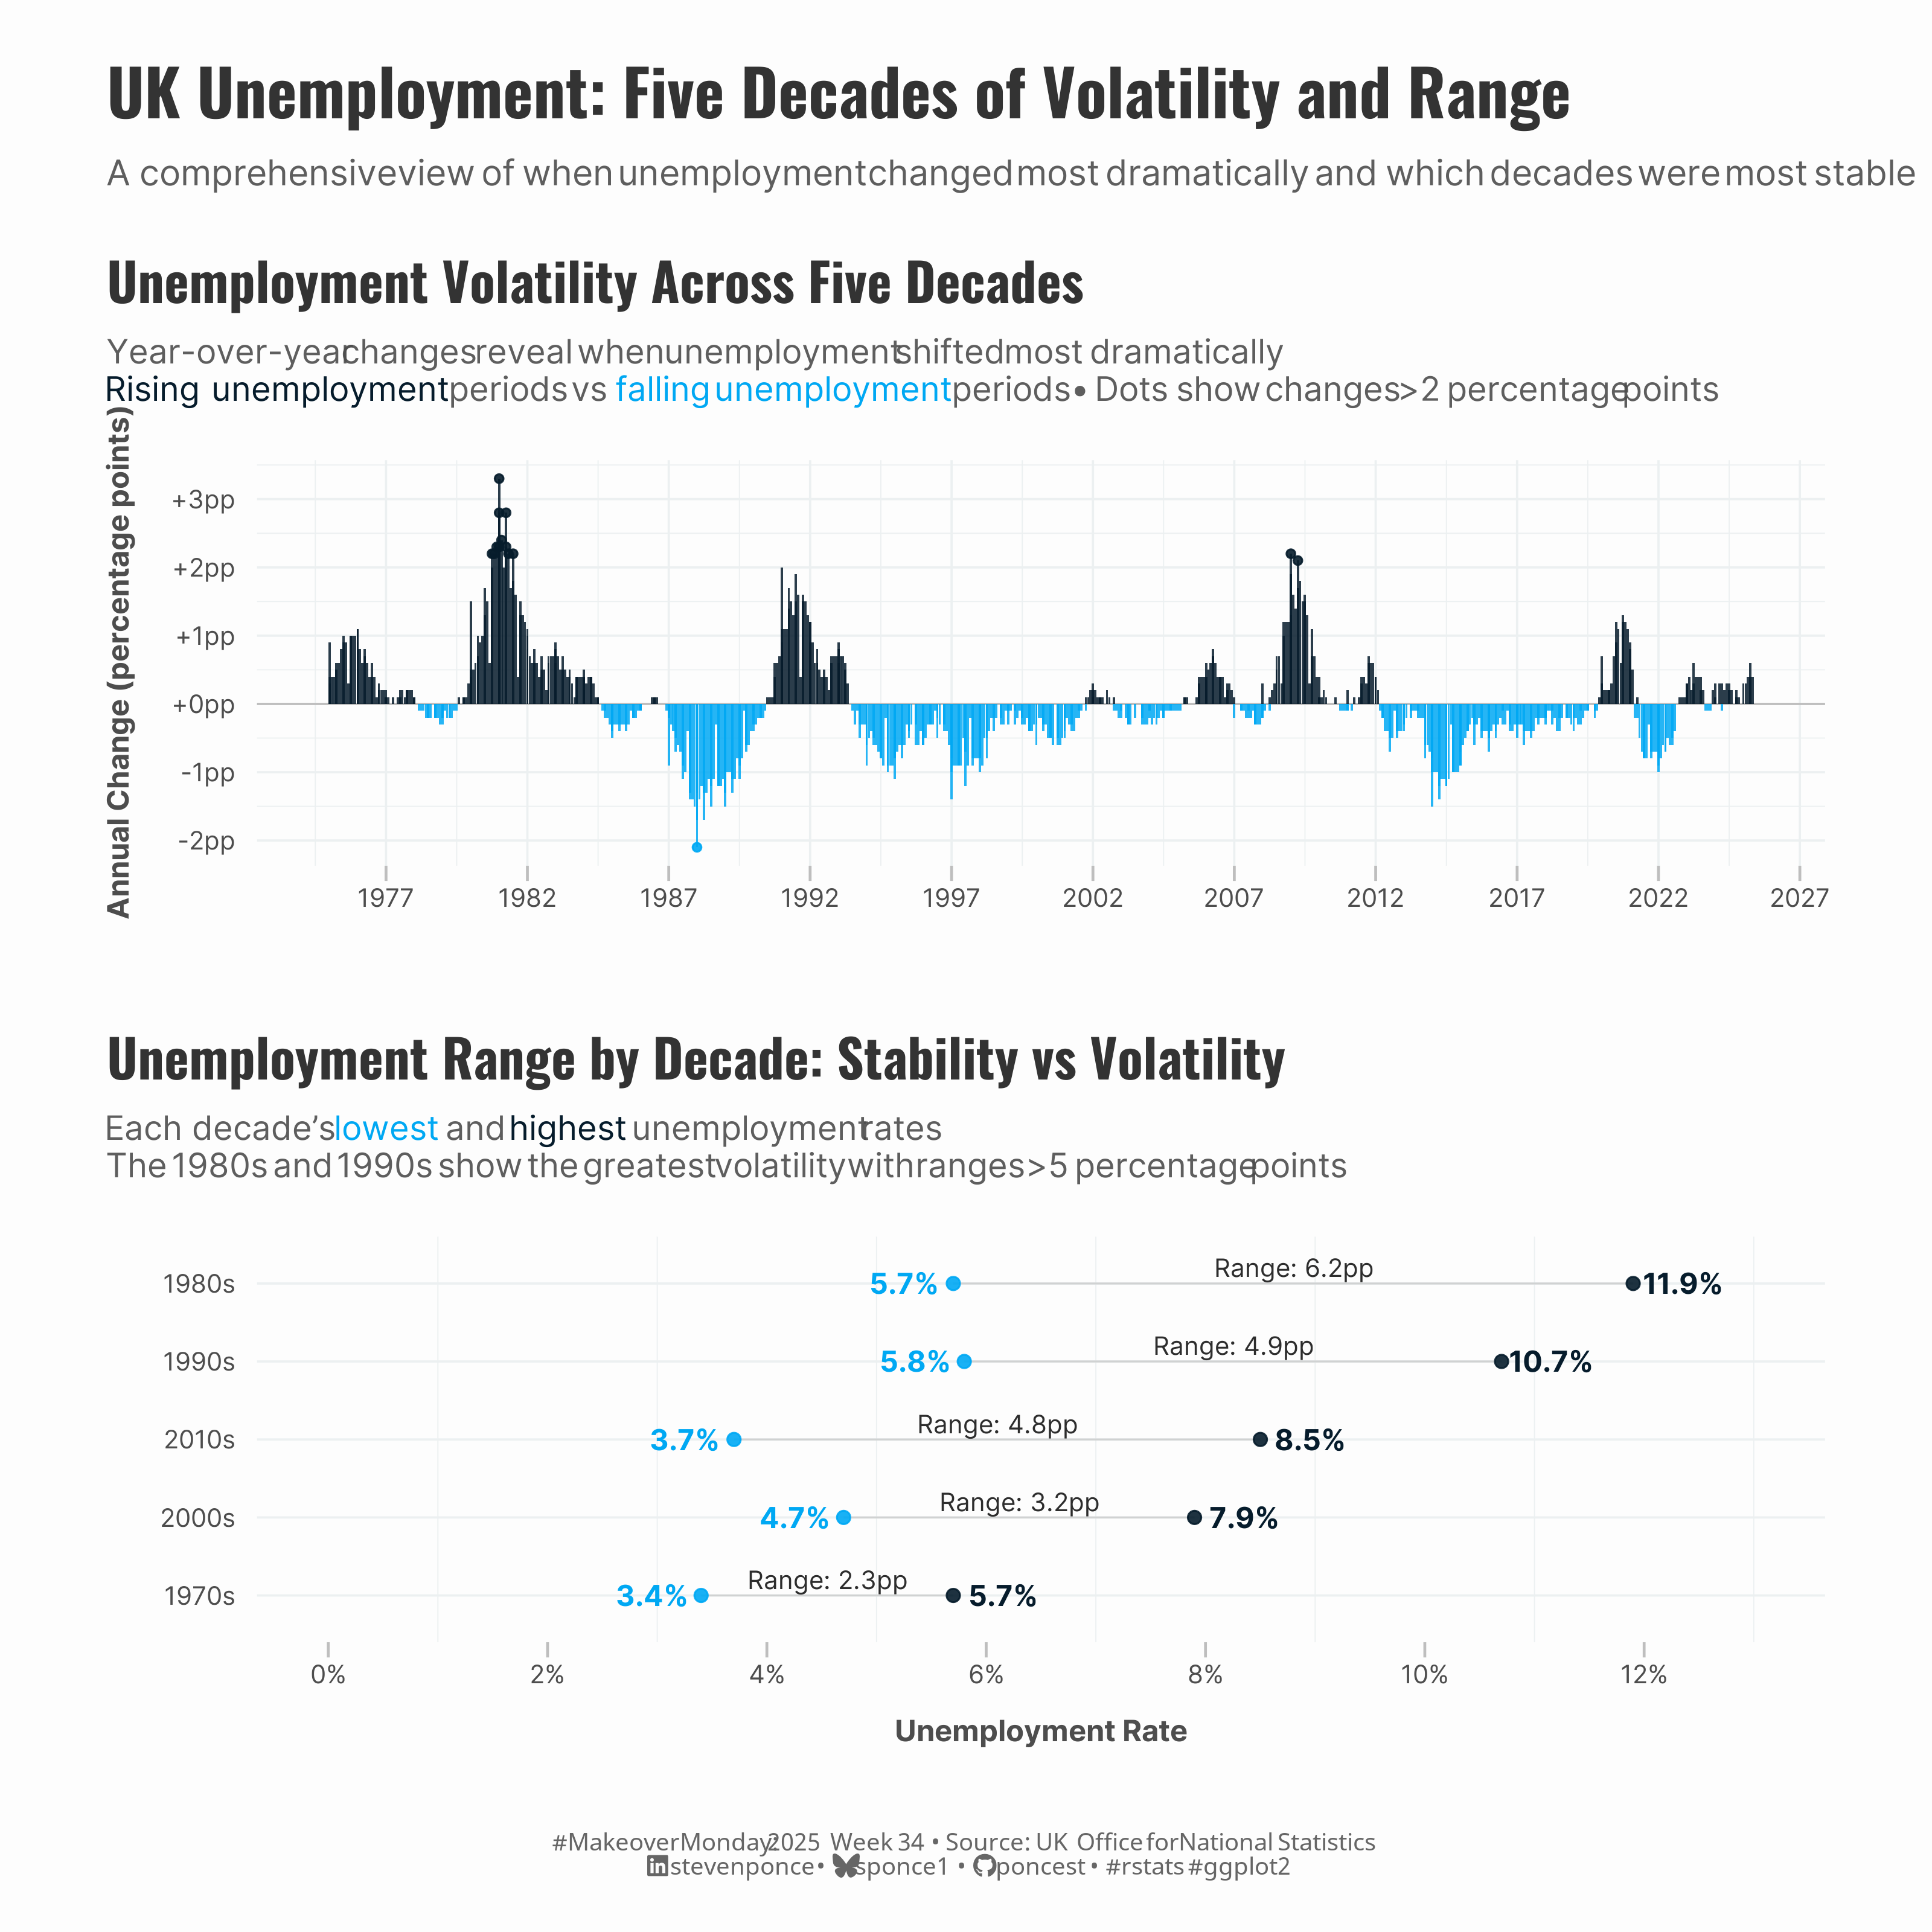
title: "UK Unemployment: Five Decades of Volatility and Range"
subtitle: "A comprehensive view of when unemployment changed most dramatically and which decades were most stable"
description: "MakeoverMonday Week 34: Transforming UK unemployment data into volatility and range analysis. Reveals when unemployment changed most dramatically and compares decade stability using bar charts and dumbbell plots."
author: "Steven Ponce"
date: "2025-08-19"
categories: ["MakeoverMonday", "2025"]
tags: [
"unemployment",
"economic-data",
"time-series",
"volatility-analysis",
"recession-periods",
"ggplot2",
"data-tidying",
"faceted-charts",
"dumbbell-chart",
"bar-chart",
"uk-statistics",
"labor-market",
"economic-trends",
"1980s-recession",
"financial-crisis"
]
image: "thumbnails/mm_2025_34.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
```{r}
#| label: setup-links
#| include: false
# CENTRALIZED LINK MANAGEMENT
## Project-specific info
current_year <- 2025
current_week <- 34
project_file <- "mm_2025_34.qmd"
project_image <- "mm_2025_34.png"
## Data Sources
data_main <- "https://data.world/makeovermonday/2025-week-34-unemployment-rate"
data_secondary <- "https://www.ons.gov.uk/employmentandlabourmarket/peoplenotinwork/unemployment/timeseries/mgsx/lms?utm_source=chatgpt.com"
## Repository Links
repo_main <- "https://github.com/poncest/personal-website/"
repo_file <- paste0("https://github.com/poncest/personal-website/blob/master/data_visualizations/MakeoverMonday/", current_year, "/", project_file)
## External Resources/Images
chart_original <- "https://raw.githubusercontent.com/poncest/MakeoverMonday/refs/heads/master/2025/Week_34/original_chart.png"
## Organization/Platform Links
org_primary <- "https://www.ons.gov.uk/employmentandlabourmarket/peoplenotinwork/unemployment/timeseries/mgsx/lms?utm_source=chatgpt.com"
org_secondary <- "https://www.ons.gov.uk/"
# Helper function to create markdown links
create_link <- function(text, url) {
paste0("[", text, "](", url, ")")
}
# Helper function for citation-style links
create_citation_link <- function(text, url, title = NULL) {
if (is.null(title)) {
paste0("[", text, "](", url, ")")
} else {
paste0("[", text, "](", url, ' "', title, '")')
}
}
```
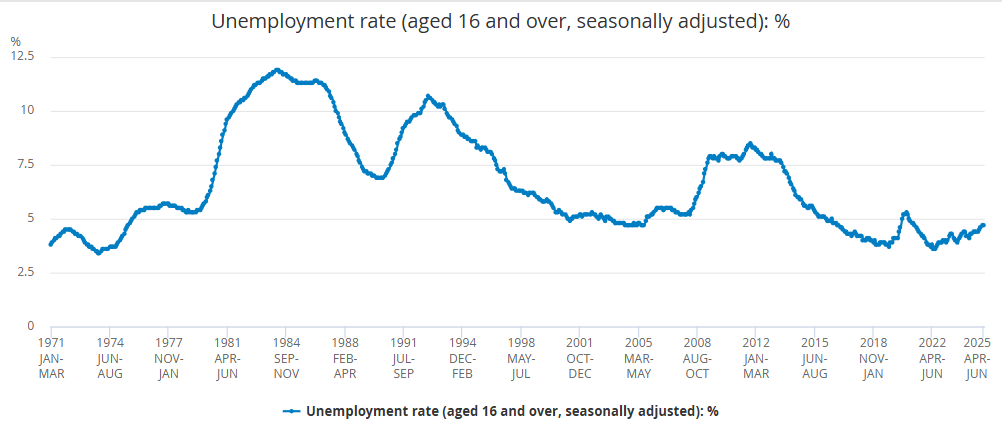
### Original
The original visualization **Unemployment Rate** comes from `r create_link("UK Office for National Statistics", data_secondary)`
<!--  -->
### Makeover
{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
  if (!require("pacman")) install.packages("pacman")
  pacman::p_load(
    tidyverse,  # Easily Install and Load the 'Tidyverse'
    ggtext,     # Improved Text Rendering Support for 'ggplot2'
    showtext,   # Using Fonts More Easily in R Graphs
    scales,     # Scale Functions for Visualization
    glue,       # Interpreted String Literals
    patchwork   # The Composer of Plots
  )
})

### |- figure size ----
camcorder::gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  = 10,
    height = 10,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
#|
uk_unemployment_raw <- read_csv(
  here::here('data/MakeoverMonday/2025/UK_unemployment rate_adjusted.csv'),
             skip = 7,
             col_names = c("date", "percent"),
             show_col_types = FALSE) |>
    slice(-1)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(uk_unemployment_raw)
skimr::skim(uk_unemployment_raw)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

# helper function for date parsing
parse_uk_dates <- function(date_str) {
  result <- rep(as.Date(NA), length(date_str))

  # Case 1: Year only (e.g., "1971")
  year_only <- str_detect(date_str, "^\\d{4}$")
  if(any(year_only, na.rm = TRUE)) {
    result[year_only] <- as.Date(paste0(date_str[year_only], "-01-01"))
  }

  # Case 2: Quarter format (e.g., "1971 Q1")
  quarter_format <- str_detect(date_str, "^\\d{4}\\s+Q[1-4]$")
  if(any(quarter_format, na.rm = TRUE)) {
    for(i in which(quarter_format)) {
      year <- str_extract(date_str[i], "^\\d{4}")
      quarter_num <- as.numeric(str_extract(date_str[i], "(?<=Q)\\d"))
      month <- (quarter_num - 1) * 3 + 1
      result[i] <- as.Date(paste0(year, "-", sprintf("%02d", month), "-01"))
    }
  }

  # Case 3: Month-Year formats (various separators)
  month_year <- str_detect(date_str, "[A-Z]{3}")
  if(any(month_year, na.rm = TRUE)) {
    for(i in which(month_year)) {
      if(str_detect(date_str[i], "^[A-Z]{3}-\\d{4}$")) {
        # Format: JAN-1971
        parts <- str_split(date_str[i], "-")[[1]]
        month_abbr <- parts[1]
        year <- parts[2]
      } else if(str_detect(date_str[i], "^\\d{4}-[A-Z]{3}$")) {
        # Format: 1971-JAN
        parts <- str_split(date_str[i], "-")[[1]]
        year <- parts[1]
        month_abbr <- parts[2]
      } else if(str_detect(date_str[i], "^[A-Z]{3}\\s+\\d{4}$")) {
        # Format: JAN 1971
        parts <- str_split(date_str[i], "\\s+")[[1]]
        month_abbr <- parts[1]
        year <- parts[2]
      } else if(str_detect(date_str[i], "^\\d{4}\\s+[A-Z]{3}$")) {
        # Format: 1971 JAN
        parts <- str_split(date_str[i], "\\s+")[[1]]
        year <- parts[1]
        month_abbr <- parts[2]
      } else {
        next
      }

      month_num <- match(month_abbr, toupper(month.abb))
      if(!is.na(month_num)) {
        result[i] <- as.Date(paste0(year, "-", sprintf("%02d", month_num), "-01"))
      }
    }
  }

  return(result)
}

# Tidy
uk_unemployment_tidy <- uk_unemployment_raw |>
  mutate(
    # Parse dates and create time variables
    date = parse_uk_dates(date),
    year = year(date),
    month = month(date, label = TRUE, abbr = TRUE),
    quarter = paste0("Q", quarter(date, with_year = FALSE)),
    decade = paste0(floor(year / 10) * 10, "s"),

    # Clean unemployment rate
    unemployment_rate = percent,

    # Add data frequency indicator
    data_frequency = case_when(
      str_detect(uk_unemployment_raw$date, "^\\d{4}$") ~ "Annual",
      str_detect(uk_unemployment_raw$date, "Q") ~ "Quarterly",
      str_detect(uk_unemployment_raw$date, "[A-Z]{3}") ~ "Monthly",
      TRUE ~ "Other"
    ),

    # Add economic periods for context
    economic_period = case_when(
      year >= 1971 & year <= 1979 ~ "1970s Oil Crisis Era",
      year >= 1980 & year <= 1989 ~ "1980s Recession & Recovery",
      year >= 1990 & year <= 1999 ~ "1990s Recession & Growth",
      year >= 2000 & year <= 2007 ~ "2000s Pre-Financial Crisis",
      year >= 2008 & year <= 2015 ~ "2008 Financial Crisis & Recovery",
      year >= 2016 & year <= 2019 ~ "Post-Brexit Vote Era",
      year >= 2020 ~ "COVID-19 Era",
      TRUE ~ "Other"
    ),

    # Flag recession periods (approximate UK recessions)
    recession_period = case_when(
      (year >= 1974 & year <= 1975) ~ "1974-75 Recession",
      (year >= 1980 & year <= 1981) ~ "1980-81 Recession",
      (year >= 1990 & year <= 1991) ~ "1990-91 Recession",
      (year >= 2008 & year <= 2009) ~ "2008-09 Financial Crisis",
      (year >= 2020 & year <= 2021) ~ "2020-21 COVID Recession",
      TRUE ~ "Non-recession"
    )
  ) |>
  # Keep only successfully parsed dates
  filter(!is.na(date)) |>
  arrange(date) |>
  # Keep only essential columns
  select(
    date, year, month, quarter, decade, unemployment_rate,
    data_frequency, economic_period, recession_period
  )

# Year-over-year data
yoy_data <- uk_unemployment_tidy |>
  arrange(date) |>
  mutate(
    yoy_change = unemployment_rate - lag(unemployment_rate, 12),
    change_direction = ifelse(yoy_change > 0, "Rising Unemployment", "Falling Unemployment")
  ) |>
  filter(!is.na(yoy_change), year >= 1975) |>
  mutate(
    decade_group = paste0(floor(year / 10) * 10, "s"),
    # Create better decade labels
    decade_label = case_when(
      decade_group == "1970s" ~ "1970s\nOil Crisis",
      decade_group == "1980s" ~ "1980s\nThatcher Era",
      decade_group == "1990s" ~ "1990s\nPost-Recession",
      decade_group == "2000s" ~ "2000s\nPre-Crisis",
      decade_group == "2010s" ~ "2010s\nAusterity",
      decade_group == "2020s" ~ "2020s\nCOVID Era",
      TRUE ~ decade_group
    ),
    # Flag extreme changes
    extreme_change = abs(yoy_change) > 2
  )

# Data for annotations (YoY)
annotation_data <- yoy_data |>
  group_by(decade_label) |>
  summarise(
    date = min(date),
    .groups = "drop"
  ) |>
  mutate(
    date = if_else(str_detect(decade_label, "2020s"), date + months(12), date)
  )

# Dumbbell data (min/max)
dumbbell_data <- uk_unemployment_tidy |>
  group_by(decade) |>
  summarise(
    min_rate = min(unemployment_rate),
    max_rate = max(unemployment_rate),
    range_width = max_rate - min_rate,
    .groups = "drop"
  ) |>
  # Better decade labels
  mutate(
    decade_label = case_when(
      decade == "1970s" ~ "1970s",
      decade == "1980s" ~ "1980s",
      decade == "1990s" ~ "1990s",
      decade == "2000s" ~ "2000s",
      decade == "2010s" ~ "2010s",
      decade == "2020s" ~ "2020s*",
      TRUE ~ decade
    )
  ) |>
  filter(decade != "2020s") # Remove incomplete decade
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
# Get base colors with custom palette
colors <- get_theme_colors(palette = list(
   "#00a8f3", "#061c2c", "#2d2d2d","#6b6b6b"
))

### |-  titles and caption ----
title_text <- str_glue("UK Unemployment: Five Decades of Volatility and Range")

subtitle_text <- str_glue(
  "A comprehensive view of when unemployment changed most dramatically and which decades were most stable"
)

# Create caption
caption_text <- create_mm_caption(
  mm_year = current_year,
  mm_week = current_week,
  source_text = paste0("UK Office for National Statistics")
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    plot.title = element_text(
      size = rel(1.4), family = fonts$title, face = "bold",
      color = colors$title, lineheight = 1.1, hjust = 0,
      margin = margin(t = 5, b = 10)
    ),
    plot.subtitle = element_markdown(
      size = rel(0.9), family = fonts$subtitle, face = "italic",
      color = alpha(colors$subtitle, 0.9), lineheight = 1.1,
      margin = margin(t = 0, b = 20)
    ),

    # Legend formatting
    legend.position = "plot",
    legend.justification = "top",
    legend.margin = margin(l = 12, b = 5),
    legend.key.size = unit(0.8, "cm"),
    legend.box.margin = margin(b = 10),
    legend.title = element_text(face = "bold"),

    # Axis formatting
    axis.ticks.y = element_blank(),
    axis.ticks.x = element_line(color = "gray", linewidth = 0.5),
    axis.ticks.length = unit(0.2, "cm"),
    axis.title.x = element_text(
      face = "bold", size = rel(0.85),
      margin = margin(t = 10)
    ),
    axis.title.y = element_text(
      face = "bold", size = rel(0.85),
      margin = margin(r = 10)
    ),
    axis.text.x = element_text(
      size = rel(0.85), family = fonts$subtitle,
      color = colors$text
    ),
    axis.text.y = element_text(
      size = rel(0.85), family = fonts$subtitle,
      color = colors$text
    ),

    # Grid lines
    panel.grid.minor = element_line(color = "#ecf0f1", linewidth = 0.2),
    panel.grid.major = element_line(color = "#ecf0f1", linewidth = 0.4),

    # Margin
    plot.margin = margin(20, 20, 20, 20)
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |- P1  YoY bar chart ----
p1 <- ggplot(yoy_data, aes(x = date, y = yoy_change)) +
  # Geoms
  geom_text(
    data = annotation_data, # annotations for the decade labels
    aes(x = date, label = decade_label),
    y = 5,
    hjust = 0,
    vjust = 0,
    size = 3.1,
    family = fonts$text,
    color = colors$palette[3],
    fontface = "bold",
    lineheight = 1.2
  ) +
  geom_hline(yintercept = 0, color = 'gray', linetype = "solid", size = 0.4) +
  geom_col(aes(fill = change_direction), alpha = 0.85, width = 30, position = "identity") +
  geom_point( # Highlight extreme changes
    data = yoy_data |> filter(extreme_change),
    aes(color = change_direction),
    size = 1.2,
    alpha = 0.9
  ) +
  # Scales
  scale_fill_manual(
    values = c(
      "Rising Unemployment" = colors$palette[2],
      "Falling Unemployment" = colors$palette[1]
    ),
    name = "Unemployment",
    labels = c("Falling", "Rising")
  ) +
  scale_color_manual(
    values = c(
      "Rising Unemployment" = colors$palette[2],
      "Falling Unemployment" = colors$palette[1]
    ),
    guide = "none"
  ) +
  scale_y_continuous(
    labels = function(x) paste0(ifelse(x >= 0, "+", ""), round(x, 1), "pp"),
    breaks = seq(-2,3, by = 1),
  ) +
  scale_x_date(
    breaks = scales::date_breaks("5 years"),
    labels = scales::date_format("%Y")
  ) +
  # Labs
  labs(
    title = "Unemployment Volatility Across Five Decades",
    subtitle = str_glue(
    "Year-over-year changes reveal when unemployment shifted most dramatically<br>
    <span style='color:{colors$palette[2]}'>**Rising unemployment**</span> periods vs
    <span style='color:{colors$palette[1]}'>**falling unemployment**</span> periods •
    Dots show changes >2 percentage points"
    ),
    x = NULL,
    y = "Annual Change (percentage points)",
  )

### |- P2  dumbbell chart----
p2 <- ggplot(dumbbell_data, aes(y = fct_reorder(decade_label, range_width))) +
  # Geoms
  geom_segment(
    aes(x = min_rate, xend = max_rate, yend = decade_label),
    color = 'gray',
    linewidth = 0.35,
    alpha = 0.6
  ) +
  geom_point( # Minimum points
    aes(x = min_rate),
    color = colors$palette[1],
    size = 2,
    alpha = 0.9
  ) +
  geom_point( # Maximum points
    aes(x = max_rate),
    color = colors$palette[2],
    size = 2,
    alpha = 0.9
  ) +
  geom_text(
    aes(x = min_rate, label = paste0(round(min_rate, 1), "%")),
    nudge_x = -0.45,
    size = 3.8,
    color = colors$palette[1],
    fontface = "bold",
    family = fonts$text
  ) +
  geom_text(
    aes(x = max_rate, label = paste0(round(max_rate, 1), "%")),
    nudge_x = 0.45,
    size = 3.8,
    color = colors$palette[2],
    fontface = "bold",
    family = fonts$text
  ) +
  geom_text(  # Range labels
    aes(x = (min_rate + max_rate)/2,
        label = paste0("Range: ", round(range_width, 1), "pp")),
    nudge_y = 0.2,
    size = 3.3,
    color = colors$palette[3],
    fontface = "italic",
    family = fonts$text
  ) +
  # Scales
  scale_x_continuous(
    labels = percent_format(scale = 1),
    breaks = seq(0, 12, 2),
    limits = c(0, 13)
  ) +
  # Labs
  labs(
    title = "Unemployment Range by Decade: Stability vs Volatility",
    subtitle = str_glue(
    "Each decade's <span style='color:{colors$palette[1]}'>**lowest**</span> and
     <span style='color:{colors$palette[2]}'>**highest**</span> unemployment rates<br>
     The 1980s and 1990s show the greatest volatility with ranges >5 percentage points"
    ),
    x = "Unemployment Rate",
    y = NULL,
  ) +
  # Theme
  theme(
    axis.line.y = element_blank(),
    panel.grid.major.x = element_blank()
  )

### |-  combined plot ----
combined_plots <- p1 / p2 +
  plot_layout(heights = c(1, 1))

combined_plots <- combined_plots +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        size = rel(1.7),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.1,
        margin = margin(t = 5, b = 5)
      ),
      plot.subtitle = element_markdown(
        size = rel(0.95),
        family = fonts$subtitle,
        color = alpha(colors$subtitle, 0.9),
        lineheight = 0.9,
        margin = margin(t = 5, b = 0)
      ),
      plot.caption = element_markdown(
        size = rel(0.65),
        family = fonts$caption,
        color = colors$caption,
        hjust = 0.5,
        margin = margin(t = 10)
      )
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  plot = combined_plots,
  type = "makeovermonday",
  year = current_year,
  week = current_week,
  width = 10,
  height = 10
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in `r create_link(project_file, repo_file)`.
For the full repository, `r create_link("click here", repo_main)`.
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data:
- Makeover Monday `r current_year` Week `r current_week`: `r create_link("UK Unemployment Rate", data_main)`
2. Article
- `r create_link("UK Unemployment Rate", data_secondary)`
:::

