---
title: "The Simpsons: Character Dialogue Analysis (2010-2016)"
subtitle: "Exploring speaking patterns, viewership trends, and character contributions across seasons"
description: "An in-depth analysis of The Simpsons character dialogues from 2010-2016, revealing speaking patterns, viewership trends, and character contributions. Through data visualization, we explore how the Simpson family dominates conversations, examine the declining viewership pattern, and identify unique speaking characteristics of key characters."
author: "Steven Ponce"
date: "2025-02-02"
categories: ["TidyTuesday", "2025"]
tags: [
"ggplot2",
"tidyverse",
"patchwork",
"text analysis",
"The Simpsons",
"TV shows",
"character analysis",
"data visualization",
"animated series",
"dialogue analysis",
"viewership trends",
"TV ratings",
"entertainment data",
"R programming"
]
image: "thumbnails/tt_2025_05.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
# filters:
# - social-share
# share:
# permalink: "https://stevenponce.netlify.app/data_visualizations/TidyTuesday/2025/tt_2025_05.html"
# description: "Analyzing The Simpsons dialogue data (2010-2016): Homer speaks 51K words while viewership declines. Discover how the Simpson family dominates screen time and shapes the show's narrative. #TidyTuesday #DataViz #TheSimpsons"
#
# twitter: true
# linkedin: true
# email: true
# facebook: false
# reddit: false
# stumble: false
# tumblr: false
# mastodon: true
# bsky: true
---
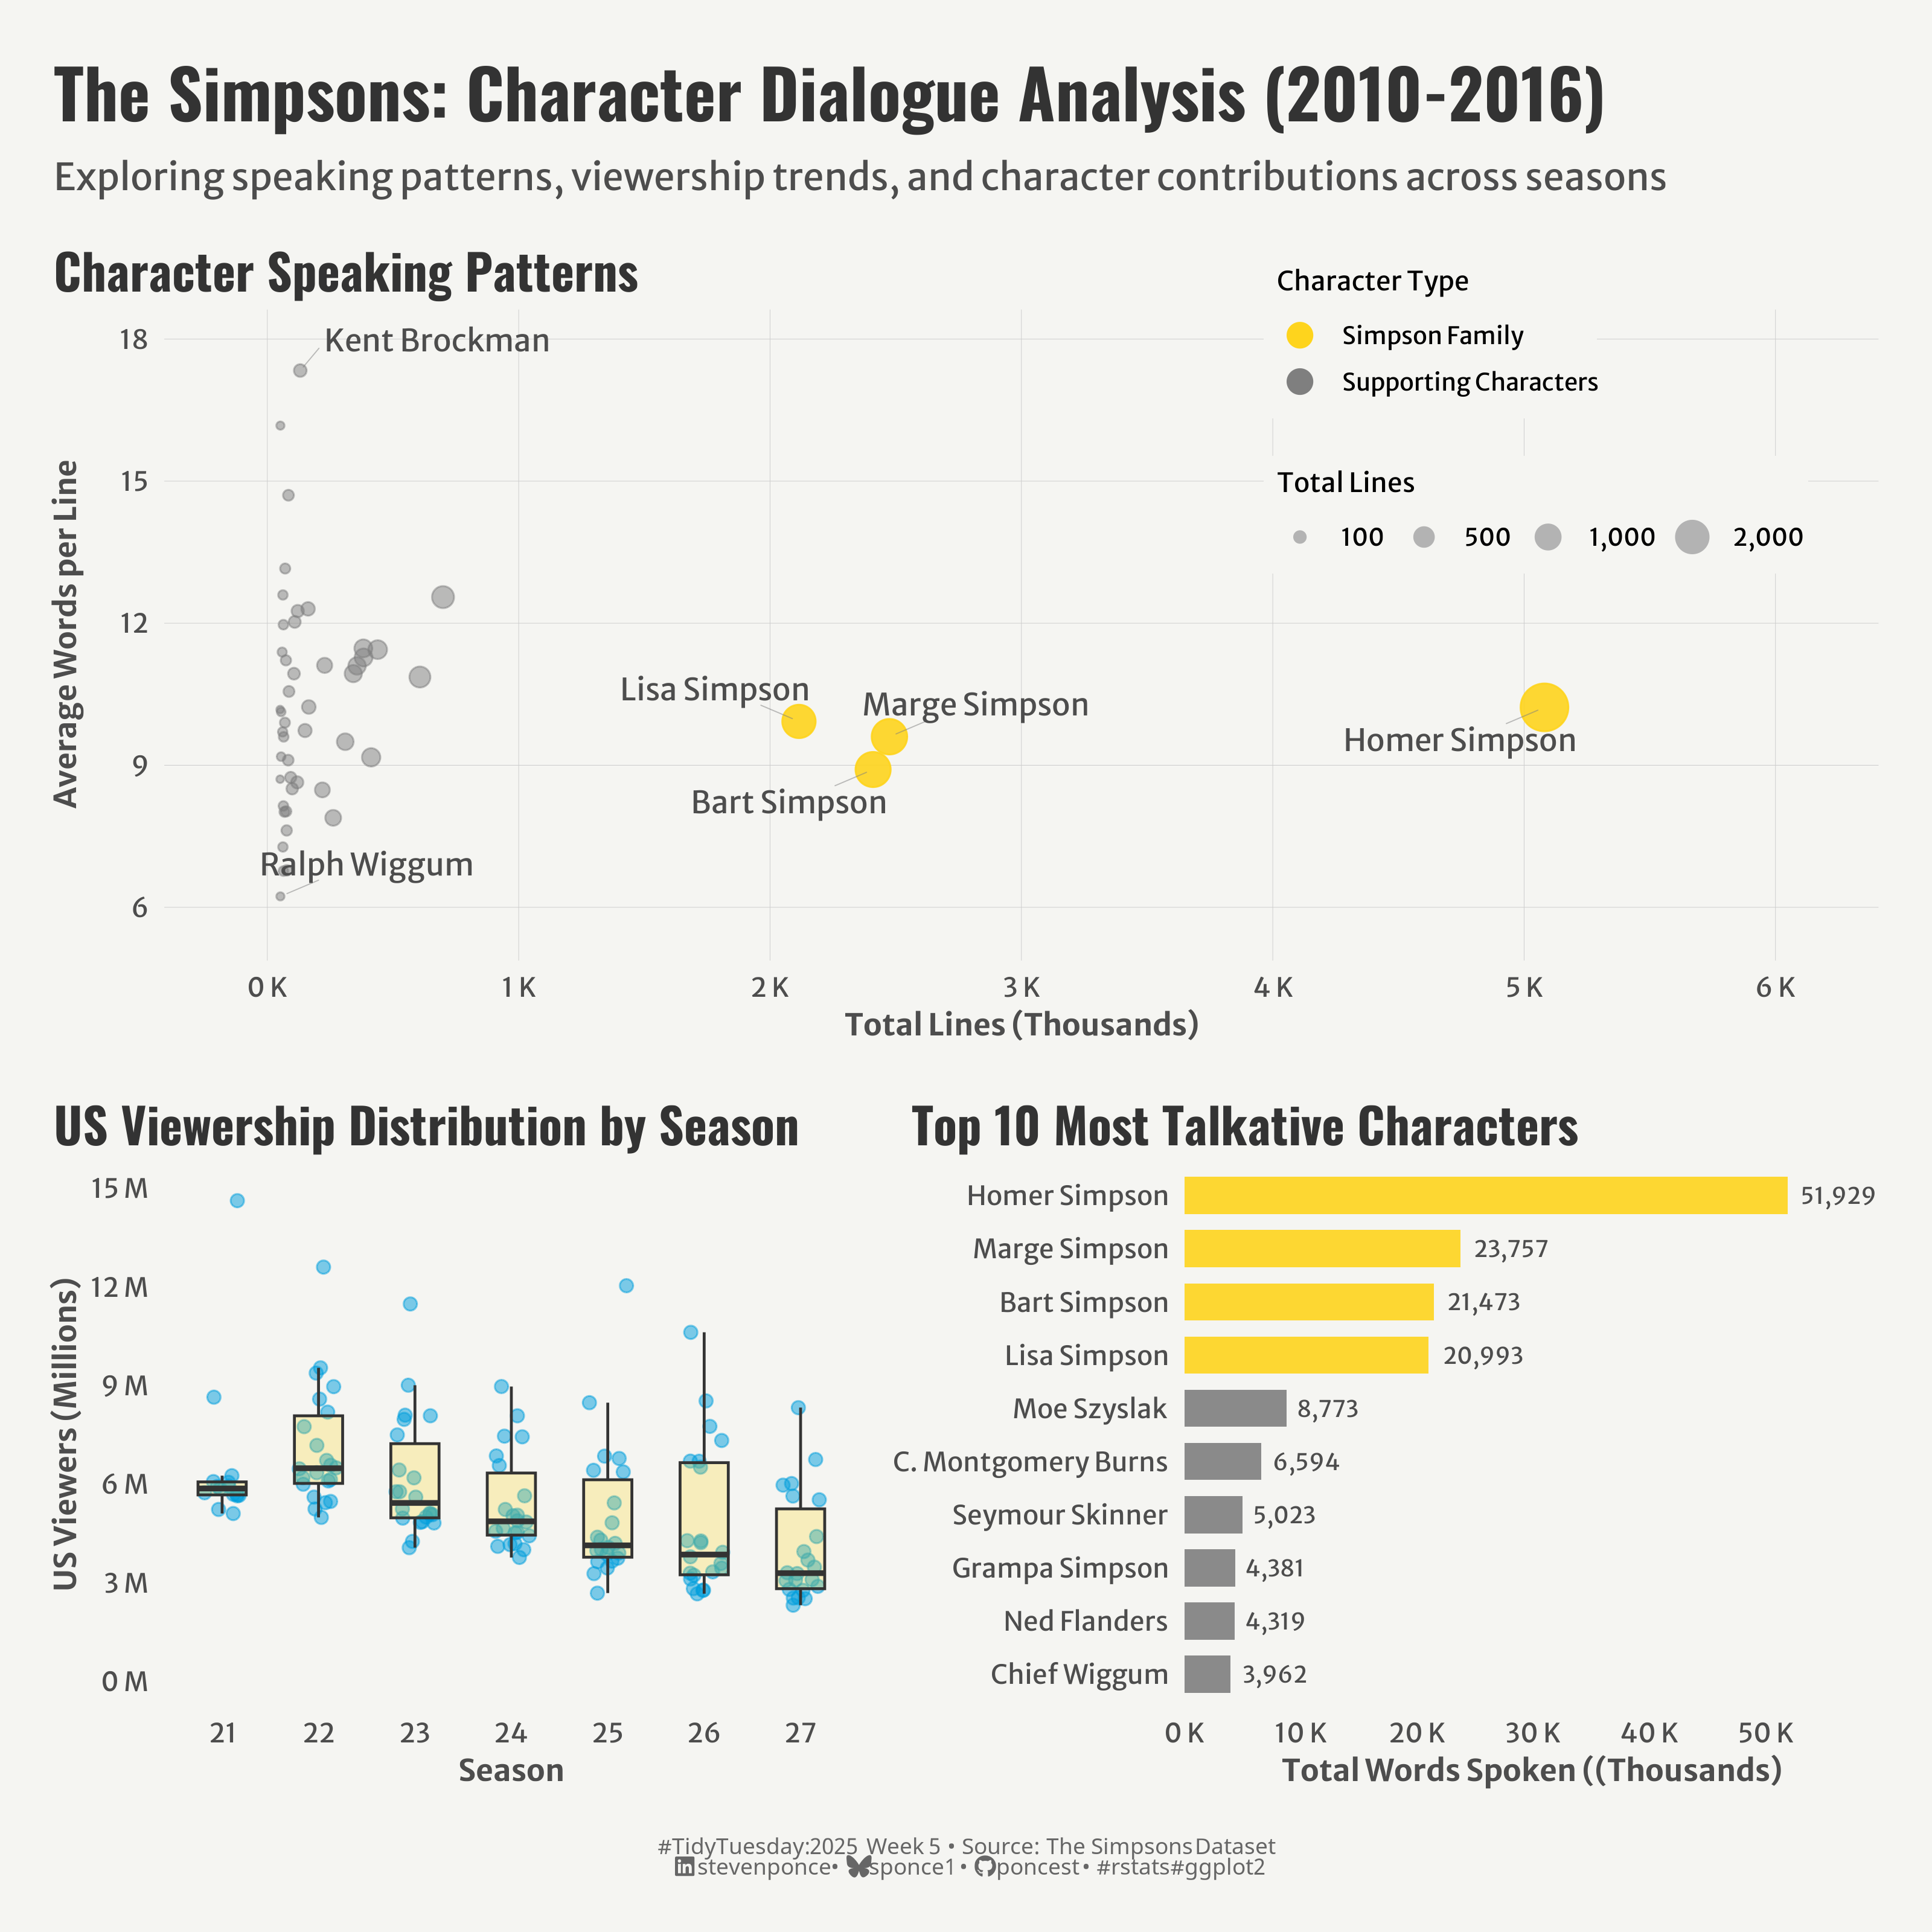{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"
## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
    tidyverse,      # Easily Install and Load the 'Tidyverse'
    ggtext,         # Improved Text Rendering Support for 'ggplot2'
    showtext,       # Using Fonts More Easily in R Graphs
    janitor,        # Simple Tools for Examining and Cleaning Dirty Data
    skimr,          # Compact and Flexible Summaries of Data
    scales,         # Scale Functions for Visualization
    glue,           # Interpreted String Literals
    here,           # A Simpler Way to Find Your Files
    patchwork,      # The Composer of Plots
    camcorder,      # Record Your Plot History
    tidytext,       # Text Mining using 'dplyr', 'ggplot2', and Other Tidy Tools
    ggrepel         # Automatically Position Non-Overlapping Text Labels with 'ggplot2'
    )
})

### |- figure size ----
gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  =  10,
    height =  10,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
tt <- tidytuesdayR::tt_load(2025, week = 05)

characters   <- tt$simpsons_characters |> clean_names()
episodes     <- tt$simpsons_episodes |> clean_names()
locations    <- tt$simpsons_locations |> clean_names()
script_lines <- tt$simpsons_script_lines |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false
glimpse(characters)
glimpse(episodes)
glimpse(locations)
glimpse(script_lines)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false
# Set seed for reproducibility
set.seed(123)

# P1. Character Speaking Pattern
speaking_patterns <- script_lines |>
    filter(
        !is.na(raw_character_text),
        speaking_line == TRUE,
        !(episode_id %in% c(597, 598, 599, 600))  # filter S28
    ) |>
    group_by(raw_character_text) |>
    summarise(
        total_lines = n(),
        avg_words = mean(word_count, na.rm = TRUE)
    ) |>
    ungroup() |>
    filter(total_lines > 50) |>
    mutate(
        character_type = case_when(
            raw_character_text %in% c("Homer Simpson", "Marge Simpson",
                                      "Bart Simpson", "Lisa Simpson") ~ "Simpson Family",
            TRUE ~ "Supporting Characters"
        ),
        show_label = raw_character_text %in% c(
            "Homer Simpson", "Marge Simpson", "Bart Simpson", "Lisa Simpson",
            "Kent Brockman", "Ralph Wiggum" # Key outliers
        )
    )

# P2. US Viewership Distribution by Season
episodes_filtered <- episodes |>
    filter(season != 28)

# P3. Top 10 Most Talkative Characters
talkative_chars <- script_lines |>
    filter(!is.na(raw_character_text)) |>
    group_by(raw_character_text) |>
    summarise(
        total_words = sum(word_count, na.rm = TRUE)
    ) |>
    ungroup() |>
    # Get top 10
    arrange(desc(total_words)) |>
    head(10) |>
    # Add character type and reverse the order
    mutate(
        character_type = case_when(
            raw_character_text %in% c("Homer Simpson", "Marge Simpson",
                                      "Bart Simpson", "Lisa Simpson") ~ "Simpson Family",
            TRUE ~ "Supporting Characters"
        ),
        # Create factor for reversed ordering
        raw_character_text = factor(raw_character_text, levels = rev(raw_character_text))
    )
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false
### |-  plot aesthetics ----
# Get base colors with custom palette
colors <- get_theme_colors(palette = c(
    "Simpson Family"        = "#FED41D",
    "Supporting Characters" = "grey50",
    " " = "#009DDC"
    )
)

### |-  titles and caption ----
title_text <- str_glue("The Simpsons: Character Dialogue Analysis (2010-2016)")
subtitle_text <- str_glue("Exploring speaking patterns, viewership trends, and character contributions across seasons")

# Create caption
caption_text <- create_social_caption(
    tt_year = 2025,
    tt_week = 05,
    source_text = "The Simpsons Dataset"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
    base_theme,
    theme(
        # Axis elements
        axis.title = element_text(color = colors$text, size = rel(0.8)),
        axis.text = element_text(color = colors$text, size = rel(0.7)),

        # Grid elements
        panel.grid.minor = element_blank(),
        panel.grid.major = element_line(color = "grey80", linewidth = 0.1),

        # Legend elements
        legend.position = "right",
        legend.title = element_text(family = fonts$text, size = rel(0.8)),
        legend.text = element_text(family = fonts$text, size = rel(0.7)),

        # Plot margins
        plot.margin = margin(t = 10, r = 10, b = 10, l = 10),

    )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false
### |-  Plot ----

# P1. Character Speaking Pattern
p1 <- ggplot(speaking_patterns, aes(x = total_lines, y = avg_words)) +

    # Geoms
    geom_point(aes(size = total_lines, color = character_type, alpha = character_type)) +
    geom_text_repel(
        data = filter(speaking_patterns, show_label),
        aes(label = raw_character_text),
        family = fonts$text,
        size = 4,
        color = "grey30",
        min.segment.length = 0,
        max.overlaps = Inf,
        segment.size = 0.2,
        segment.color = "grey50",
        segment.alpha = 0.5,
        box.padding = 0.5,
        point.padding = 0.3,
        force = 3,
        direction = "both",
        seed = 123
    ) +
    # Control legend order and appearance
    guides(
        color = guide_legend(
            override.aes = list(size = 4),
            order = 1
        ),
        size = guide_legend(
            nrow = 1,
            order = 2,
            override.aes = list(color = "grey70")
        )
    ) +

    # Scales
    scale_x_continuous(
        breaks = seq(0, 6000, 1000),
        labels = scales::label_number(scale = 1e-3, suffix = " K"),
        limits = c(-100, 6100)
    ) +
    scale_y_continuous(
        breaks = seq(6, 18, 3),
        limits = c(5.5, 18)
    ) +
    scale_color_manual(
        values = colors$palette
    ) +
    scale_alpha_manual(
        values = c("Simpson Family" = 0.9,
                   "Supporting Characters" = 0.5),
        guide = "none"
    ) +
    scale_size_continuous(
        range = c(1, 8),
        breaks = c(100, 500, 1000, 2000),
        labels = scales::comma
    ) +
    coord_cartesian(clip = 'off') +

    # Labs
    labs(
        title = "Character Speaking Patterns",
        x = "Total Lines (Thousands)",
        y = "Average Words per Line",
        color = "Character Type",
        size = "Total Lines"
    ) +

    # Theme
    theme(
        panel.grid = element_blank(),
        legend.position = c(0.8, 0.84),
        legend.box = "vertical",
        legend.background = element_rect(fill = colors$background, color = NA),
        legend.title = element_text(family = fonts$text, size = 10),
        legend.text = element_text(family = fonts$text, size = 9),
        legend.margin = margin(5, 5, 5, 5),

        plot.title = element_text(
            size   = rel(1.3),
            family = fonts$title,
            face   = "bold",
            color  = colors$title,
            lineheight = 1.1,
            margin = margin(t = 5, b = 5)
        ),
    )

# P2. US Viewership Distribution by Season
p2 <- ggplot(episodes_filtered, aes(x = factor(season), y = us_viewers_in_millions)) +

    # Geoms
    geom_point(
        position = position_jitter(width = 0.2, seed = 123),
        color = colors$palette[3],
        alpha = 0.5,
        size = 2
    ) +
    geom_boxplot(
        fill = colors$palette[1],
        alpha = 0.25,
        outlier.shape = NA,
        width = 0.5
    ) +

    # Scales
    scale_y_continuous(
        breaks = seq(0, 15, 3),
        limits = c(0, 15),
        labels = scales::label_number(scale = 1, suffix = " M"),
    ) +

    # Labs
    labs(
        title = "US Viewership Distribution by Season",
        x = "Season",
        y = "US Viewers (Millions)"
    ) +

    # Theme
    theme(
        panel.grid.minor = element_blank(),
        panel.grid.major = element_blank(),

        plot.title = element_text(
            size   = rel(1.3),
            family = fonts$title,
            face   = "bold",
            color  = colors$title,
            lineheight = 1.1,
            margin = margin(t = 5, b = 5)
        ),
    )

# P3. Top 10 Most Talkative Characters
p3 <- ggplot(talkative_chars,
             aes(x = raw_character_text,
                 y = total_words,
                 fill = character_type)) +

    # Geoms
    geom_col(
        width = 0.7,
        alpha = 0.9,
        show.legend = FALSE
    ) +
    geom_text(
        aes(label = scales::comma(total_words)),
        hjust = -0.2,
        family = fonts$text,
        size = 3,
        color = colors$text
    ) +

    # Scales
    scale_y_continuous(
        labels = scales::label_number(scale = 1e-3, suffix = " K"),
        expand = expansion(mult = c(0, 0.15))
    ) +
    scale_fill_manual(
        values = colors$palette
    ) +
    coord_flip() +

    # Labs
    labs(
        title = "Top 10 Most Talkative Characters",
        x = NULL,
        y = "Total Words Spoken ((Thousands)"
    ) +

    # Theme
    theme(
        panel.grid.minor = element_blank(),
        panel.grid.major = element_blank(),

        plot.title = element_text(
            size   = rel(1.3),
            family = fonts$title,
            face   = "bold",
            color  = colors$title,
            lineheight = 1.1,
            margin = margin(t = 5, b = 5)
        ),
    )

# Combine plots
combined_plot <- (p1 / (p2 + p3)) +

    plot_layout(
        heights = c(1.2, 1),
        widths = c(1, 1)
        )

combined_plot <- combined_plot +
    # Add overall title, subtitle, and caption
    plot_annotation(
        title = title_text,
        subtitle = subtitle_text,
        caption = caption_text,
        theme = theme(
            plot.title = element_text(
                size   = rel(1.8),
                family = fonts$title,
                face   = "bold",
                color  = colors$title,
                lineheight = 1.1,
                margin = margin(t = 5, b = 5)
            ),
            plot.subtitle = element_text(
                size   = rel(1),
                family = fonts$subtitle,
                color  = colors$subtitle,
                lineheight = 1.2,
                margin = margin(t = 5, b = 5)
            ),
            plot.caption = element_markdown(
                size   = rel(0.6),
                family = fonts$caption,
                color  = colors$caption,
                hjust  = 0.5,
                margin = margin(t = 10)
            ),
             plot.margin = margin(t = 20, r = 10, b = 20, l = 10)
            )
        )
```
#### 7. Save
```{r}
#| label: save
#| warning: false
### |-  plot image ----

save_plot_patchwork(
  plot = combined_plot,
  type = "tidytuesday",
  year = 2025,
  week = 5,
  width = 10,
  height = 10
)
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_05.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_05.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 05: [The Simpsons](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-02-04)
:::
