---
title: "A Tale of Pixar's Evolution: Duration and Reception"
subtitle: "How Pixar films have evolved in length and how audiences vs critics perceive them."
description: "An analysis of Pixar's film evolution examining how movie durations have increased over time and comparing audience and critic reception patterns across their filmography. Visualizations reveal interesting patterns in run times and reception across different eras and franchises."
author: "Steven Ponce"
date: "2025-03-10"
categories: ["TidyTuesday", "2025"]
tags: [
"pixar",
"film analysis",
"data storytelling",
"ggplot2",
"animation",
"movie ratings",
"cinema",
"audience reception",
"film critics",
"time series",
"entertainment data",
"patchwork"
]
image: "thumbnails/tt_2025_10.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
# filters:
# - social-share
# share:
# permalink: "https://stevenponce.netlify.app/data_visualizations/TidyTuesday/2025/tt_2025_10.html"
# description: "Exploring 25+ years of Pixar films: See how movie lengths have grown over time and discover which films critics loved but audiences didn't (and vice versa)! #TidyTuesday #DataViz"
#
# twitter: true
# linkedin: true
# email: true
# facebook: false
# reddit: false
# stumble: false
# tumblr: false
# mastodon: true
# bsky: true
---
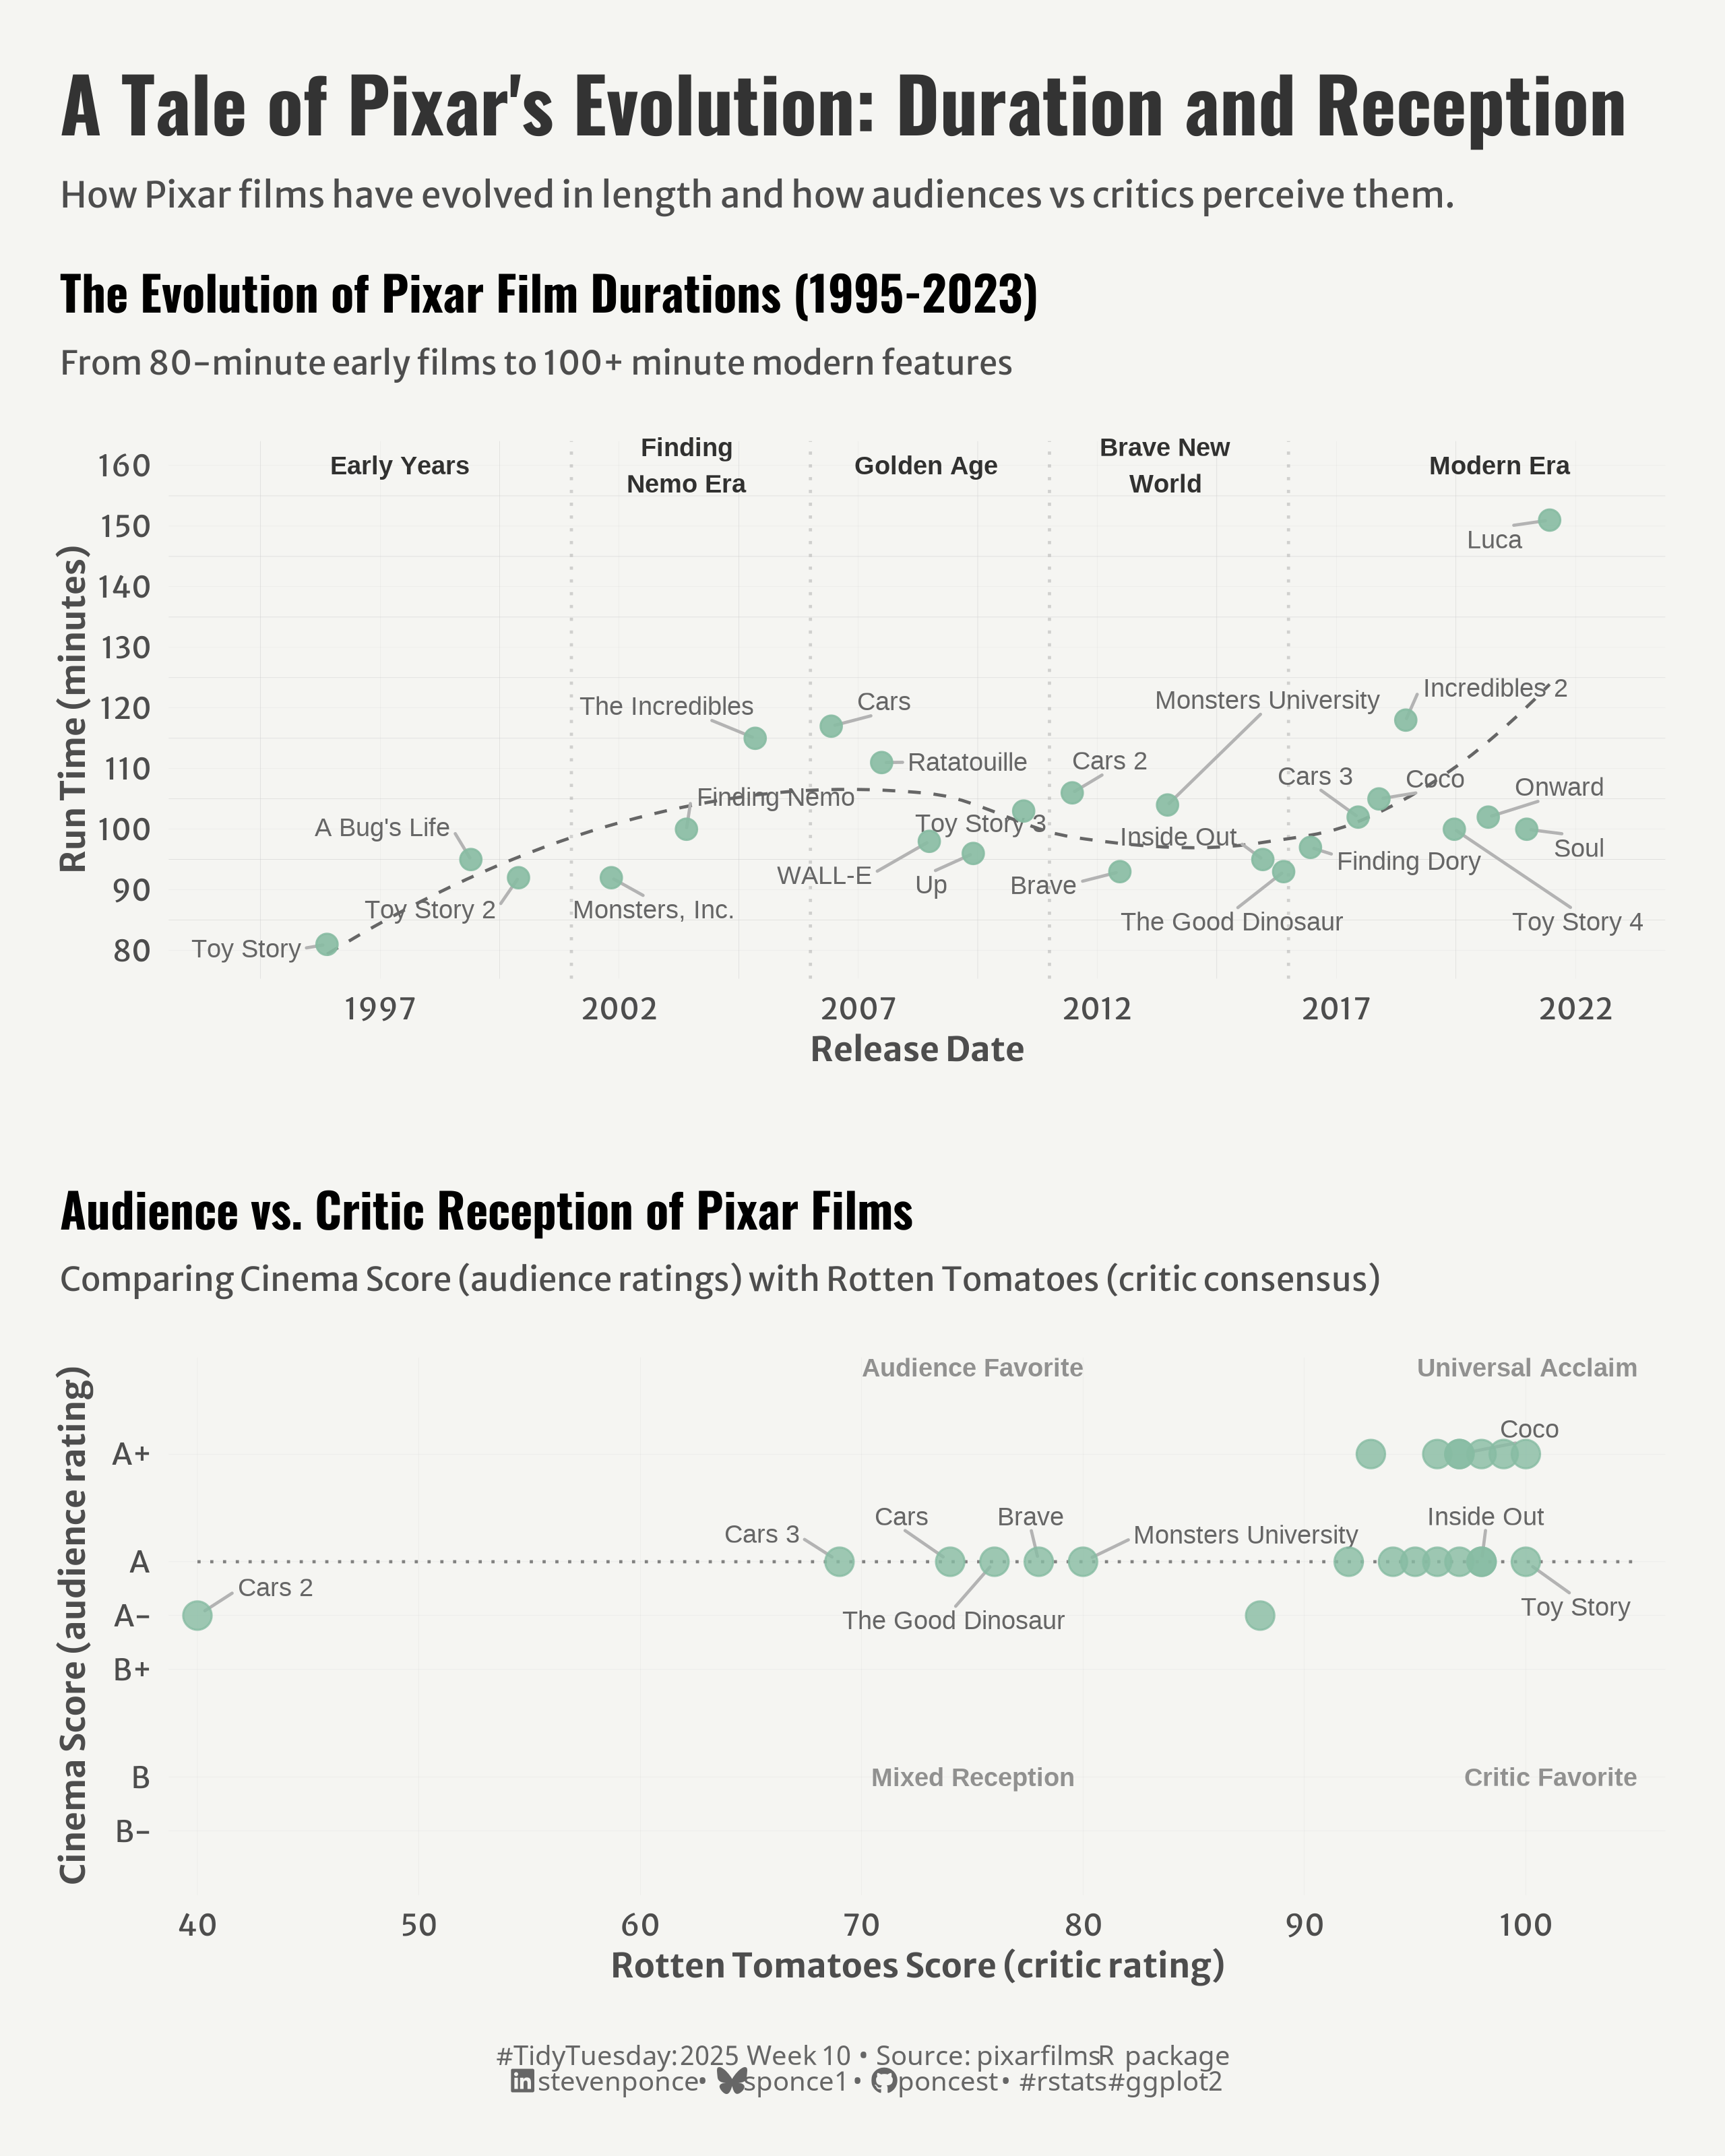{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"
## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
    tidyverse,      # Easily Install and Load the 'Tidyverse'
    ggtext,         # Improved Text Rendering Support for 'ggplot2'
    showtext,       # Using Fonts More Easily in R Graphs
    janitor,        # Simple Tools for Examining and Cleaning Dirty Data
    skimr,          # Compact and Flexible Summaries of Data
    scales,         # Scale Functions for Visualization
    glue,           # Interpreted String Literals
    here,           # A Simpler Way to Find Your Files
    camcorder,      # Record Your Plot History
    patchwork,      # The Composer of Plots # The Composer of Plots # The Composer of Plots
    ggrepel         # Position Non-Overlapping Text Labels with 'ggplot2'
    )
})

### |- figure size ----
gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  =  8,
    height =  10,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
tt <- tidytuesdayR::tt_load(2025, week = 10)

pixar_films <- tt$pixar_films |> clean_names()
public_response <- tt$public_response |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false
glimpse(pixar_films)
skim(pixar_films)

glimpse(public_response)
skim(public_response)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false
### |-  tidy data ----
# Combine the data for easier analysis
pixar_combined <- pixar_films |>
    left_join(public_response, by = "film")

# P1. Film Duration's ----

# Define eras for P1
p1_data <- pixar_combined |>
    mutate(
        era = case_when(
            release_date < as.Date("2001-01-01") ~ "Early Years (1995-2000)",
            release_date < as.Date("2006-01-01") ~ "Finding Nemo Era (2001-2005)",
            release_date < as.Date("2011-01-01") ~ "Golden Age (2006-2010)",
            release_date < as.Date("2016-01-01") ~ "Brave New World (2011-2015)",
            TRUE ~ "Modern Era (2016+)"
        )
    ) |>
    filter(!is.na(film))

# Define era boundary lines
era_boundaries <- data.frame(
    x = as.Date(c("2001-01-01", "2006-01-01", "2011-01-01", "2016-01-01")),
    ymin = 70,
    ymax = 160
)

# Era labels coordinates
era_labels <- data.frame(
    x = as.Date(c("1997-06-01", "2003-06-01", "2008-06-01", "2013-06-01", "2020-06-01")),
    y = c(rep(160, 5)),
    label = c("Early Years", "Finding\nNemo Era", "Golden Age", "Brave New\nWorld", "Modern Era")
)

# P2. Audience vs. Critic Reception ----
p2_data <- pixar_combined |>
    filter(!is.na(rotten_tomatoes) & !is.na(cinema_score)) |>
    mutate(
        # Convert Cinema Score to numeric
        cinema_score_numeric = case_when(
            cinema_score == "A+" ~ 10,
            cinema_score == "A" ~ 9,
            cinema_score == "A-" ~ 8.5,
            cinema_score == "B+" ~ 8,
            cinema_score == "B" ~ 7,
            cinema_score == "B-" ~ 6.5,
            TRUE ~ 5
        ),
        # Create release year groups
        release_decade = case_when(
            release_date < as.Date("2000-01-01") ~ "1995-1999",
            release_date < as.Date("2010-01-01") ~ "2000-2009",
            release_date < as.Date("2020-01-01") ~ "2010-2019",
            TRUE ~ "2020+"
        ),
        # Create selective labeling flag
        label_film = case_when(
            cinema_score_numeric >= 9 & rotten_tomatoes < 90 ~ TRUE,
            cinema_score_numeric < 10 & rotten_tomatoes >= 99 ~ TRUE,
            rotten_tomatoes < 50 ~ TRUE,
            film %in% c("Toy Story", "Inside Out", "Coco", "Soul") ~ TRUE,
            TRUE ~ FALSE
        )
    )

# Create a filtered dataframe for labels
p2_labels <- p2_data |> filter(label_film == TRUE)

# Define reception area dividing lines
reception_lines <- data.frame(
    type = c("vertical_1",  "horizontal"),
    x1 = c(90, 40),
    y1 = c(5, 9),
    x2 = c(90, 105),
    y2 = c(10.5, 9)
)
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false
### |-  plot aesthetics ----
# Color for P1
colors <- get_theme_colors(palette = c(
    "gray40", "gray60", "gray70", "gray80", "#87BBA2")
    )

### |-  titles and caption ----
title_text <- str_glue("A Tale of Pixar's Evolution: Duration and Reception")

subtitle_text <- str_glue("How Pixar films have evolved in length and how audiences vs critics perceive them.")

# Create caption
caption_text <- create_social_caption(
    tt_year = 2025,
    tt_week = 10,
    source_text =  "pixarfilms R package"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
    base_theme,
    theme(
        # Text styling
        plot.title = element_text(face = "bold", family = fonts$title, size = rel(1.14), margin = margin(b = 10)),
        plot.subtitle = element_text(family = fonts$subtitle, color = colors$text, size = rel(0.78), margin = margin(b = 20)),

        # Axis elements
        axis.title = element_text(color = colors$text, face = "bold", size = rel(0.8)),
        axis.text = element_text(color = colors$text, size = rel(0.7)),

        # Grid elements
        panel.grid.minor = element_line(color = "gray80", linewidth = 0.05),
        panel.grid.major = element_line(color = "gray80", linewidth = 0.02),

        # Legend elements
        legend.position = "plot",
        legend.title = element_text(family = fonts$text, size = rel(0.8)),
        legend.text = element_text(family = fonts$text, size = rel(0.7)),

        # Plot margins
        plot.margin = margin(t = 10, r = 10, b = 10, l = 10),
    )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false
### |-  Plot  ----
# P1. Film Duration's ----
p1 <- ggplot(p1_data, aes(x = release_date, y = run_time)) +
  # Geoms
  geom_vline(
    data = era_boundaries,
    aes(xintercept = x),
    linetype = "dotted",
    color = colors$palette[2],
    alpha = 0.4
  ) +
  geom_smooth(
    method = "loess", se = FALSE, color = colors$palette[1],
    linewidth = 0.5, alpha = 0.6, linetype = "dashed", na.rm = TRUE
  ) +
  geom_text_repel(
    aes(label = film),
    size = 3,
    max.overlaps = 10,
    box.padding = 0.5,
    colour = colors$palette[1],
    segment.color = colors$palette[3],
    min.segment.length = 0.2,
    seed = 123
  ) +
  geom_point(size = 3, color = colors$palette[5], alpha = 0.9, na.rm = TRUE) +
  # Annotate
  annotate(
    "text",
    x = era_labels$x,
    y = era_labels$y,
    label = era_labels$label,
    alpha = 0.8,
    fontface = "bold",
    size = 3
  ) +
  # Scales
  scale_x_date(
    date_breaks = "5 years",
    date_labels = "%Y",
    limits = c(as.Date("1994-01-01"), NA)
  ) +
  scale_y_continuous(
    breaks = seq(80, 180, by = 10),
  ) +
  coord_cartesian(clip = "off") +
  # Labs
  labs(
    title = "The Evolution of Pixar Film Durations (1995-2023)",
    subtitle = "From 80-minute early films to 100+ minute modern features",
    x = "Release Date",
    y = "Run Time (minutes)"
  )

# P2. Audience vs. Critic Reception ----
p2 <- ggplot(p2_data, aes(x = rotten_tomatoes, y = cinema_score_numeric)) +
  # Geoms
  geom_segment(
    data = reception_lines,
    aes(x = x1, y = y1, xend = x2, yend = y2),
    linetype = "dotted", color = colors$palette[1], alpha = 0.8
  ) +
  geom_text_repel(
    data = p2_labels,
    aes(label = film),
    size = 3,
    box.padding = 0.8,
    point.padding = 0.5,
    colour = colors$palette[1],
    segment.color = colors$palette[3],
    min.segment.length = 0.2,
    max.overlaps = 30,
    force = 3,
    seed = 145
  ) +
  geom_point(
    aes(size = 3),
    color = colors$palette[5], alpha = 0.8
  ) +
  # Annotate
  annotate(
    "text",
    x = 105, y = 10.8,
    label = "Universal Acclaim",
    size = 3, fontface = "bold", alpha = 0.7,
    color = colors$palette[1],
    hjust = 1
  ) +
  annotate(
    "text",
    x = 105, y = 7,
    label = "Critic Favorite",
    size = 3, fontface = "bold", alpha = 0.7,
    color = colors$palette[1],
    hjust = 1
  ) +
  annotate(
    "text",
    x = 75, y = 10.8,
    label = "Audience Favorite",
    size = 3, fontface = "bold", alpha = 0.7,
    color = colors$palette[1],
    hjust = 0.5
  ) +
  annotate(
    "text",
    x = 75, y = 7,
    label = "Mixed Reception",
    size = 3, fontface = "bold", alpha = 0.7,
    color = colors$palette[1],
    hjust = 0.5
  ) +
  # Scales
  scale_color_brewer(
    palette = "Set1",
    name = "Film Era"
  ) +
  scale_size_continuous(
    range = c(2, 5),
    name = "Runtime (min)"
  ) +
  scale_y_continuous(
    breaks = c(10, 9, 8.5, 8, 7, 6.5),
    labels = c("A+", "A", "A-", "B+", "B", "B-"),
    limits = c(6, 10.8),
    minor_breaks = NULL,
    expand = expansion(mult = c(0.02, 0.02))
  ) +
  scale_x_continuous(
    breaks = seq(40, 100, by = 10),
    limits = c(40, 105),
    minor_breaks = NULL,
    expand = expansion(mult = c(0.02, 0.02))
  ) +
  coord_cartesian(clip = "off") +
  # Labs
  labs(
    title = "Audience vs. Critic Reception of Pixar Films",
    subtitle = "Comparing Cinema Score (audience ratings) with Rotten Tomatoes (critic consensus)",
    y = "Cinema Score (audience rating)",
    x = "Rotten Tomatoes Score (critic rating)"
  )

# Combined Plot -----
combined_plot <- (p1 / plot_spacer() / p2) +
  plot_layout(
    height = c(1, 0.005, 1),
    ncol = 1
  )

combined_plot <- combined_plot +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        size = rel(1.8),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.1,
        margin = margin(t = 5, b = 5)
      ),
      plot.subtitle = element_text(
        size = rel(0.85),
        family = fonts$subtitle,
        color = colors$subtitle,
        lineheight = 1.2,
        margin = margin(t = 5, b = 10)
      ),
      plot.caption = element_markdown(
        size   = rel(0.65),
        family = fonts$caption,
        color  = colors$caption,
        hjust  = 0.5,
        margin = margin(t = 10)
      ),
      plot.margin = margin(t = 20, r = 10, b = 20, l = 10),
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false
### |-  plot image ----
save_plot_patchwork(
  plot = combined_plot,
  type = "tidytuesday",
  year = 2025,
  week = 10,
  width = 8,
  height = 10
)
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_10.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_10.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 10: [Pixar Films](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-03-11)
:::
