---
title: "Evolution of Business Priorities in Amazon's Annual Reports"
subtitle: "Tracking the relative importance of business areas from 2005 to 2023"
description: "Analyzing Amazon's transformation from e-commerce to tech giant through their annual reports. This visualization tracks how terminology shifts reflect changing business priorities, with AWS and cloud services becoming increasingly dominant while traditional retail language declined."
author: "Steven Ponce"
date: "2025-03-23"
categories: ["TidyTuesday", "2025"]
tags: [
"Amazon", "Annual Reports", "Text Analysis", "Natural Language Processing", "Business Evolution", "AWS", "Cloud Computing", "Corporate Language", "Financial Reporting", "Corporate Strategy", "Text Mining", "ggplot2", "Time Series Visualization", "Business Intelligence"
]
image: "thumbnails/tt_2025_12.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
# filters:
# - social-share
# share:
# permalink: "https://stevenponce.netlify.app/data_visualizations/TidyTuesday/2025/tt_2025_12.html"
# description: "Discover how Amazon's business priorities evolved from 2005-2023 through text analysis of their annual reports. See the dramatic rise of AWS, consistent financial focus, and the impact of key milestones like the Whole Foods acquisition and COVID-19 pandemic."
#
# twitter: true
# linkedin: true
# email: true
# facebook: false
# reddit: false
# stumble: false
# tumblr: false
# mastodon: true
# bsky: true
---
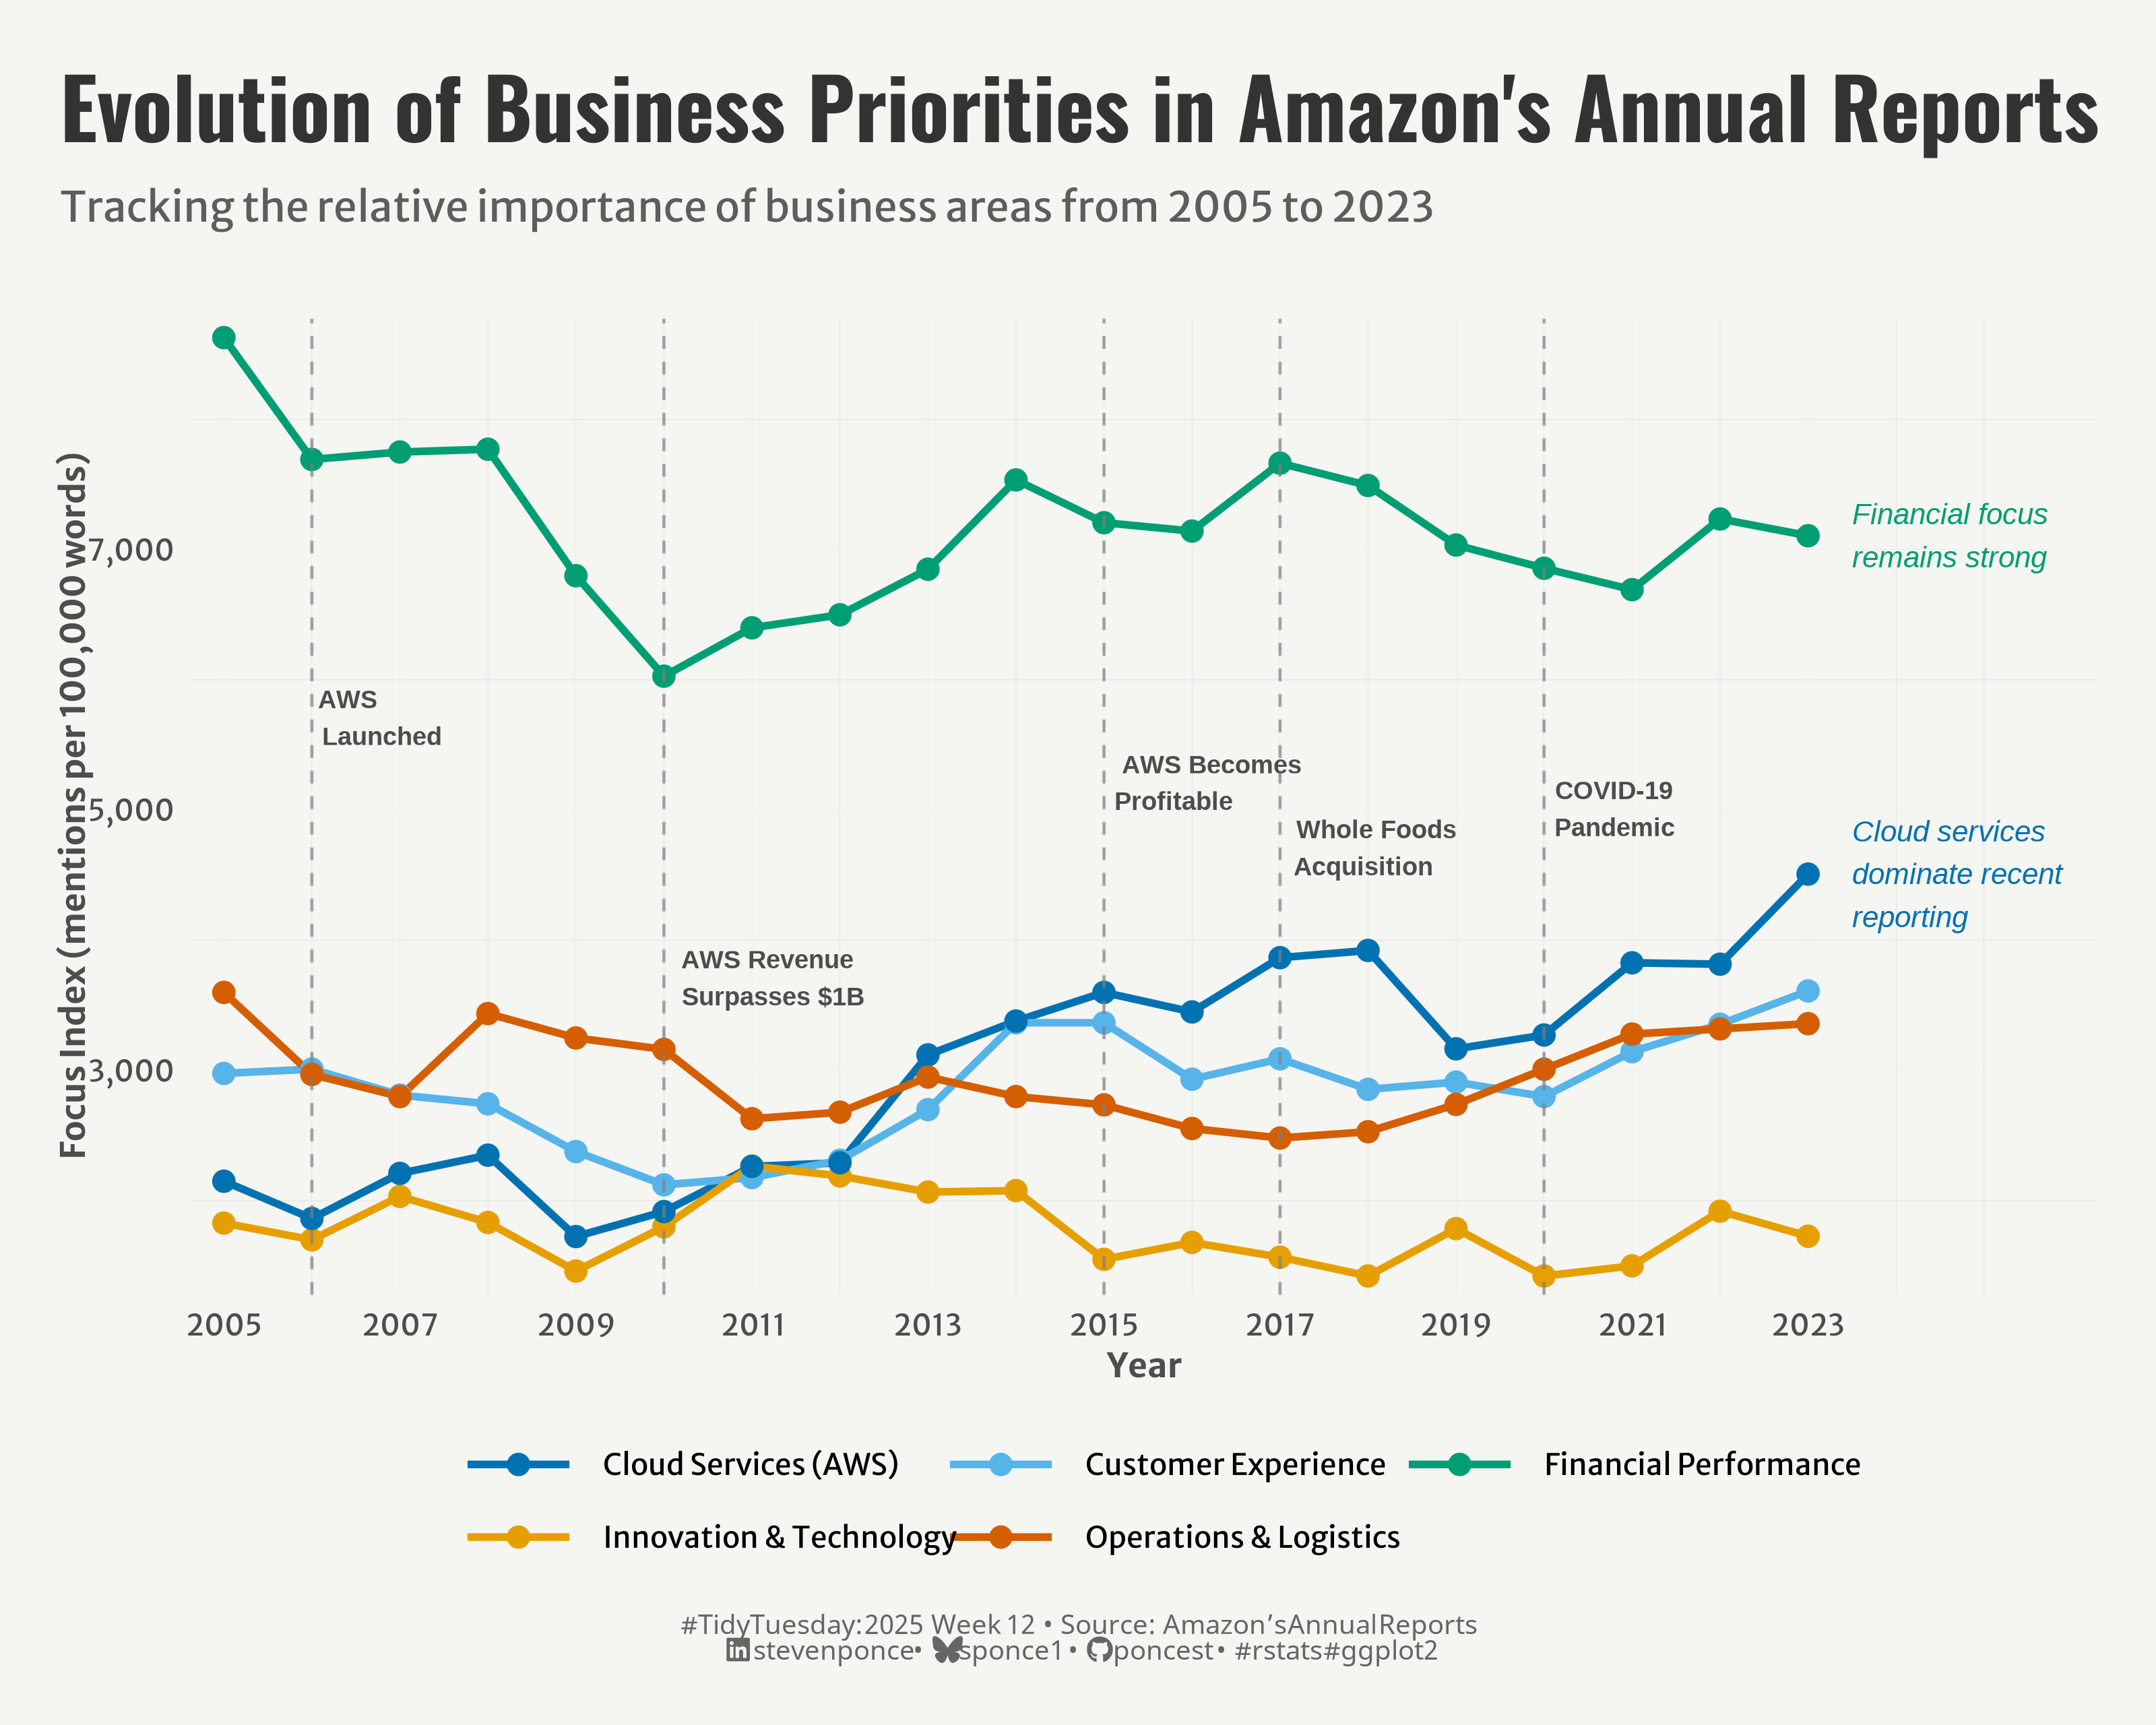{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"
## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
       tidyverse,      # Easily Install and Load the 'Tidyverse'
    ggtext,         # Improved Text Rendering Support for 'ggplot2'
    showtext,       # Using Fonts More Easily in R Graphs
    janitor,        # Simple Tools for Examining and Cleaning Dirty Data
    skimr,          # Compact and Flexible Summaries of Data
    scales,         # Scale Functions for Visualization
    glue,           # Interpreted String Literals
    here,           # A Simpler Way to Find Your Files
    camcorder,      # Record Your Plot History
    tidytext,       # Text Mining using 'dplyr', 'ggplot2', and Other Tidy Tools
    patchwork       # The Composer of Plots
    )
})

### |- figure size ----
gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  =  10,
    height =  8,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false
tt <- tidytuesdayR::tt_load(2025, week = 12)

report_words_clean <- tt$report_words_clean |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false
glimpse(report_words_clean)
skim(report_words_clean)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false
### |-  tidy data ----
text_df <- report_words_clean |>
    group_by(year, word) |>
    summarize(
        count = n(),
        .groups = "drop"
    )

# Define word categories with targeted keywords
focus_categories <- list(
    innovation = c("innovation", "innovative", "invent", "patent", "technology", "research",
                   "development", "ai", "machine", "learning", "automation"),
    customer = c("customer", "consumer", "satisfaction", "service", "experience", "value",
                 "delivery", "prime", "shopping", "retail", "personalization"),
    finance = c("revenue", "profit", "margin", "earning", "cost", "expense", "financial",
                "billion", "million", "investment", "growth", "cash", "flow", "capital"),
    cloud = c("aws", "cloud", "server", "compute", "storage", "database", "web", "services",
              "infrastructure", "platform", "hosting", "data"),
    operations = c("operations", "logistics", "fulfillment", "warehouse", "distribution",
                   "supply", "chain", "inventory", "shipping", "transportation", "facility")
)

# Calculate category indices
focus_indices <- map_dfr(names(focus_categories), function(category) {
    text_df |>
        filter(word %in% focus_categories[[category]]) |>
        group_by(year) |>
        summarize(
            word_count = sum(count),
            total_words = n(),
            index = word_count / total_words * 100,
            category = category,
            .groups = "drop"
        )
})

# Cleaner category label mapping
category_labels <- c(
    "innovation" = "Innovation & Technology",
    "customer" = "Customer Experience",
    "finance" = "Financial Performance",
    "cloud" = "Cloud Services (AWS)",
    "operations" = "Operations & Logistics"
)

# Key events/milestones for annotation
key_events <- tibble(
    year = c(2006, 2010, 2015, 2017, 2020),
    event = c("AWS\nLaunched", "AWS Revenue\nSurpasses $1B", "AWS Becomes\nProfitable", "Whole Foods\nAcquisition", "COVID-19\nPandemic"),
    index = c(5500, 3500, 5000, 4500, 4800),
    category = NA
)
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false
colors <- get_theme_colors(
    palette = c(
        "innovation" = "#E69F00",
        "customer" = "#56B4E9",
        "finance" = "#009E73",
        "cloud" = "#0072B2",
        "operations" = "#D55E00"
    )
)

### |-  titles and caption ----
title_text <- str_glue("Evolution of Business Priorities in Amazon's Annual Reports")
subtitle_text <- str_glue("Tracking the relative importance of business areas from 2005 to 2023")

# Create caption
caption_text <- create_social_caption(
    tt_year = 2025,
    tt_week = 12,
    source_text =  "Amazon's Annual Reports"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
    base_theme,
    theme(
        # Text styling
        plot.title = element_text(face = "bold", family = fonts$title, size = rel(1.14), margin = margin(b = 10)),
        plot.subtitle = element_text(family = fonts$subtitle, color = colors$text, size = rel(0.78), margin = margin(b = 20)),

        # Axis elements
        axis.title = element_text(color = colors$text, face = "bold", size = rel(0.8)),
        axis.text = element_text(color = colors$text, size = rel(0.7)),

        # Grid elements
        panel.grid.minor = element_line(color = "gray80", linewidth = 0.05),
        panel.grid.major = element_line(color = "gray80", linewidth = 0.02),

        # Legend elements
        legend.position = "bottom",
        legend.direction = "horizontal",
        legend.title = element_text(family = fonts$text, size = rel(0.8), face = "bold"),
        legend.text = element_text(family = fonts$text, size = rel(0.7)),

        # two-row legend
        legend.box.spacing = unit(0.4, "cm"),
        legend.key.width = unit(1.5, "cm"),
        legend.spacing.x = unit(0.2, "cm"),

        legend.box = "horizontal",
        legend.box.just = "left",

        # Plot margins
        plot.margin = margin(t = 20, r = 20, b = 20, l = 20),
    )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false
### |-  Plot  ----
p <- ggplot() +
    # Geoms
    geom_line(
        data = focus_indices,
        aes(x = year, y = index, color = category),
        linewidth = 1.2
    ) +
    geom_point(
        data = focus_indices,
        aes(x = year, y = index, color = category),
        size = 3
    ) +
    geom_vline(
        data = key_events,
        aes(xintercept = year),
        linetype = "dashed",
        color = "gray50",
        alpha = 0.7
    ) +
    geom_text(
        data = key_events,
        aes(x = year, y = index, label = event),
        hjust = -0.1,
        vjust = 0,
        size = 3,
        fontface = "bold",
        color = "gray30"
    ) +
    # Annotate
    annotate(
        "text",
        x = max(focus_indices$year) + 0.5,
        y = filter(focus_indices, year == max(year) & category == "cloud")$index,
        label = "Cloud services\ndominate recent\nreporting",
        hjust = 0,
        size = 3.5,
        fontface = "italic",
        color = colors$palette[4]
    ) +
    annotate(
        "text",
        x = max(focus_indices$year) + 0.5,
        y = filter(focus_indices, year == max(year) & category == "finance")$index,
        label = "Financial focus\nremains strong",
        hjust = 0,
        size = 3.5,
        fontface = "italic",
        color = colors$palette[3]
    ) +
    # Scales
    scale_color_manual(
        values = colors$palette,
        labels = category_labels,
        name = NULL
    ) +
    scale_x_continuous(
        breaks = seq(min(focus_indices$year), max(focus_indices$year), by = 2),
        expand = expansion(mult = c(0.02, 0.15))
    ) +
    scale_y_continuous(
        labels = function(x) format(x, big.mark = ","),
        expand = expansion(mult = c(0.02, 0.02))
    ) +
    # Labs
    labs(
        title = title_text,
        subtitle = subtitle_text,
        caption = caption_text,
        x = "Year",
        y = "Focus Index (mentions per 100,000 words)"
    ) +
    # Legend
    guides(
        color = guide_legend(
            nrow = 2,
            byrow = TRUE,
            override.aes = list(size = 3)
        )
    ) +
    # Theme
    theme(
        plot.title = element_text(
            size = rel(2),
            family = fonts$title,
            face = "bold",
            color = colors$title,
            lineheight = 1.1,
            margin = margin(t = 5, b = 5)
        ),
        plot.subtitle = element_text(
            size = rel(1),
            family = fonts$subtitle,
            color = alpha(colors$subtitle, 0.9),
            lineheight = 1.2,
            margin = margin(t = 5, b = 30)
        ),
        plot.caption = element_markdown(
            size   = rel(0.65),
            family = fonts$caption,
            color  = colors$caption,
            hjust  = 0.5,
            margin = margin(t = 10)
        )
    )
```
#### 7. Save
```{r}
#| label: save
#| warning: false
### |-  plot image ----
save_plot_patchwork(
  plot = p,
  type = "tidytuesday",
  year = 2025,
  week = 12,
  width = 10,
  height = 8
)
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_12.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_12.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 12: [Text Data From Amazon's Annual Reports](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-03-25)
:::
