---
title: "Analysis of 1,041 Terminated NSF Grants Totaling $613.26M"
subtitle: "Representing 1,2993.5 years years of lost research time across four distinct patterns of termination"
description: "Exploring patterns in NSF grants terminated in 2025 using K-means clustering to reveal four distinct groups based on funding amount, completion percentage, and remaining time, visualizing the impact on American scientific research."
author: "Steven Ponce"
date: "2025-05-04"
categories: ["TidyTuesday", "2025"]
tags: [
"NSF Grants", "K-means Clustering", "Science Funding", "Data Analysis",
"Grant Terminations", "Science Policy", "Research Impact",
"Funding Cuts", "TidyTuesday Challenge", "Data Storytelling"
]
image: "thumbnails/tt_2025_18.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
# filters:
# - social-share
# share:
# permalink: "https://stevenponce.netlify.app/data_visualizations/TidyTuesday/2025/tt_2025_18.html"
# description: "#TidyTuesday week 18: Visualizing patterns in 1,041 terminated NSF grants totaling $613M and representing nearly 1,300 years of interrupted research time."
#
# twitter: true
# linkedin: true
# email: true
# facebook: false
# reddit: false
# stumble: false
# tumblr: false
# mastodon: true
# bsky: true
---
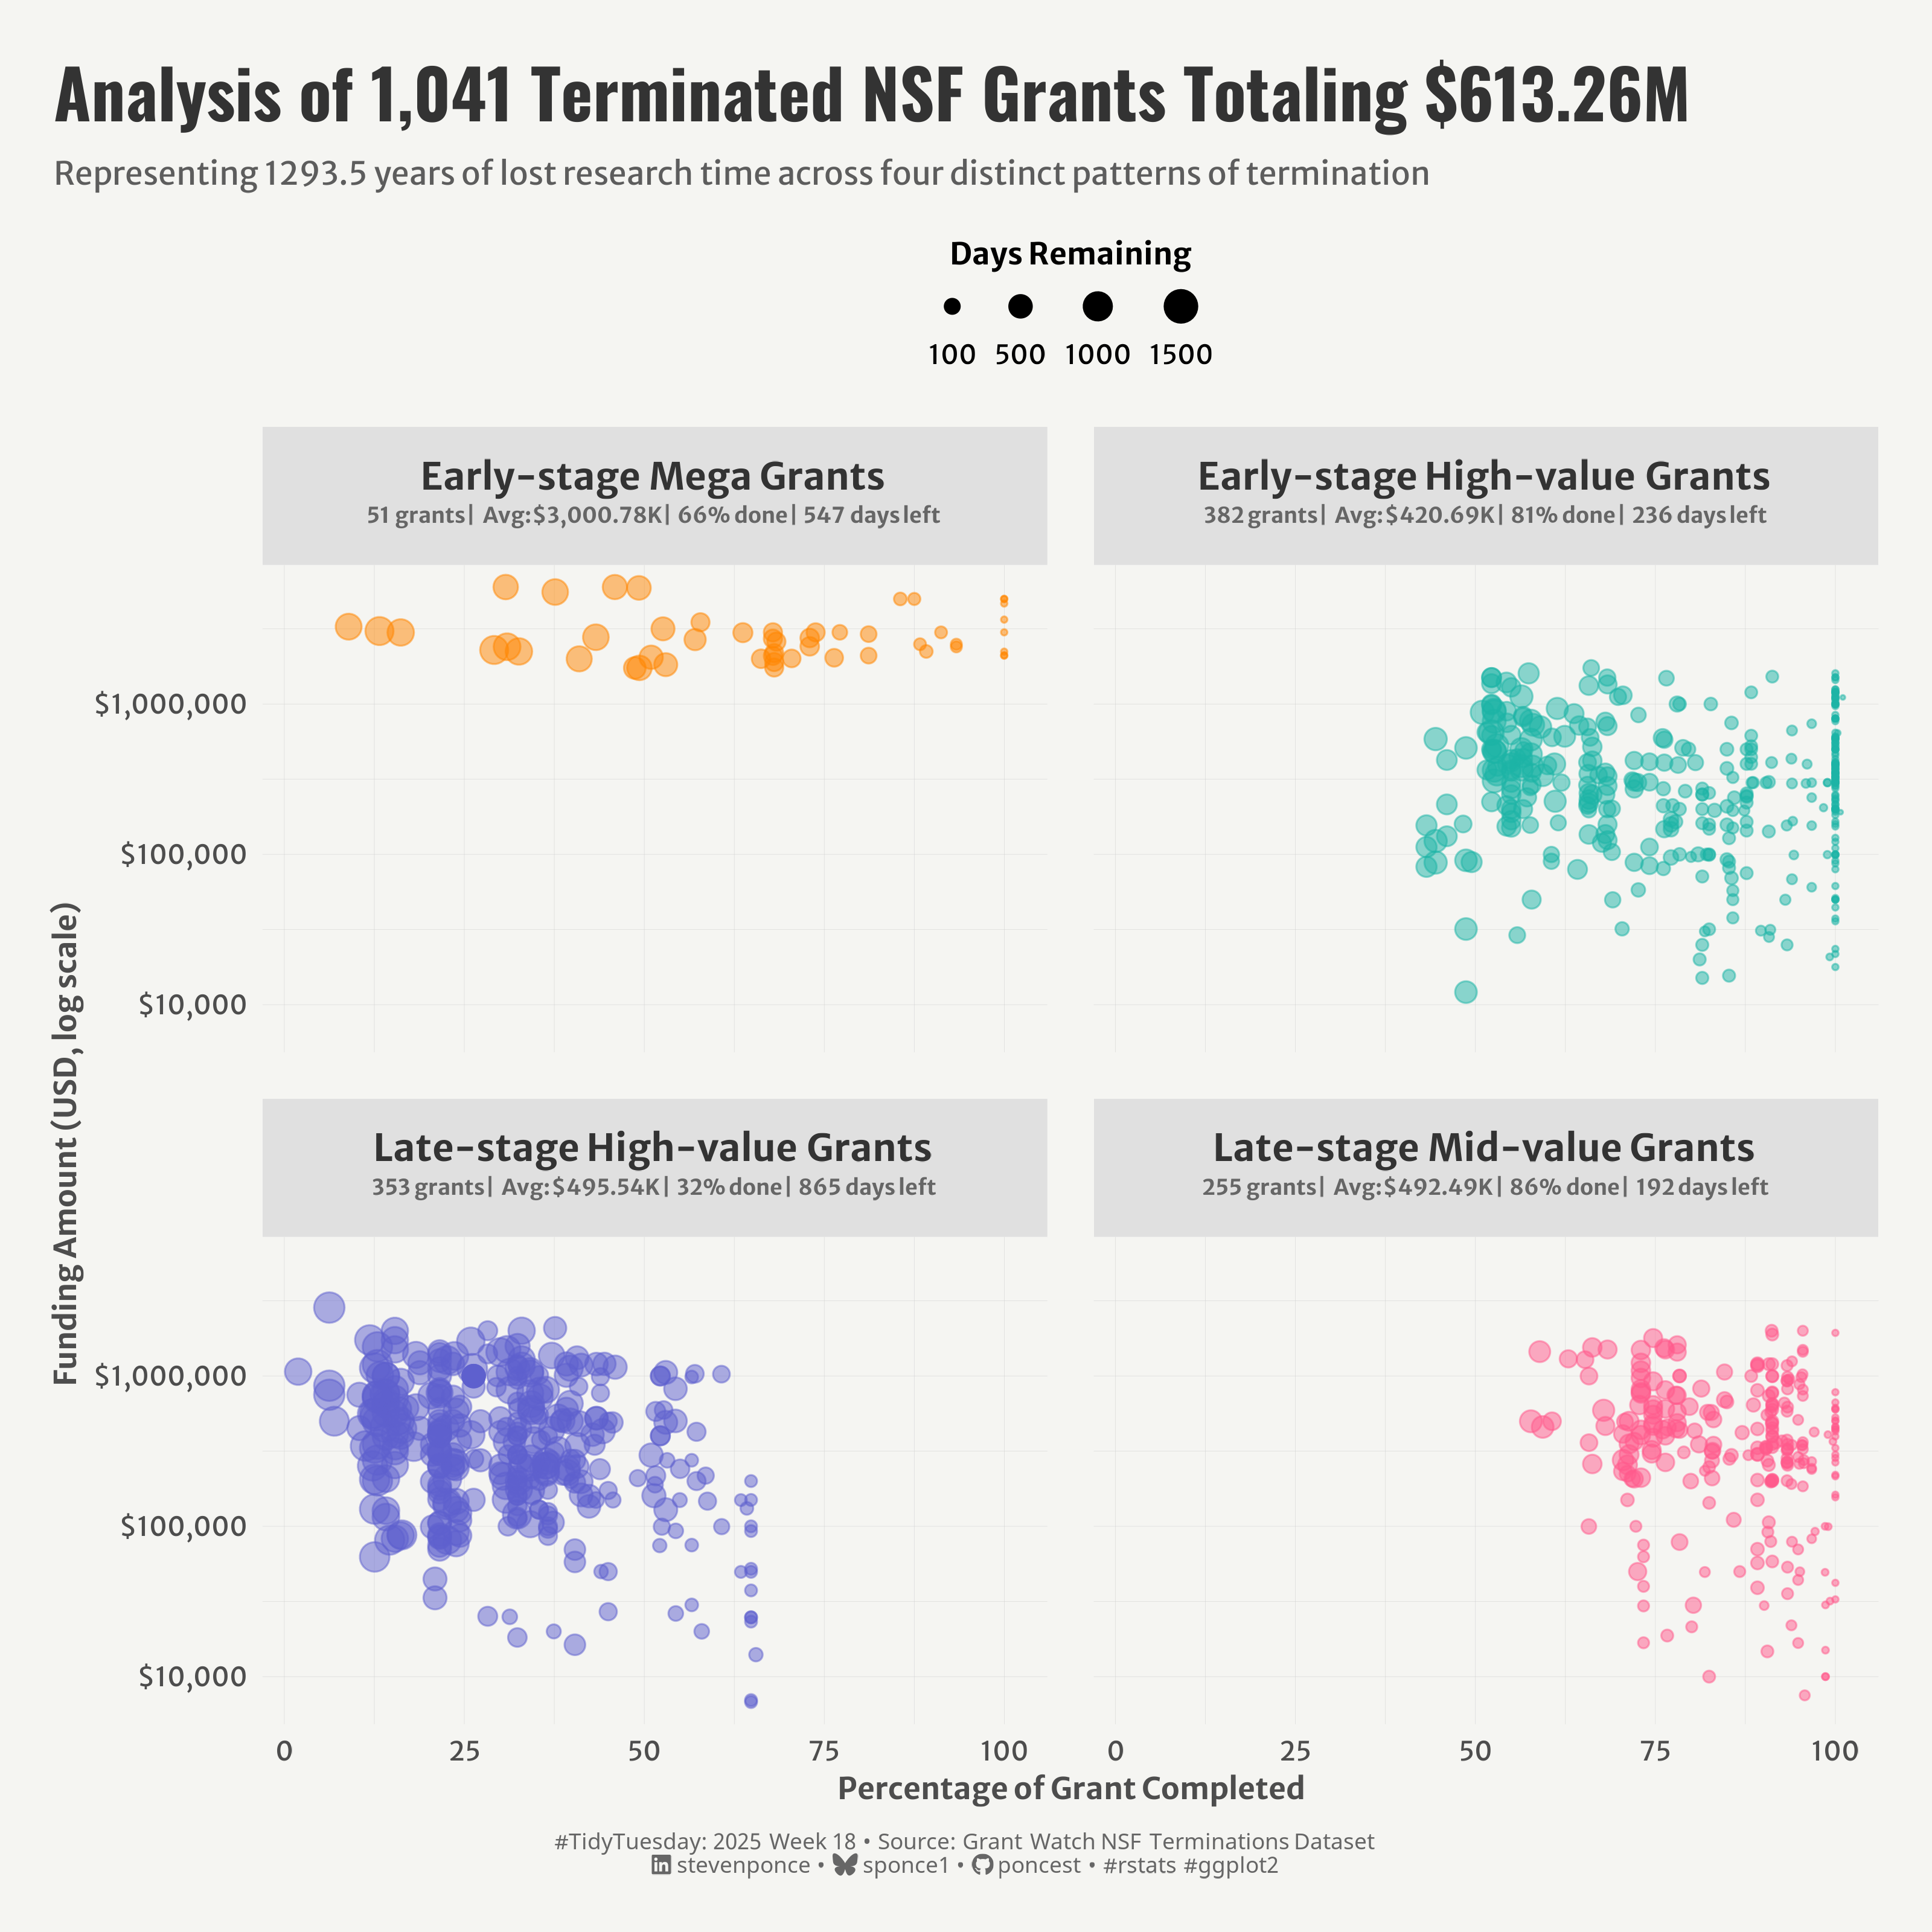{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
  tidyverse, # Easily Install and Load the 'Tidyverse'
  ggtext,    # Improved Text Rendering Support for 'ggplot2'
  showtext,  # Using Fonts More Easily in R Graphs
  janitor,   # Simple Tools for Examining and Cleaning Dirty Data
  skimr,     # Compact and Flexible Summaries of Data
  scales,    # Scale Functions for Visualization
  glue,      # Interpreted String Literals
  here,      # A Simpler Way to Find Your Files
  cluster,   # "Finding Groups in Data": Cluster Analysis Extended Rousseeuw et al.
  camcorder  # Record Your Plot History
    )
})

### |- figure size ----
gg_record(
    dir    = here::here("temp_plots"),
    device = "png",
    width  =  10,
    height =  10,
    units  = "in",
    dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

tt <- tidytuesdayR::tt_load(2025, week = 18)

nsf_terminations_raw <- tt$nsf_terminations |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(nsf_terminations_raw)
skim(nsf_terminations_raw)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

### |-  tidy data ----
nsf_terminations <- nsf_terminations_raw |>
  mutate(
    # Calculate how long the grant had been running before termination
    days_active = as.numeric(termination_letter_date - nsf_startdate),
    months_active = days_active / 30.44,
    years_active = months_active / 12,

    # Calculate how much time was cut short
    days_remaining = as.numeric(nsf_expected_end_date - termination_letter_date),
    months_remaining = days_remaining / 30.44, # 365.25/12 = 30.4375. 365.25 days per year to account for leap years
    years_remaining = months_remaining / 12,

    # Calculate percentage of grant period completed
    grant_duration_days = as.numeric(nsf_expected_end_date - nsf_startdate),
    pct_completed = days_active / grant_duration_days * 100,

    # Round dollar amounts
    funding_millions = usaspending_obligated / 1000000,

    # Create date variables
    term_year = year(termination_letter_date),
    term_month = month(termination_letter_date),
    term_day = day(termination_letter_date),
  )

set.seed(42) # seed for reproducibility
k <- 4 # Number of clusters

# Prepare data for clustering
cluster_data <- nsf_terminations |>
  select(
    usaspending_obligated, days_active, days_remaining,
    pct_completed, in_cruz_list
  ) |>
  mutate(
    in_cruz_list = as.numeric(in_cruz_list),
    # Scale the data
    across(where(is.numeric), ~ scale(.x)[, 1]),
    # Fill in missing values with mean (0 after scaling)
    across(everything(), ~ ifelse(is.na(.x), 0, .x))
  )

# Perform k-means clustering
kmeans_result <- kmeans(cluster_data, centers = k, nstart = 25)

# Add cluster assignments back to the original data
nsf_clusters <- nsf_terminations |>
  mutate(
    # Numeric clusters for calculation
    cluster_num = kmeans_result$cluster,
    # Descriptive labels
    cluster = case_when(
      kmeans_result$cluster == 1 ~ "Early-stage High-value Grants",
      kmeans_result$cluster == 2 ~ "Late-stage High-value Grants",
      kmeans_result$cluster == 3 ~ "Early-stage Mega Grants",
      kmeans_result$cluster == 4 ~ "Late-stage Mid-value Grants",
      TRUE ~ paste("Cluster", kmeans_result$cluster)
    )
  )

# Create detailed summary of each cluster for the table and titles
cluster_summary <- nsf_clusters |>
  group_by(cluster, cluster_num) |>
  summarize(
    count = n(),
    pct_of_total = n() / nrow(nsf_clusters) * 100,
    total_funding = sum(usaspending_obligated, na.rm = TRUE),
    avg_funding = mean(usaspending_obligated, na.rm = TRUE),
    median_funding = median(usaspending_obligated, na.rm = TRUE),
    avg_days_active = mean(days_active, na.rm = TRUE),
    avg_days_remaining = mean(days_remaining, na.rm = TRUE),
    avg_pct_completed = mean(pct_completed, na.rm = TRUE),
    pct_cruz_list = mean(in_cruz_list == TRUE, na.rm = TRUE) * 100,
    .groups = "drop"
  ) |>
  # Format values for presentation
  mutate(
    # Formatted values for tables
    formatted_count = scales::comma(count),
    formatted_pct = paste0(round(pct_of_total, 1), "%"),
    formatted_total = scales::dollar(total_funding),
    formatted_avg = scales::dollar(avg_funding, accuracy = 1),
    formatted_median = scales::dollar(median_funding),
    formatted_days_remaining = round(avg_days_remaining, 0),
    formatted_pct_completed = paste0(round(avg_pct_completed), "%"),
    formatted_cruz = paste0(round(pct_cruz_list, 1), "%"),

    # Create concise strip labels with key stats
    # Format: Main title + count | Avg $ | Completion % | Days left
    concise_label = paste0(
      cluster, "\n",
      count, " grants | Avg: ", scales::dollar(avg_funding, scale = 1 / 1000), "K | ",
      round(avg_pct_completed), "% done | ",
      round(avg_days_remaining), " days left"
    )
  )

# Calculate overall totals for data-driven title
overall_stats <- nsf_clusters |>
  summarize(
    total_count = n(),
    total_funding = sum(usaspending_obligated, na.rm = TRUE),
    avg_funding = mean(usaspending_obligated, na.rm = TRUE),
    total_days_remaining = sum(days_remaining, na.rm = TRUE) / 365.25 # Convert to years
  ) |>
  mutate(
    # Format for title
    formatted_total = scales::dollar(total_funding, scale = 1 / 1000000, suffix = "M"),
    formatted_count = scales::comma(total_count),
    formatted_years = round(total_days_remaining, 1)
  )

# Create enhanced data for plotting with strip labels from summary
nsf_clusters_plot <- nsf_clusters |>
  left_join(
    cluster_summary |> select(cluster, concise_label),
    by = "cluster"
  )
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
colors <- get_theme_colors(
  palette = c(
    "Early-stage High-value Grants" = "#1CB3A6",
    "Late-stage High-value Grants" = "#5E60CE",
    "Early-stage Mega Grants" = "#FF8500",
    "Late-stage Mid-value Grants" = "#FF5A8C"
  )
)

### |-  custom facet ordering ----
### |-  Add ordering to existing cluster_summary ----
# First, add an ordering field to the existing data
cluster_summary <- cluster_summary |>
  mutate(
    # Create a new column for custom ordering
    cluster_order = case_when(
      cluster == "Early-stage Mega Grants" ~ 1,
      cluster == "Early-stage High-value Grants" ~ 2,
      cluster == "Late-stage High-value Grants" ~ 3,
      cluster == "Late-stage Mid-value Grants" ~ 4,
      TRUE ~ 5
    )
  )

### |-  Generate formatted strip labels with richtext ----
# Create richtext labels with different formatting for title and details
cluster_summary <- cluster_summary |>
    mutate(
        # Keep the ordering from before
        cluster_order = case_when(
            cluster == "Early-stage Mega Grants" ~ 1,
            cluster == "Early-stage High-value Grants" ~ 2,
            cluster == "Late-stage High-value Grants" ~ 3,
            cluster == "Late-stage Mid-value Grants" ~ 4,
            TRUE ~ 5
        ),

        # Create a two-part rich text label with different styling
        richtext_label = paste0(
            # First line (cluster name) - larger and bold
            "<span style='font-size:14pt; font-weight:bold;'>",
            cluster,
            "</span><br>",
            # Second line (details) - smaller and regular weight
            "<span style='font-size:8pt; font-weight:normal; color:gray40;'>",
            count, " grants | Avg: ", scales::dollar(avg_funding, scale = 1/1000), "K | ",
            round(avg_pct_completed), "% done | ",
            round(avg_days_remaining), " days left",
            "</span>"
        )
    )

# Update the plot data with formatted labels
nsf_clusters_plot <- nsf_clusters |>
    left_join(
        cluster_summary |> select(cluster, richtext_label, cluster_order),
        by = "cluster"
    ) |>
    # Convert to factor with custom ordering
    mutate(
        richtext_label = factor(richtext_label,
                                levels = cluster_summary |>
                                    arrange(cluster_order) |>
                                    pull(richtext_label))
    )

### |-  titles and caption ----
title_text <- str_glue(
  "Analysis of ", overall_stats$formatted_count,
  " Terminated NSF Grants Totaling ", overall_stats$formatted_total
)
subtitle_text <- str_glue(
  "Representing ", overall_stats$formatted_years,
  " years of lost research time across four distinct patterns of termination"
)

# Create caption
caption_text <- create_social_caption(
  tt_year = 2025,
  tt_week = 18,
  source_text =  "Grant Watch NSF Terminations Dataset"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # Text styling
    plot.title = element_text(face = "bold", family = fonts$title, size = rel(1.14), margin = margin(b = 10)),
    plot.subtitle = element_text(family = fonts$subtitle, color = colors$text, size = rel(0.78), margin = margin(b = 20)),

    # Axis elements
    axis.title = element_text(color = colors$text, face = "bold", size = rel(0.8)),
    axis.text = element_text(color = colors$text, size = rel(0.7)),

    # Grid elements
    panel.grid.minor = element_line(color = "gray80", linewidth = 0.05),
    panel.grid.major = element_line(color = "gray80", linewidth = 0.05),

    # Legend elements
    legend.position = "top",
    legend.direction = "horizontal",
    legend.title = element_text(family = fonts$text, size = rel(0.8), face = "bold"),
    legend.text = element_text(family = fonts$text, size = rel(0.7)),

    # Style facet labels
    strip.text = element_text(size = rel(0.75), face = "bold",
                              color = colors$title, margin = margin(b = 8, t = 8)),

    # Add spacing
    panel.spacing = unit(1.2, "lines"),
    strip.background = element_rect(fill = "#e0e0e0", color = NA),

    # Plot margins
    plot.margin = margin(t = 20, r = 20, b = 20, l = 20),
  )
 )

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |-  Plot  ----
p <- ggplot(
  nsf_clusters_plot,
  aes(x = pct_completed, y = usaspending_obligated, color = cluster, size = days_remaining)
  ) +
  # Geoms
  geom_point(alpha = 0.5) +
  # Scales
  scale_y_log10(labels = label_dollar()) +
  scale_color_manual(values = colors$palette) +
  # Improved size scale with meaningful breaks
  scale_size_continuous(
    breaks = c(100, 500, 1000, 1500),
    labels = c("100", "500", "1000", "1500"),
    range = c(0.5, 5)
  ) +
  # Facets with ordered layout
    facet_wrap(~ richtext_label, nrow = 2) +
  # Labs
  labs(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    x = "Percentage of Grant Completed",
    y = "Funding Amount (USD, log scale)",
    size = "Days Remaining",
  ) +
  # Legend
  guides(
    # Remove the color legend
    color = "none",
    size = guide_legend(
      title.position = "top",
      override.aes = list(
        alpha = 1,
        stroke = 1,
        fill = NA,
        color = "black"
      ),
      direction = "horizontal",
      keywidth = unit(1, "lines"),
      keyheight = unit(1, "lines"),
      title.hjust = 0.5,
      label.position = "bottom"
    )
  ) +
  # Theme
  theme(
    plot.title = element_text(
      size = rel(1.8),
      family = fonts$title,
      face = "bold",
      color = colors$title,
      lineheight = 1.1,
      margin = margin(t = 5, b = 5)
    ),
    plot.subtitle = element_text(
      size = rel(0.85),
      family = fonts$subtitle,
      color = alpha(colors$subtitle, 0.9),
      lineheight = 1.2,
      margin = margin(t = 5, b = 10)
    ),
    plot.caption = element_markdown(
      size = rel(0.6),
      family = fonts$caption,
      color = colors$caption,
      hjust = 0.5,
      margin = margin(t = 10)
    ),
    legend.key = element_rect(fill = NA),
    strip.text = element_markdown(
        lineheight = 1.2,
        padding = margin(5, 5, 5, 5)
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot(
  plot = p,
  type = "tidytuesday",
  year = 2025,
  week = 18,
  width = 10,
  height = 10
)
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_18.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_18.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 18: [National Science Foundation Grant Terminations under the Trump Administration](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-05-06)
:::
