---
title: "Gender Differences in Color Ranking Accuracy"
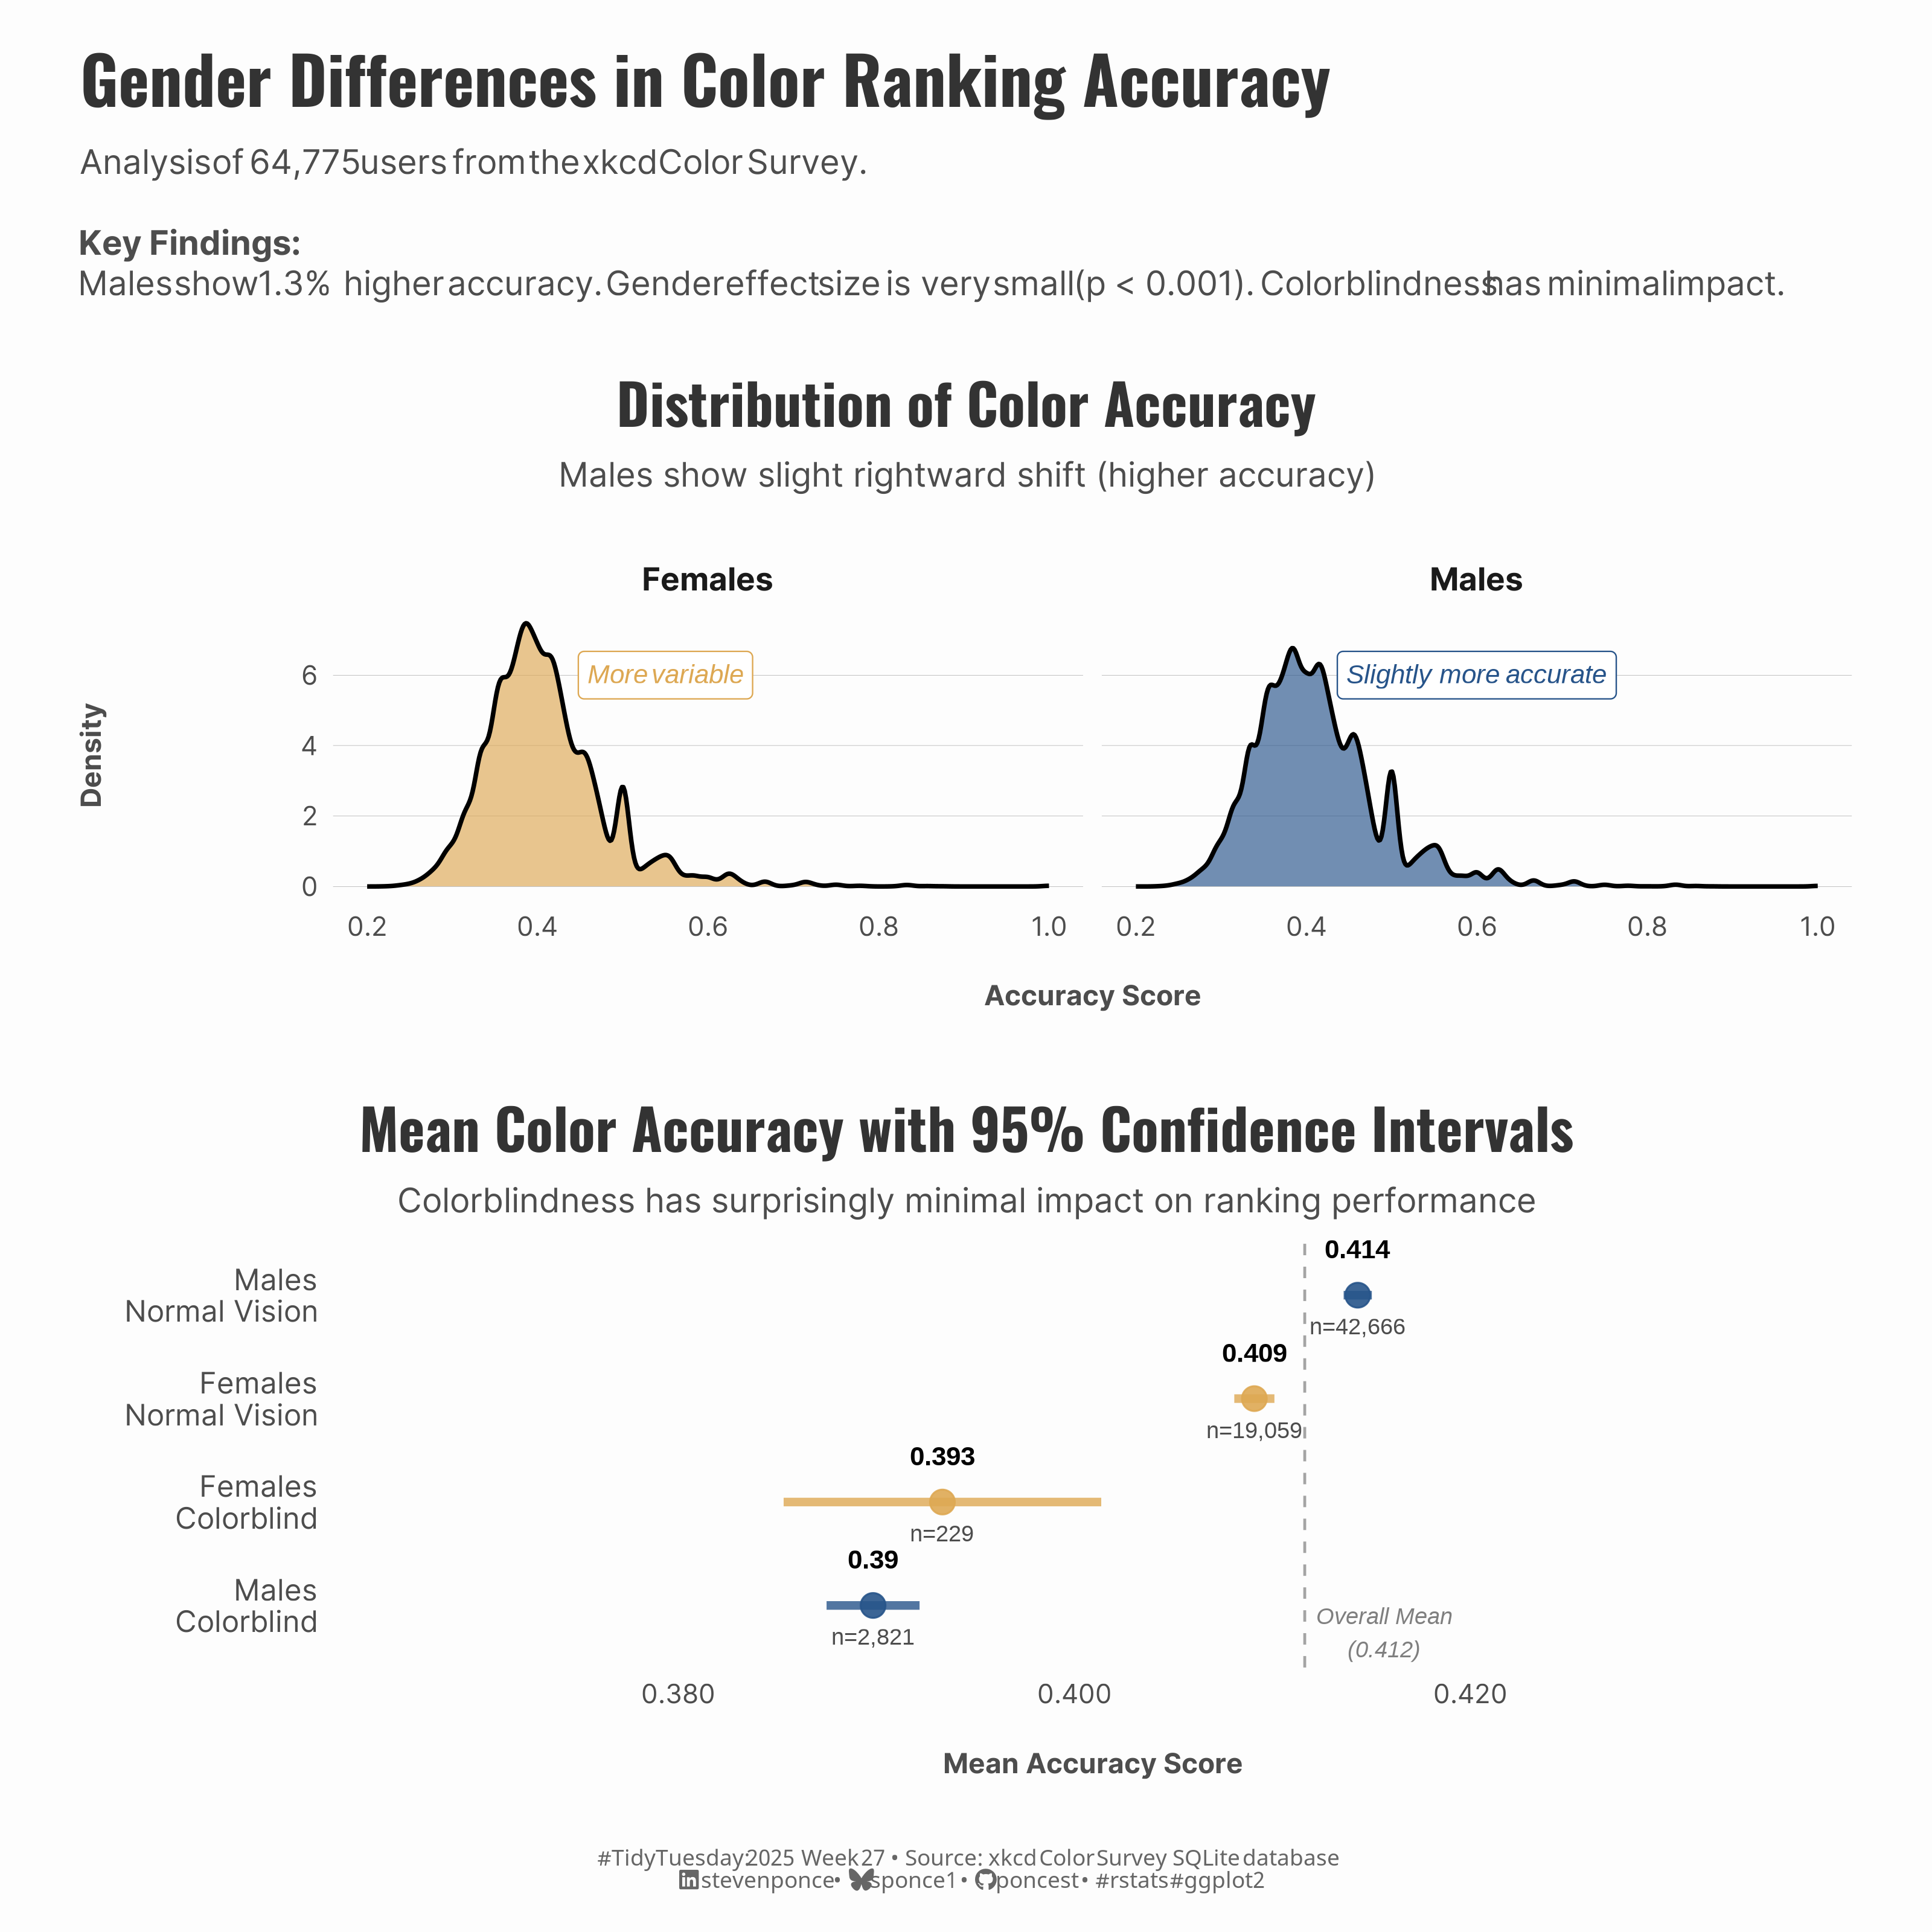
subtitle: "Analysis of ~64K users from the xkcd Color Survey."
description: "An analysis of gender differences in color ranking accuracy using data from the famous xkcd Color Survey. This study examines 64,775 users who ranked colors on a 1-5 scale, revealing statistically significant but practically small differences between groups. "
author: "Steven Ponce"
date: "2025-07-08"
categories: ["TidyTuesday", "2025"]
tags: [
"data-visualization",
"gender-differences",
"color-perception",
"statistical-analysis",
"effect-size",
"xkcd",
"cohen-d",
"confidence-intervals",
"survey-analysis",
"colorblindness",
"psychology",
"perception",
"ggplot2",
"patchwork"
]
image: "thumbnails/tt_2025_27.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
  tidyverse,  # Easily Install and Load the 'Tidyverse'
    ggtext,     # Improved Text Rendering Support for 'ggplot2'
    showtext,   # Using Fonts More Easily in R Graphs
    janitor,    # Simple Tools for Examining and Cleaning Dirty Data
    scales,     # Scale Functions for Visualization
    glue,       # Interpreted String Literals
    patchwork,  # The Composer of Plots
    effsize     # Efficient Effect Size Computation
  )})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
   width  = 10,
  height =  10,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

tt <- tidytuesdayR::tt_load(2025, week = 27)

answers <- tt$answers |> clean_names()
users <- tt$users |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(answers)
glimpse(users)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

# Data preparation
user_accuracy <- answers |>
  left_join(users, by = "user_id") |>
  filter(!is.na(y_chromosome), !is.na(colorblind)) |>
  group_by(user_id, y_chromosome, colorblind) |>
  summarise(
    avg_user_rank = mean(rank, na.rm = TRUE),
    accuracy_score = 1 / avg_user_rank,
    total_answers = n(),
    .groups = "drop"
  ) |>
  filter(total_answers >= 5)

# Plot 1 data
accuracy_by_groups <- user_accuracy |>
  mutate(
    chromosome_label = ifelse(y_chromosome == 1, "Males", "Females"),
    colorblind_label = ifelse(colorblind == 1, "Colorblind", "Normal Vision"),
    user_group = case_when(
      y_chromosome == 1 & colorblind == 0 ~ "Males\nNormal Vision",
      y_chromosome == 1 & colorblind == 1 ~ "Males\nColorblind",
      y_chromosome == 0 & colorblind == 0 ~ "Females\nNormal Vision",
      y_chromosome == 0 & colorblind == 1 ~ "Females\nColorblind"
    )
  ) |>
  filter(!is.na(user_group))

# Plot 2 data
group_stats <- accuracy_by_groups |>
  group_by(user_group) |>
  summarise(
    n = n(),
    mean_acc = mean(accuracy_score),
    median_acc = median(accuracy_score),
    se_acc = sd(accuracy_score) / sqrt(n()),
    ci_lower = mean_acc - 1.96 * se_acc,
    ci_upper = mean_acc + 1.96 * se_acc,
    .groups = "drop"
  ) |>
  mutate(
    gender = ifelse(str_detect(user_group, "Males"), "Males", "Females"),
    vision = ifelse(str_detect(user_group, "Colorblind"), "Colorblind", "Normal Vision")
  )

# key statistics

# overall mean for reference line
overall_mean <- mean(accuracy_by_groups$accuracy_score)

# t-test
gender_ttest <- t.test(accuracy_score ~ chromosome_label, data = accuracy_by_groups)

# Percentage difference
summary_stats <- accuracy_by_groups %>%
  group_by(chromosome_label, colorblind_label) %>%
  summarise(
    n = n(),
    mean_acc = mean(accuracy_score),
    .groups = "drop"
  )

male_mean <- summary_stats$mean_acc[summary_stats$chromosome_label == "Males" &
  summary_stats$colorblind_label == "Normal Vision"]
female_mean <- summary_stats$mean_acc[summary_stats$chromosome_label == "Females" &
  summary_stats$colorblind_label == "Normal Vision"]

percentage_diff <- ((male_mean - female_mean) / female_mean) * 100

# Effect size
gender_cohens_d <- cohen.d(
  accuracy_by_groups$accuracy_score,
  accuracy_by_groups$chromosome_label
)
cohens_d_value <- abs(gender_cohens_d$estimate)

# Descriptive variables
gender_sig <- ifelse(gender_ttest$p.value < 0.001, "p < 0.001",
                     ifelse(gender_ttest$p.value < 0.01, "p < 0.01",
                            ifelse(gender_ttest$p.value < 0.05, "p < 0.05",
                                   paste("p =", round(gender_ttest$p.value, 3)))))

gender_effect_desc <- ifelse(cohens_d_value < 0.2, "very small",
                             ifelse(cohens_d_value < 0.5, "small",
                                    ifelse(cohens_d_value < 0.8, "medium", "large")))
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
colors <- get_theme_colors(
  palette = c("#DDA853", "#27548A")
)

### |- titles and caption ----
title_text <- str_glue("Gender Differences in Color Ranking Accuracy")

subtitle_text <- str_glue(
    "Analysis of ", scales::comma(nrow(accuracy_by_groups)), " users from the xkcd Color Survey.<br><br>",
    "**Key Findings:**<br>",
    "Males show ", round(percentage_diff, 1), "% higher accuracy. ",
    "Gender effect size is ", gender_effect_desc, " (", gender_sig, "). ",
    "Colorblindness has minimal impact."
    )

caption_text <- create_social_caption(
  tt_year = 2025,
  tt_week = 27,
  source_text =  "xkcd Color Survey SQLite database"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # Axis elements
    axis.text = element_text(color = colors$text, size = rel(0.7)),
    axis.title.x = element_text(color = colors$text, face = "bold", size = rel(0.8), margin = margin(t = 15)),
    axis.title.y = element_text(color = colors$text, face = "bold", size = rel(0.8), margin = margin(r = 10)),

    # Grid elements
    panel.grid.major.y = element_line(color = "gray50", linewidth = 0.05),
    panel.grid.minor = element_blank(),
    panel.grid.major.x = element_blank(),

    # Legend elements
    legend.position = "plot",
    legend.title = element_text(family = fonts$tsubtitle, color = colors$text, size = rel(0.8), face = "bold"),
    legend.text = element_text(family = fonts$tsubtitle, color = colors$text, size = rel(0.7)),

    # Plot margin
    plot.margin = margin(t = 15, r = 15, b = 15, l = 15),
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

# Plot 1: Distribution plot
p1 <- ggplot(accuracy_by_groups, aes(x = accuracy_score, fill = chromosome_label)) +
  # Geoms
  geom_density(alpha = 0.65, size = 0.8) +
  # Annotations
  geom_richtext(
    data = tibble(
      accuracy_score = c(0.55, 0.6),
      y = c(6, 6),
      chromosome_label = c("Females", "Males"),
      label = c("More variable", "Slightly more accurate")
    ), aes(x = accuracy_score, y = y, label = label),
    inherit.aes = FALSE,
    size = 3.5, fontface = "italic",
    color = colors$palette
  ) +
  # Scales
  scale_fill_manual(
    values = colors$palette,
    name = "Group"
  ) +
  # Labs
  labs(
    title = "Distribution of Color Accuracy",
    subtitle = "Males show slight rightward shift (higher accuracy)",
    x = "Accuracy Score",
    y = "Density"
  ) +
  # Facets
  facet_wrap(~chromosome_label) +
  # Theme
  theme(
    legend.position = "none",
    panel.grid.minor = element_blank(),
    strip.text = element_text(face = "bold", size = 12),
    plot.title = element_text(
      size = rel(1.5),
      family = fonts$title,
      face = "bold",
      color = colors$title,
      hjust = 0.5,
      lineheight = 1.1,
      margin = margin(t = 5, b = 5)
    ),
    plot.subtitle = element_text(
      size = rel(0.9),
      family = fonts$subtitle,
      color = colors$subtitle,
      hjust = 0.5,
      lineheight = 1.2,
      margin = margin(t = 5, b = 20)
    ),
  )

# Plot 2: dot-range plot
p2 <- ggplot(group_stats, aes(x = mean_acc, y = reorder(user_group, mean_acc))) +
  # Geoms
  geom_segment(
    aes(
      x = ci_lower, xend = ci_upper,
      y = user_group, yend = user_group,
      color = gender
    ),
    size = 1.5, alpha = 0.8
  ) +
  geom_point(aes(color = gender), size = 4, alpha = 0.9) +
  geom_text(aes(label = paste0("n=", scales::comma(n))),
    hjust = 0.5, vjust = 2.5, size = 3, color = "gray30"
  ) +
  geom_text(aes(label = round(mean_acc, 3)),
    hjust = 0.5, vjust = -2, size = 3.5, fontface = "bold"
  ) +
  geom_vline(
    xintercept = overall_mean,
    linetype = "dashed", color = "gray50", alpha = 0.7
  ) +
  # Annotate
  annotate("text",
    x = overall_mean + 0.004, y = 0.5,
    label = paste0("Overall Mean\n(", round(overall_mean, 3), ")"),
    hjust = 0.5, vjust = 0, size = 3,
    color = "gray50", fontface = "italic"
  ) +
  # Scales
  scale_color_manual(
    values = colors$palette,
    name = "Gender"
  ) +
  scale_x_continuous(
    labels = scales::number_format(accuracy = 0.001),
    limits = c(
      min(group_stats$ci_lower) * 0.95,
      max(group_stats$ci_upper) * 1.05
    )
  ) +
  # Labs
  labs(
    title = "Mean Color Accuracy with 95% Confidence Intervals",
    subtitle = "Colorblindness has surprisingly minimal impact on ranking performance",
    x = "Mean Accuracy Score",
    y = NULL
  ) +
  # Theme
  theme(
    legend.position = "plot",
    panel.grid.minor = element_blank(),
    panel.grid.major.y = element_blank(),
    axis.text.y = element_text(size = 11),
    plot.title = element_text(
      size = rel(1.5),
      family = fonts$title,
      face = "bold",
      color = colors$title,
      hjust = 0.5,
      lineheight = 1.1,
      margin = margin(t = 5, b = 5)
    ),
    plot.subtitle = element_text(
      size = rel(0.9),
      family = fonts$subtitle,
      color = colors$subtitle,
      hjust = 0.5,
      lineheight = 1.2,
      margin = margin(t = 5, b = 5)
    ),
  )

# Combine plots
combined_plot <- p1 / p2 +
  plot_layout(heights = c(0.8, 1.2))

combined_plot <- combined_plot +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        size = rel(1.75),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.1,
        margin = margin(t = 5, b = 5)
      ),
      plot.subtitle = element_markdown(
        size = rel(0.9),
        family = fonts$subtitle,
        color = colors$subtitle,
        lineheight = 1.2,
        margin = margin(t = 5, b = 10)
      ),
      plot.caption = element_markdown(
        size = rel(0.6),
        family = fonts$caption,
        color = colors$caption,
        hjust = 0.5,
        margin = margin(t = 10)
      )
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  plot = combined_plot,
  type = "tidytuesday",
  year = 2025,
  week = 27,
  width  = 10,
  height = 10
)
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_27.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_27.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 27: \[The xkcd Color Survey Results\](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-07-08)
:::
