---
title: "Netflix Content Viewing Velocity Analysis (Jul to Dec 2023)"
subtitle: "Strategic insights into audience capture patterns and performance metrics"
description: "An in-depth analysis of Netflix content performance using TidyTuesday data, examining how viewing velocity (views per day) changes over time for movies vs shows. Features data-driven insights into content lifecycle patterns, audience capture rates, and strategic implications for content marketing timing."
author: "Steven Ponce"
date: "2025-07-28"
categories: ["TidyTuesday", "2025"]
tags: [
"netflix",
"streaming-analytics",
"content-performance",
"velocity-analysis",
"audience-engagement",
"media-strategy",
"content-lifecycle",
"performance-metrics",
"business-intelligence",
"entertainment-data",
"viewing-patterns",
"data-storytelling",
"executive-dashboard",
"ggplot2",
"patchwork"
]
image: "thumbnails/tt_2025_30.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
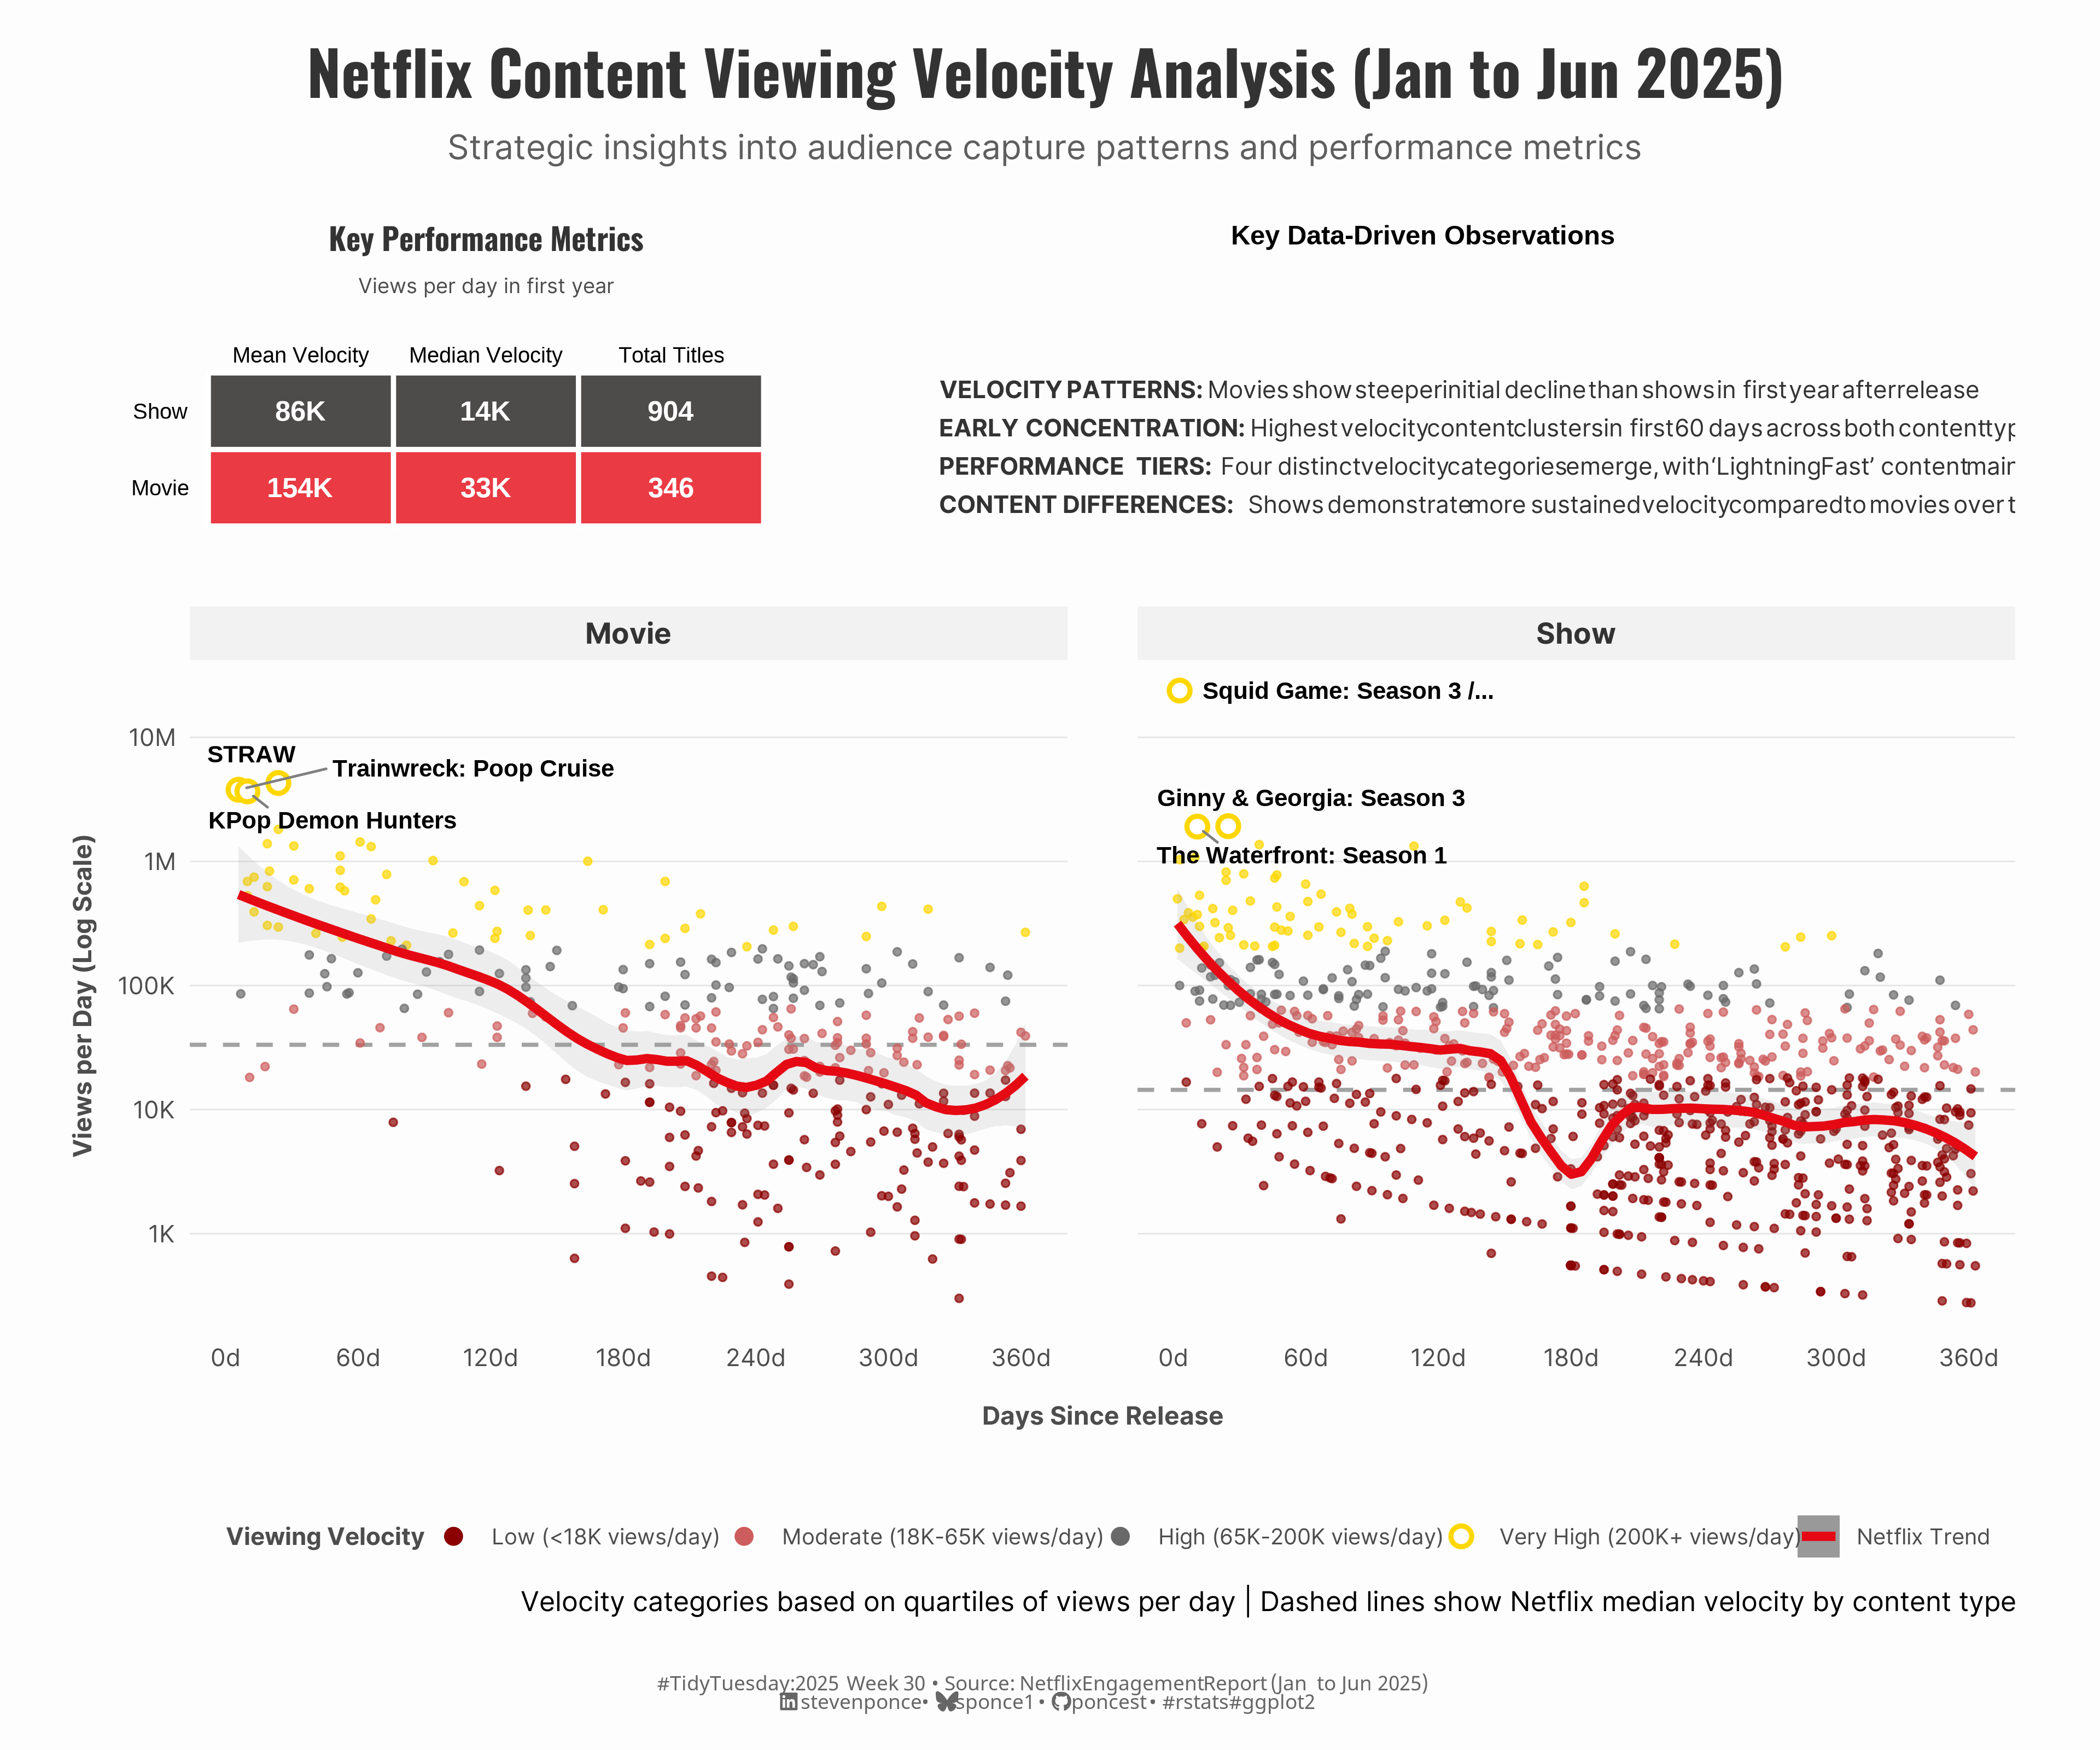{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
    tidyverse,  # Easily Install and Load the 'Tidyverse'
    ggtext,     # Improved Text Rendering Support for 'ggplot2'
    showtext,   # Using Fonts More Easily in R Graphs
    janitor,    # Simple Tools for Examining and Cleaning Dirty Data
    scales,     # Scale Functions for Visualization
    glue,       # Interpreted String Literals
    patchwork   # The Composer of Plots
  )})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
  width  = 12,
  height = 10,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

tt <- tidytuesdayR::tt_load(2025, week = 30)

movies <- tt$movies |> clean_names()
shows <- tt$shows |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(movies)
glimpse(shows)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

# Function to parse runtime from "XH YM ZS" format to minutes
parse_runtime <- function(runtime_str) {
  # Extract hours, minutes, seconds using regex
  hours <- str_extract(runtime_str, "\\d+(?=H)") |>
    as.numeric() |>
    replace_na(0)
  minutes <- str_extract(runtime_str, "\\d+(?=M)") |>
    as.numeric() |>
    replace_na(0)
  seconds <- str_extract(runtime_str, "\\d+(?=S)") |>
    as.numeric() |>
    replace_na(0)

  # Convert to total minutes
  total_minutes <- hours * 60 + minutes + seconds / 60
  return(total_minutes)
}

# Generic function to clean and prepare content data
clean_content_data <- function(df, content_type_label) {
  df |>
    mutate(
      # Parse runtime to minutes
      runtime_minutes = parse_runtime(runtime),

      # Create content type
      content_type = content_type_label,

      # Extract release year and month
      release_year = year(release_date),
      release_month = month(release_date, label = TRUE),
      release_quarter = quarter(release_date),

      # Calculate days since release (using latest report date as reference)
      # Define reference date once if it's constant
      report_date = as.Date("2025-06-30"),
      days_since_release = as.numeric(report_date - release_date),

      # Create age categories
      age_category = case_when(
        days_since_release <= 30 ~ "Very Recent (0-30 days)",
        days_since_release <= 90 ~ "Recent (31-90 days)",
        days_since_release <= 365 ~ "Less than 1 year",
        days_since_release <= 730 ~ "1-2 years",
        TRUE ~ "2+ years"
      ),

      # Global availability factor
      available_globally = factor(available_globally, levels = c("Yes", "No")),

      # Views per million hours (efficiency metric)
      views_per_million_hours = views / (hours_viewed / 1e6),

      # Log transformations for better visualization
      log_hours_viewed = log10(hours_viewed + 1),
      log_views = log10(views + 1)
    ) |>
    # Remove the temporary 'report_date' column
    select(-report_date)
}

# Clean and prepare movies and shows data
movies_clean <- clean_content_data(movies, "Movie")
shows_clean <- clean_content_data(shows, "Show")

# Combine datasets
combined_data <- bind_rows(movies_clean, shows_clean)

# Housekeeping
rm(movies, movies_clean, shows, shows_clean)

# Calculate viewing velocity (views per day since release)
velocity_data <- combined_data |>
    filter(days_since_release > 0, days_since_release <= 365) |>
    mutate(
        views_per_day = views / days_since_release,
        velocity_category = case_when(
            views_per_day >= 200000 ~ "Very High (200K+ views/day)",
            views_per_day >= 65000 ~ "High (65K-200K views/day)",
            views_per_day >= 18000 ~ "Moderate (18K-65K views/day)",
            TRUE ~ "Low (<18K views/day)"
        ),
        velocity_category = factor(velocity_category,
                                   levels = c("Low (<18K views/day)", "Moderate (18K-65K views/day)",
                                              "High (65K-200K views/day)", "Very High (200K+ views/day)")
        )
    )

# Calculate Netflix-specific benchmarks (from the actual data)
netflix_benchmarks <- velocity_data |>
  group_by(content_type) |>
  summarise(
    median_velocity = median(views_per_day, na.rm = TRUE),
    p75_velocity = quantile(views_per_day, 0.75, na.rm = TRUE),
    p90_velocity = quantile(views_per_day, 0.9, na.rm = TRUE),
    .groups = "drop"
  )

# Identify top performers for annotation
top_performers <- velocity_data |>
  group_by(content_type) |>
  slice_max(views_per_day, n = 3) |>
  ungroup() |>
  mutate(title_clean = str_trunc(title, 25))

# Calculate key statistics for summary box
summary_stats <- velocity_data |>
  group_by(content_type) |>
  summarise(
    total_titles = n(),
    median_velocity = median(views_per_day, na.rm = TRUE),
    mean_velocity = mean(views_per_day, na.rm = TRUE),
    peak_day = days_since_release[which.max(views_per_day)],
    .groups = "drop"
  ) |>
  mutate(
    median_velocity_formatted = case_when(
      median_velocity >= 1e6 ~ paste0(round(median_velocity / 1e6, 1), "M"),
      median_velocity >= 1e3 ~ paste0(round(median_velocity / 1e3, 0), "K"),
      TRUE ~ as.character(round(median_velocity, 0))
    ),
    mean_velocity_formatted = case_when(
      mean_velocity >= 1e6 ~ paste0(round(mean_velocity / 1e6, 1), "M"),
      mean_velocity >= 1e3 ~ paste0(round(mean_velocity / 1e3, 0), "K"),
      TRUE ~ as.character(round(mean_velocity, 0))
    )
  )

# KPI data
summary_data <- summary_stats |>
  mutate(
    total_titles = as.character(total_titles)
  ) |>
  pivot_longer(
    cols = c(median_velocity_formatted, mean_velocity_formatted, total_titles),
    names_to = "metric", values_to = "value"
  ) |>
  mutate(
    metric_clean = case_when(
      metric == "median_velocity_formatted" ~ "Median Velocity",
      metric == "mean_velocity_formatted" ~ "Mean Velocity",
      metric == "total_titles" ~ "Total Titles"
    )
  )
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
colors <- get_theme_colors(
  palette = c(
      # Scatter
      "Low (<18K views/day)" = "#8B0000",
      "Moderate (18K-65K views/day)" = "#CD5C5C",
      "High (65K-200K views/day)" = "#696969",
      "Very High (200K+ views/day)" = "#FFD700",
      "Netflix Trend" = "#E50914",

      # KPI
      "Movie" = "#E50914",
      "Show" = "#221F1F"
  )
)

### |- titles and caption ----
title_text <- str_glue("Netflix Content Viewing Velocity Analysis (Jan to Jun 2025)")
subtitle_text <- str_glue("Strategic insights into audience capture patterns and performance metrics")

caption_text <- create_social_caption(
  tt_year = 2025,
  tt_week = 30,
  source_text =  "Netflix Engagement Report (Jan to Jun 2025)"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----

# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # Text styling
    plot.title = element_text(face = "bold", family = fonts$title, size = rel(1.14), color  = colors$title, margin = margin(b = 10)),
    plot.subtitle = element_text(family = fonts$subtitle, color = colors$subtitle, size = rel(0.78), margin = margin(b = 20)),

    # Axis elements
    axis.line = element_blank(),
    axis.ticks = element_blank(),

    # Grid elements
    panel.grid.major.y = element_line(color = "gray90",linetype = "solid", linewidth = 0.3),
    panel.grid.minor.y = element_blank(),
    panel.grid.major.x = element_blank(),
    panel.grid.minor.x = element_blank(),

    # Axis elements
    axis.text = element_text(color = colors$text, size = rel(0.7)),
    axis.title.x = element_text(color = colors$text, face = "bold", size = rel(0.8), margin = margin(t = 15)),
    axis.title.y = element_text(color = colors$text, face = "bold", size = rel(0.8), margin = margin(r = 10)),

    # Legend elements
    legend.position = "plot",
    legend.title = element_text(family = fonts$tsubtitle, color = colors$text, size = rel(0.8), face = "bold"),
    legend.text = element_text(family = fonts$tsubtitle, color = colors$text, size = rel(0.7)),

    # Plot margin
    plot.margin = margin(t = 15, r = 15, b = 15, l = 15),
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

# Scatter Plot ----
scatter_plot <- velocity_data |>
  ggplot(aes(x = days_since_release, y = views_per_day)) +

  # Geoms
  geom_hline(
    data = netflix_benchmarks, aes(yintercept = median_velocity),
    linetype = "dashed", alpha = 0.6, color = "gray40", size = 0.8
  ) +
  geom_point(aes(color = velocity_category), alpha = 0.7, size = 1.2) +
  geom_smooth(aes(color = "Netflix Trend"),
    method = "loess", se = TRUE,
    alpha = 0.15, size = 1.8, span = 0.3
  ) +
  geom_point(
    data = top_performers, aes(color = velocity_category),
    size = 3, shape = 21, stroke = 1.5, fill = "white"
  ) +
  ggrepel::geom_text_repel(
    data = top_performers,
    aes(label = title_clean),
    size = 3.5,
    fontface = "bold",
    box.padding = 0.5,
    point.padding = 0.3,
    segment.color = "gray50",
    segment.size = 0.5,
    max.overlaps = 6,
    force = 2
  ) +
  # Scales
  scale_color_manual(
    name = "Viewing Velocity",
    values = colors$palette,
    guide = guide_legend(override.aes = list(size = 3, alpha = 1))
  ) +
  scale_y_log10(
    labels = function(x) {
      case_when(
        x >= 1e6 ~ paste0(round(x / 1e6, 1), "M"),
        x >= 1e3 ~ paste0(round(x / 1e3, 0), "K"),
        TRUE ~ as.character(round(x, 0))
      )
    },
    breaks = c(1e3, 1e4, 1e5, 1e6, 1e7),
    minor_breaks = NULL
  ) +
  scale_x_continuous(
    breaks = seq(0, 365, 60),
    labels = function(x) paste0(x, "d"),
    minor_breaks = seq(0, 365, 30)
  ) +
  # Labs
  labs(
    x = "Days Since Release",
    y = "Views per Day (Log Scale)",
    caption = "Velocity categories based on quartiles of views per day | Dashed lines show Netflix median velocity by content type"
  ) +
  # Facet by content type
  facet_wrap(~content_type) +
  # Theme
  theme(
    # Facet formatting
    strip.text = element_text(size = 12, face = "bold", color = "gray20"),
    strip.background = element_rect(fill = "gray95", color = NA),
    panel.spacing.x = unit(2, "lines"),

    # Legend formatting
    legend.position = "bottom",
    legend.title = element_text(size = 10, face = "bold"),
    legend.text = element_text(size = 9),
    legend.box.margin = margin(t = 15),
  )

# KPI Plot ----
kpi_plot <- summary_data |>
  ggplot(aes(x = metric_clean, y = content_type, fill = content_type)) +
  # Geoms
  geom_tile(alpha = 0.8, color = "white", size = 1) +
  geom_text(aes(label = value), size = 4, fontface = "bold", color = "white") +
  # Scales
  scale_x_discrete(position = "top") +
  scale_fill_manual(values = colors$palette) +
  # Labs
  labs(
    title = "Key Performance Metrics",
    subtitle = "Views per day in first year"
  ) +
  # Theme
  theme_void() +
  theme(
    plot.title = element_text(
      face = "bold", family = fonts$title, size = rel(1.14),
      color = colors$title, margin = margin(b = 10), hjust = 0.5
    ),
    plot.subtitle = element_text(
      family = fonts$subtitle, color = colors$subtitle,
      size = rel(0.78), margin = margin(b = 20), , hjust = 0.5
    ),
    plot.caption = element_markdown(
        size = rel(0.6),
        family = fonts$caption,
        color = colors$caption,
        hjust = 0.5,
        margin = margin(t = 10)
    ),
    axis.text.y = element_text(size = 9),
    axis.text.x.top = element_text(size = 9, hjust = 0.5),
    legend.position = "none",
  )

# Insight Plot ----
insights_plot <-
  tibble(
    insight = c(
      "**VELOCITY PATTERNS:** Movies show steeper initial decline than shows in first year after release",
      "**EARLY CONCENTRATION:** Highest velocity content clusters in first 60 days across both content types",
      "**PERFORMANCE TIERS:** Four distinct velocity categories emerge, with 'Lightning Fast' content maintaining higher rates",
      "**CONTENT DIFFERENCES:** Shows demonstrate more sustained velocity compared to movies over time"
    ),
    x = c(1, 1, 1, 1),
    y = c(4, 3, 2, 1)
  ) |>
  ggplot(aes(x = x, y = y)) +
  geom_richtext(aes(label = insight),
    hjust = 0, size = 3.5,
    color = "gray20", lineheight = 1.2, family = fonts$text,
    fill = NA, label.color = NA
  ) +
  xlim(0.5, 12) +
  ylim(0.5, 4.5) +
  labs(title = "Key Data-Driven Observations") +
  theme_void() +
  theme(
    plot.title = element_text(size = rel(1), face = "bold", hjust = 0.5, margin = margin(b = 10)),
    plot.margin = margin(15, 20, 15, 20),
    # plot.background = element_rect(fill = "gray97", color = "gray90", linewidth = 0.5)
  )

# Combined Plot ----
top_panel <- (kpi_plot | insights_plot) +
    plot_layout(widths = c(1, 2))

combined_plots <- top_panel / scatter_plot +
    plot_layout(heights = c(1, 4))

combined_plots <- combined_plots +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        size = rel(1.8),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.1,
        hjust = 0.5,
        margin = margin(t = 5, b = 5)
      ),
      plot.subtitle = element_text(
        size = rel(1),
        family = fonts$subtitle,
        color = alpha(colors$subtitle, 0.9),
        lineheight = 1.2,
        hjust = 0.5,
        margin = margin(t = 5, b = 10)
      ),
      plot.caption = element_markdown(
        size = rel(0.6),
        family = fonts$caption,
        color = colors$caption,
        hjust = 0.5,
        margin = margin(t = 10)
      )
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  plot = combined_plots,
  type = "tidytuesday",
  year = 2025,
  week = 30,
  width  = 12,
  height = 10
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_30.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_30.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 30: \[What have we been watching on Netflix?\](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-07-29)
:::
