---
title: "Regional evolution of extreme weather attribution science"
subtitle: "How different regions developed attribution research over time (2010–2024)"
description: "Regional analysis of extreme weather attribution science development (2010-2024) reveals distinct patterns in research volume and rapid attribution methodology adoption across global regions. Using normalized comparisons of TidyTuesday data, the visualization shows how some regions emerged as early adopters while others maintained traditional approaches."
author: "Steven Ponce"
date: "2025-08-12"
categories: ["TidyTuesday", "2025"]
tags: [
"extreme weather",
"climate attribution",
"regional analysis",
"time series",
"faceted visualization",
"normalized comparison",
"rapid attribution",
"climate science",
"research trends",
"scientific methodology",
"carbon brief",
"ggplot2",
"data normalization",
"moving averages"
]
image: "thumbnails/tt_2025_32.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
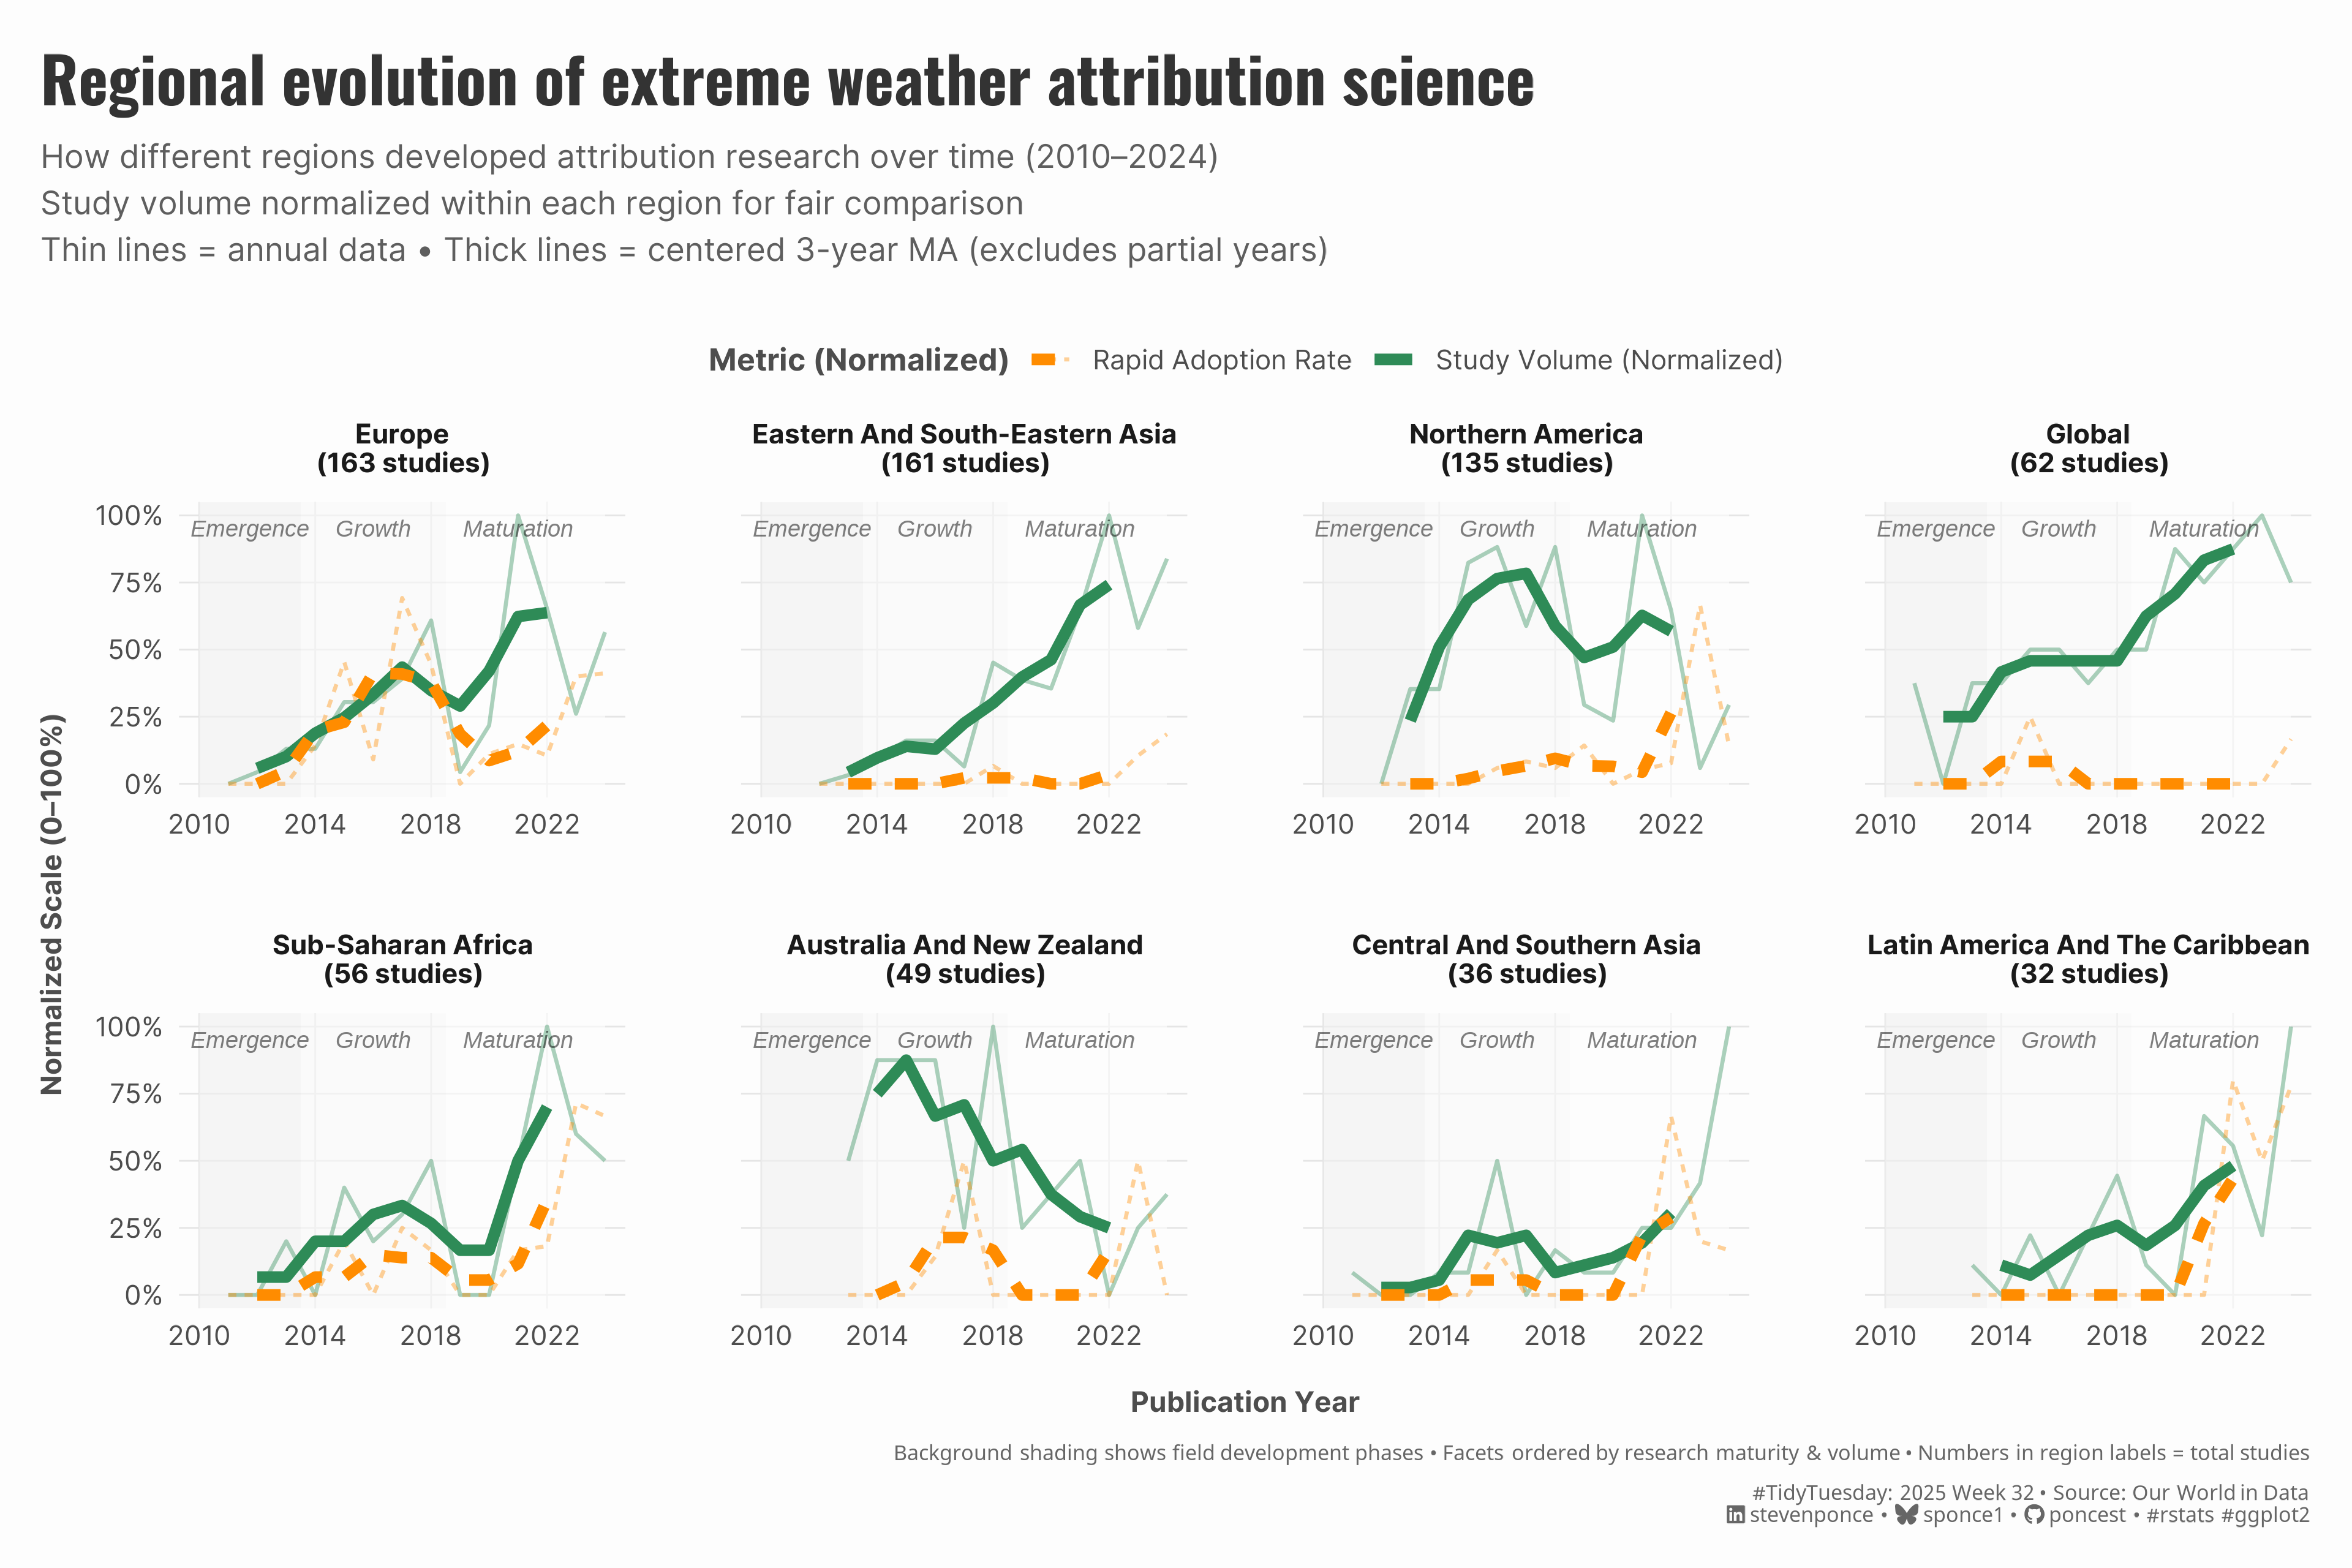{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
        tidyverse,  # Easily Install and Load the 'Tidyverse'
    tidyverse,   # Easily Install and Load the 'Tidyverse'
    ggtext,      # Improved Text Rendering Support for 'ggplot2'
    showtext,    # Using Fonts More Easily in R Graphs
    janitor,     # Simple Tools for Examining and Cleaning Dirty Data
    scales,      # Scale Functions for Visualization
    glue,        # Interpreted String Literals
    zoo          # S3 Infrastructure for Regular and Irregular Time Series
  )})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
  width  = 12,
  height = 8,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

tt <- tidytuesdayR::tt_load(2025, week = 32)

attribution_studies <- tt$attribution_studies |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(attribution_studies)
```
#### 4. Tidy Data
```{r}
#| label: tidy
#| warning: false

attribution_clean <- attribution_studies |>
  clean_names() |>
  mutate(publication_year = as.integer(publication_year)) |>
  mutate(
    cb_region = str_to_title(cb_region),
    cb_region = case_when(
      cb_region == "Usa" ~ "USA",
      cb_region == "Northern Hemisphere" ~ "Northern Hemisphere",
      TRUE ~ cb_region
    ),
    rapid_study = factor(rapid_study, levels = c("Yes", "No"))
  )

# how many ending years to treat as potentially partial
PARTIAL_YEARS <- 1

regional_evolution_data <- attribution_clean |>
  filter(!is.na(publication_year), !is.na(cb_region), publication_year >= 2010) |>
  group_by(cb_region) |>
  mutate(region_total_studies = n()) |>
  ungroup() |>
  filter(region_total_studies >= 30) |>
  # Annual counts by region/year/rapid
  count(cb_region, publication_year, rapid_study, name = "studies") |>
  # Complete years ONLY within each region up to its own last observed year
  group_by(cb_region, rapid_study) |>
  complete(
    publication_year = seq(min(publication_year, na.rm = TRUE),
      max(publication_year, na.rm = TRUE),
      by = 1
    ),
    fill = list(studies = 0)
  ) |>
  ungroup() |>
  # yearly totals & rapid adoption
  group_by(cb_region, publication_year) |>
  summarise(
    total_studies = sum(studies),
    rapid_studies = sum(studies[rapid_study == "Yes"], na.rm = TRUE),
    .groups = "drop"
  ) |>
  mutate(rapid_adoption_rate = rapid_studies / pmax(total_studies, 1)) |>
  # Normalize + Smoothing (centered, but exclude partial-year leakage)
  group_by(cb_region) |>
  mutate(
    total_normalized = if (max(total_studies) > min(total_studies)) {
      (total_studies - min(total_studies)) / (max(total_studies) - min(total_studies))
    } else {
      0.5
    },
    # region-wise bounds
    min_y = min(publication_year),
    max_y = max(publication_year),
    # last year to be treated as "complete" for smoothing windows
    last_complete_y = max_y - PARTIAL_YEARS
  ) |>
  arrange(cb_region, publication_year) |>
  # compute centered rollmean across full series
  mutate(
    total_smooth_tmp = zoo::rollmean(total_normalized, k = 3, fill = NA, align = "center"),
    rapid_smooth_tmp = zoo::rollmean(rapid_adoption_rate, k = 3, fill = NA, align = "center")
  ) |>
  # Mask smoothed values whose 3-yr window would include partial years
  mutate(
    valid_center = publication_year >= (min_y + 1) & publication_year <= (last_complete_y - 1),
    total_smooth = ifelse(valid_center, total_smooth_tmp, NA_real_),
    rapid_smooth = ifelse(valid_center, rapid_smooth_tmp, NA_real_)
  ) |>
  # context metrics & labels
  mutate(
    total_regional_studies = sum(total_studies),
    avg_rapid_adoption = mean(rapid_adoption_rate, na.rm = TRUE),
    research_start_year = min(publication_year[total_studies > 0]),
    development_pattern = case_when(
      avg_rapid_adoption > 0.30 ~ "Early Adopter",
      avg_rapid_adoption > 0.15 ~ "Moderate Adopter",
      TRUE ~ "Traditional"
    )
  ) |>
  ungroup() |>
  # field development phases (for backdrop)
  mutate(
    development_phase = case_when(
      publication_year <= 2013 ~ "Emergence",
      publication_year <= 2018 ~ "Growth",
      TRUE ~ "Maturation"
    ),
    phase_color = case_when(
      development_phase == "Emergence" ~ "#f0f0f0",
      development_phase == "Growth" ~ "#f5f5f5",
      TRUE ~ "#fafafa"
    ),
    facet_order_metric = total_regional_studies * (2024 - research_start_year),
    region_label = paste0(cb_region, "\n(", total_regional_studies, " studies)")
  ) |>
  arrange(development_pattern, desc(total_regional_studies)) |>
  ungroup()
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
colors <- get_theme_colors(
    palette = c(
      "Study Volume" = "#2E8B57",
      "Rapid Adoption" = "#FF8C00"
    )
)

### |- titles and caption ----
title_text <- str_glue("Regional evolution of extreme weather attribution science")

subtitle_text <- str_glue(
    "How different regions developed attribution research over time (2010–2024)\n",
    "Study volume normalized within each region for fair comparison\n",
    "Thin lines = annual data • Thick lines = centered 3-year MA (excludes partial years)"
)

caption_text <- create_social_caption(
    tt_year = 2025,
    tt_week = 32,
    source_text =  "Our World in Data"
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----
# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
    base_theme,
    theme(
        # Text styling
        plot.title = element_text(face = "bold", family = fonts$title, size = rel(1.2), color  = colors$title, margin = margin(b = 10)),
        plot.subtitle = element_text(family = fonts$subtitle, lineheight = 1.2, color = colors$subtitle, size = rel(0.78), margin = margin(b = 20)),

        # Axis elements
        axis.line = element_blank(),
        axis.ticks = element_blank(),

        # Grid elements
        panel.grid.major = element_line(color = "gray90",linetype = "solid", linewidth = 0.3),
        panel.grid.minor = element_blank(),

        # Axis elements
        axis.text = element_text(color = colors$text, size = rel(0.7)),
        axis.title.x = element_text(color = colors$text, face = "bold", size = rel(0.8), margin = margin(t = 15)),
        axis.title.y = element_text(color = colors$text, face = "bold", size = rel(0.8), margin = margin(r = 10)),

        # Legend elements
        legend.position = "top",
        legend.title = element_text(family = fonts$tsubtitle, color = colors$text, size = rel(0.8), face = "bold"),
        legend.text = element_text(family = fonts$tsubtitle, color = colors$text, size = rel(0.7)),
        legend.margin = margin(t = 15),

        # Plot margin
        plot.margin = margin(t = 15, r = 15, b = 15, l = 15),
    )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |-  final plot ----
p <- ggplot(regional_evolution_data, aes(x = publication_year)) +
  # Annotate (bkg phases)
  annotate("rect",
    xmin = 2010, xmax = 2013.5, ymin = -Inf, ymax = Inf,
    fill = "#f0f0f0", alpha = 0.6
  ) +
  annotate("rect",
    xmin = 2013.5, xmax = 2018.5, ymin = -Inf, ymax = Inf,
    fill = "#f8f8f8", alpha = 0.6
  ) +
  annotate("rect",
    xmin = 2018.5, xmax = 2024, ymin = -Inf, ymax = Inf,
    fill = "#fdfdfd", alpha = 0.6
  ) +
  # Geoms
  geom_line(aes(y = total_normalized, color = "Study Volume", linetype = "Study Volume"),
    alpha = 0.4, linewidth = 0.7
  ) +
  geom_line(aes(y = rapid_adoption_rate, color = "Rapid Adoption", linetype = "Rapid Adoption"),
    alpha = 0.4, linewidth = 0.7
  ) +
  geom_line(aes(y = total_smooth, color = "Study Volume", linetype = "Study Volume"),
    linewidth = 2, na.rm = TRUE
  ) +
  geom_line(aes(y = rapid_smooth, color = "Rapid Adoption", linetype = "Rapid Adoption"),
    linewidth = 2, na.rm = TRUE
  ) +
  # Annotate (phase labels)
  annotate("text",
    x = 2011.75, y = 0.95, label = "Emergence",
    size = 3, alpha = 0.5, fontface = "italic"
  ) +
  annotate("text",
    x = 2016, y = 0.95, label = "Growth",
    size = 3, alpha = 0.5, fontface = "italic"
  ) +
  annotate("text",
    x = 2021, y = 0.95, label = "Maturation",
    size = 3, alpha = 0.5, fontface = "italic"
  ) +
  # Scales
  scale_color_manual(
    values = colors$palette,
    name = "Metric (Normalized)",
    labels = c(
      "Rapid Adoption" = "Rapid Adoption Rate",
      "Study Volume" = "Study Volume (Normalized)"
    )
  ) +
  scale_linetype_manual(
    values = c("Study Volume" = "solid", "Rapid Adoption" = "22"),
    name = "Metric (Normalized)",
    labels = c(
      "Rapid Adoption" = "Rapid Adoption Rate",
      "Study Volume" = "Study Volume (Normalized)"
    )
  ) +
  scale_y_continuous(
    labels = percent_format(),
    limits = c(0, 1), breaks = seq(0, 1, 0.25)
  ) +
  scale_x_continuous(breaks = seq(2010, 2024, 4)) +
  # Labs
  labs(
    title = title_text,
    subtitle = subtitle_text,
    x = "Publication Year",
    y = "Normalized Scale (0–100%)",
    caption = paste0(
      "Background shading shows field development phases • ",
      "Facets ordered by research maturity & volume • ",
      "Numbers in region labels = total studies<br><br>",
      caption_text
    )
  ) +
  # Facets
  facet_wrap(~ fct_reorder(region_label, facet_order_metric, .desc = TRUE),
    ncol = 4, scales = "free_x"
  ) +
  # Theme
  theme(
    plot.title = element_text(
      size = rel(1.65),
      family = fonts$title,
      face = "bold",
      color = colors$title,
      lineheight = 1.1,
      margin = margin(t = 5, b = 10)
    ),
    plot.subtitle = element_text(
      size = rel(0.85),
      family = fonts$subtitle,
      color = alpha(colors$subtitle, 0.9),
      lineheight = 1.2,
      margin = margin(t = 0, b = 10)
    ),
    plot.caption = element_markdown(
      size = rel(0.55),
      family = fonts$caption,
      color = colors$caption,
      hjust = 1,
      margin = margin(t = 10)
    ),
    strip.text = element_text(size = rel(0.70), face = "bold", margin = margin(b = 10)),
    panel.spacing.x = unit(1.5, "cm"),
    panel.spacing.y = unit(1.2, "cm"),
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot(
  plot = p,
  type = "tidytuesday",
  year = 2025,
  week = 32,
  width  = 12,
  height = 8
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_32.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_32.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 32: \[Extreme Weather Attribution Studies\](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-08-12)
:::
