---
title: "Gender Equity in British Literary Prizes: Progress with Persistent Disparities"
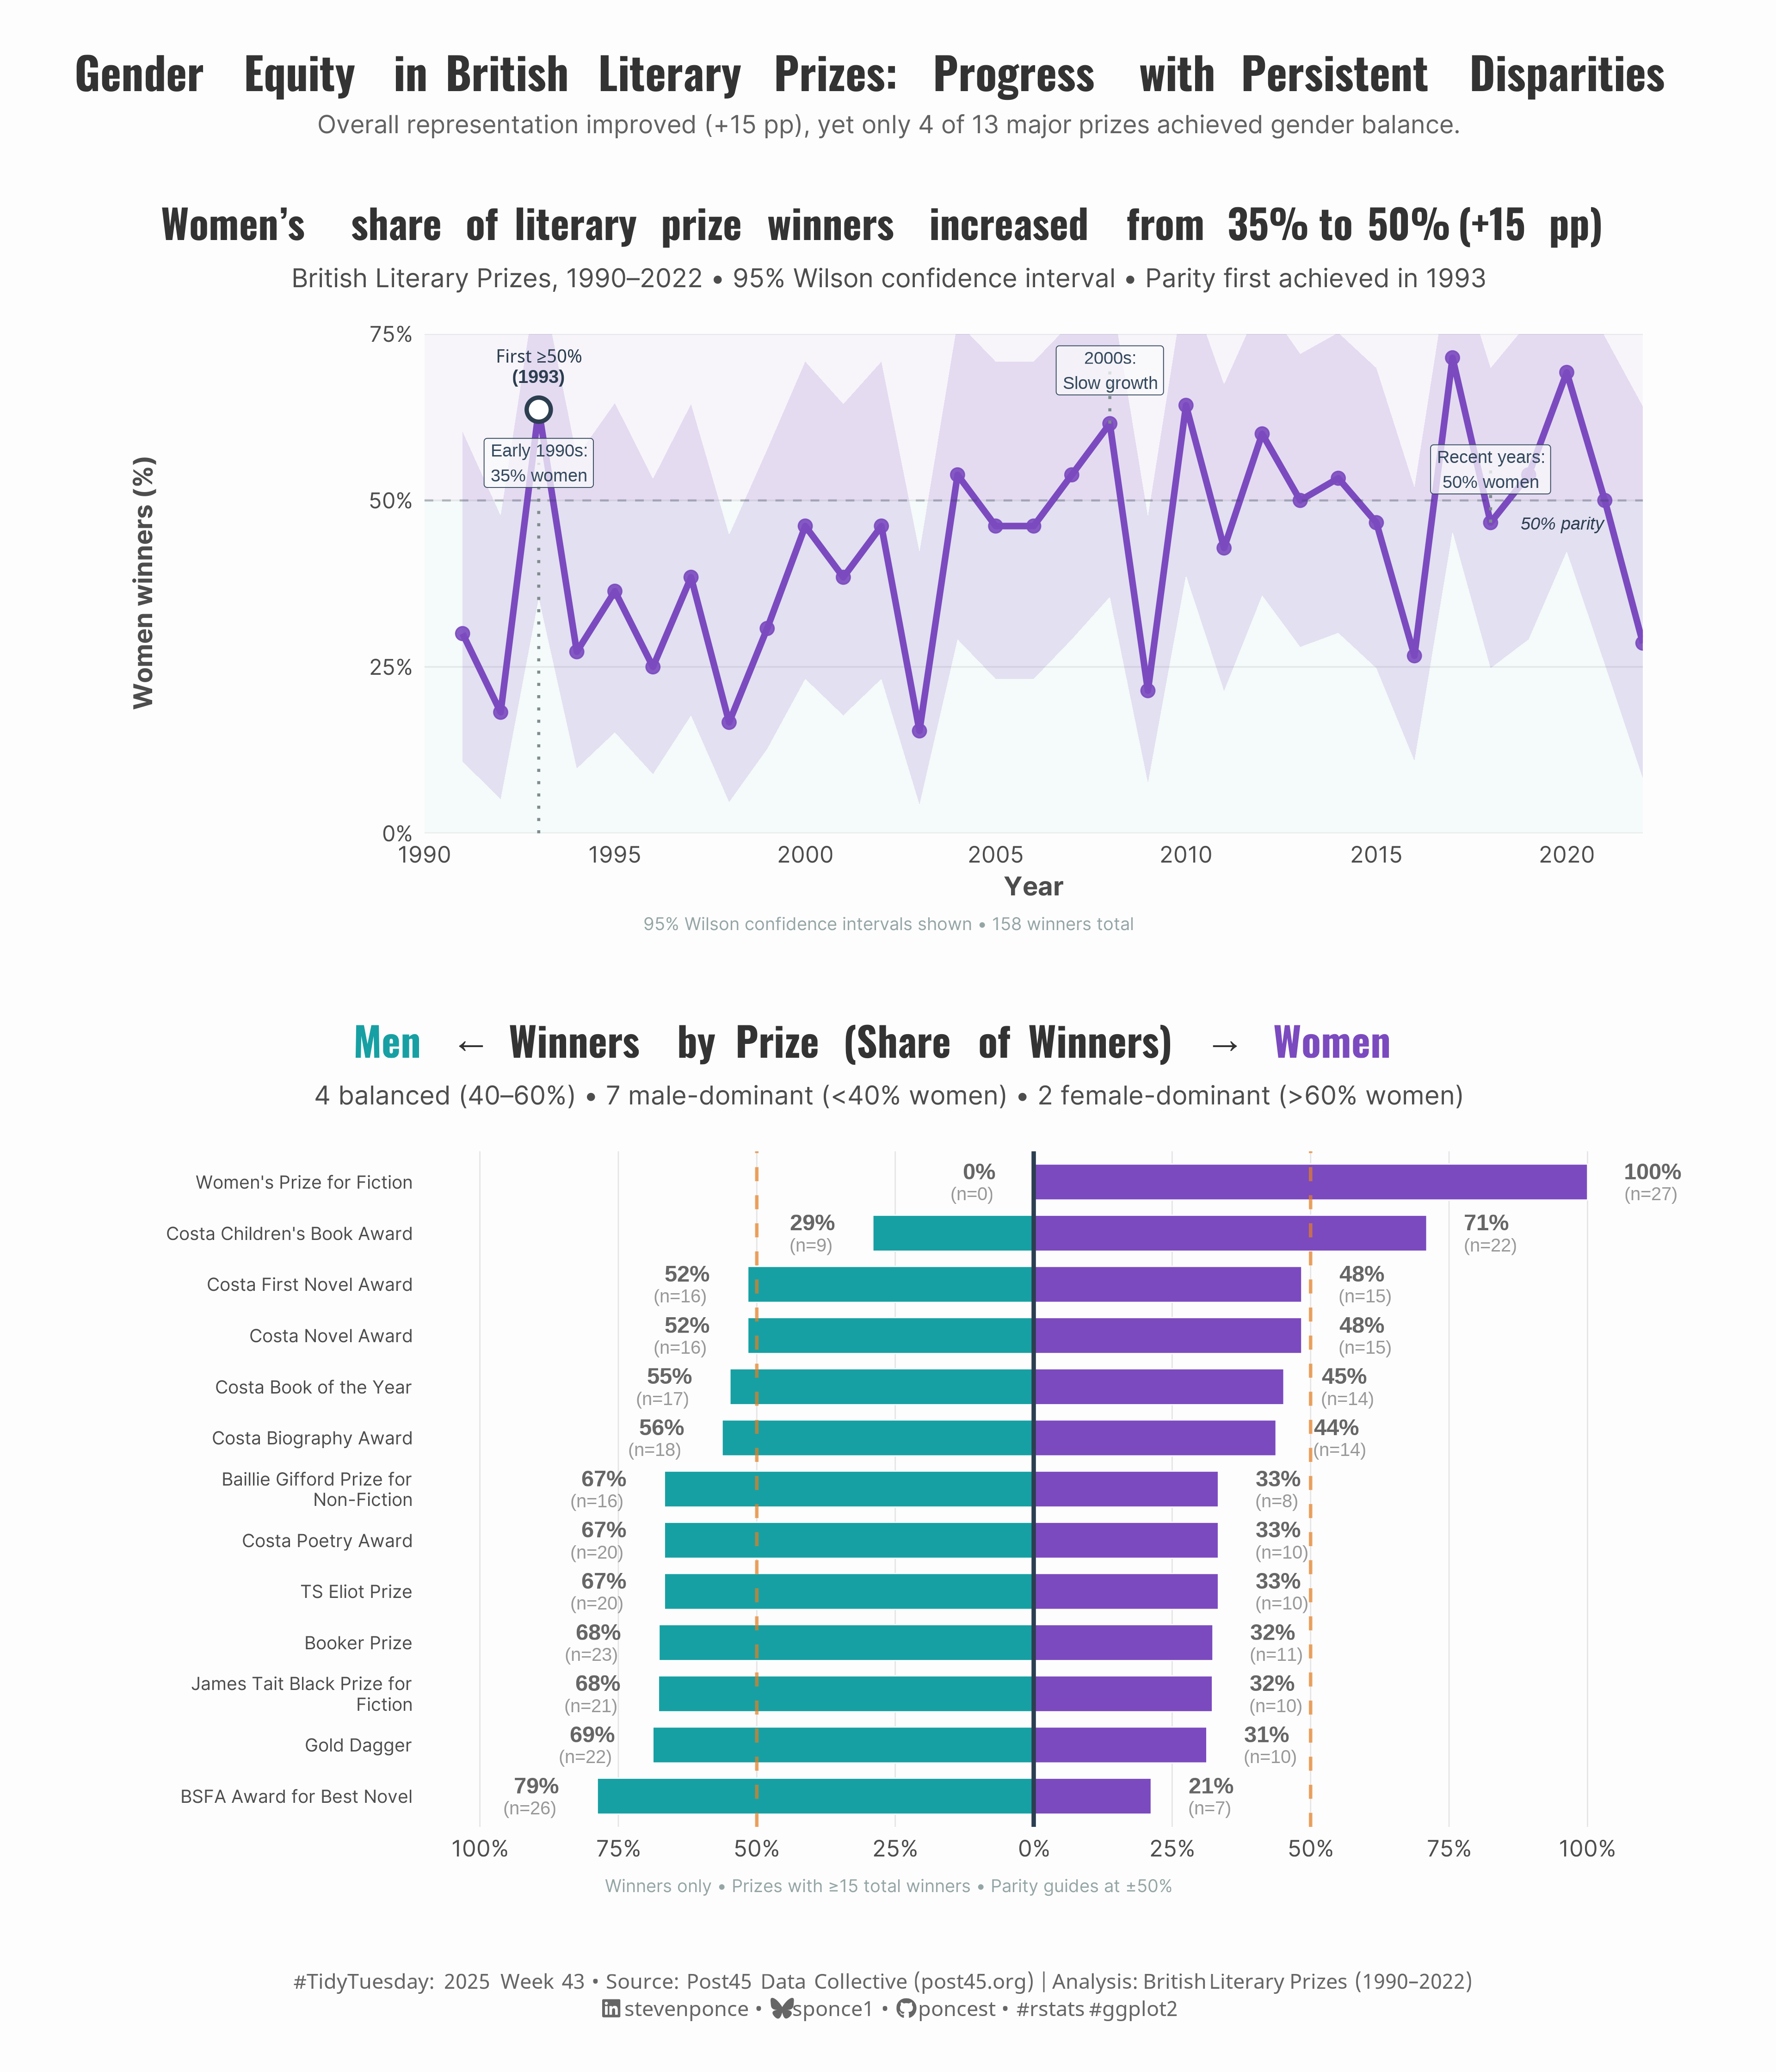
subtitle: "Overall representation improved (+15 pp), yet only 4 of 13 major prizes achieved gender balance."
description: "Analysis of 950+ prize outcomes (1990-2022) reveals women's representation among winners doubled from 35% to 50%, but progress varies dramatically by prize. Pyramid chart and timeline visualization using R, ggplot2, and patchwork."
date: "2025-10-26"
categories: ["TidyTuesday", "2025"]
tags: [
"ggplot2",
"tidyverse",
"patchwork",
"pyramid-chart",
"timeline-visualization",
"gender-equity",
"literary-prizes",
"confidence-intervals",
"Post45-Data-Collective",
"data-analysis",
"statistical-visualization",
"British-literature",
"ggtext",
"Wilson-CI"
]
image: "thumbnails/tt_2025_43.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
  tidyverse,     # Easily Install and Load the 'Tidyverse'
  ggtext,        # Improved Text Rendering Support for 'ggplot2'
  showtext,      # Using Fonts More Easily in R Graphs
  janitor,       # Simple Tools for Examining and Cleaning Dirty Data
  scales,        # Scale Functions for Visualization
  glue,          # Interpreted String Literals
  patchwork,     # The Composer of Plots
  binom          # Binomial Confidence Intervals for Several Parameterizations
)
})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
  width  = 12,
  height = 14,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

tt <- tidytuesdayR::tt_load(2025, week = 43)

prizes <- tt$prizes |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(prizes)
glimpse(prizes)
```
#### 4. Tidy Data
```{r}
#| label: tidy-fixed
#| warning: false

# data prep
prizes_clean <- prizes |>
  filter(
    !is.na(gender),
    !is.na(prize_year),
    prize_year >= 1990,
    prize_year <= 2022,
    gender %in% c("man", "woman")
  )

# P1: pyramid data ----
pyramid_data <- prizes_clean |>
  filter(person_role == "winner") |>
  count(prize_alias, gender) |>
  group_by(prize_alias) |>
  mutate(
    total = sum(n),
    pct = 100 * n / total
  ) |>
  ungroup() |>
  filter(total >= 15) |>
  select(prize_alias, gender, n, pct, total) |>
  pivot_wider(
    names_from = gender,
    values_from = c(n, pct),
    values_fill = 0
  ) |>
  mutate(
    prize_label = str_wrap(prize_alias, width = 28),
    women_pct = pct_woman,
    men_pct = pct_man,
    women_n = n_woman,
    men_n = n_man,
    men_x = -men_pct,
    women_x = women_pct,
    total = total,
    dist50 = abs(women_pct - 50)
  ) |>
  select(
    prize_label, women_pct, men_pct, women_n, men_n, men_x,
    women_x, total, dist50
  ) |>
  arrange(across(all_of("women_pct"), desc)) |>
  mutate(
    y_fac = factor(prize_label, levels = rev(prize_label))
  )

# Summary counts
balanced <- sum(abs(pyramid_data$women_pct - 50) <= 10)
total_prize <- nrow(pyramid_data)
male_dom <- sum(pyramid_data$women_pct < 40)
female_dom <- sum(pyramid_data$women_pct > 60)

# Outside labels with counts
pad <- 4.5
pad <- 5.5 # Slightly more padding for breathing room
fmt_lab <- function(pct, n) {
  paste0(
    "<span style='font-size:11pt;'><b>", round(pct), "%</b></span><br>",
    "<span style='font-size:9pt; color:gray60;'>(n=", n, ")</span>"
  )
}

men_lab <- pyramid_data |>
  mutate(
    x = men_x - pad,
    txt = fmt_lab(abs(men_x), men_n)
  )
wom_lab <- pyramid_data |>
  mutate(
    x = women_x + pad,
    txt = fmt_lab(women_x, women_n)
  )

# P2: timeline data ----
timeline <- prizes_clean |>
  filter(person_role == "winner") |>
  count(prize_year, gender) |>
  pivot_wider(names_from = gender, values_from = n, values_fill = 0) |>
  mutate(
    total = man + woman,
    p_w = woman / total
  ) |>
  mutate({
    binom::binom.wilson(x = woman, n = total)[, c("lower", "upper")]
  } |> as_tibble()) |>
  rename(ci_lo = lower, ci_hi = upper) |>
  mutate(
    pct_w = 100 * p_w,
    lo = 100 * ci_lo,
    hi = 100 * ci_hi
  )

# Headline stats
early_avg <- timeline |>
  filter(prize_year <= 1995) |>
  summarise(avg = mean(pct_w, na.rm = TRUE)) |>
  pull()

late_avg <- timeline |>
  filter(prize_year >= 2018) |>
  summarise(avg = mean(pct_w, na.rm = TRUE)) |>
  pull()

improvement <- late_avg - early_avg

parity_year <- timeline |>
  filter(pct_w >= 50) |>
  arrange(prize_year) |>
  slice(1) |>
  pull(prize_year)

# milestones
milestones <- tibble(
  year = c(1993, 2008, 2018),
  label = c(
    glue("Early 1990s:\n{round(early_avg)}% women"),
    "2000s:\nSlow growth",
    glue("Recent years:\n{round(late_avg)}% women")
  )
) |>
  left_join(timeline |> select(prize_year, pct_w), by = c("year" = "prize_year")) |>
  mutate(
    y = case_when(
      year == 1993 ~ pct_w - 8,
      year == 2008 ~ pct_w + 8,
      year == 2018 ~ pct_w + 8
    )
  )
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
# Get basic theme colors
colors <- get_theme_colors(
  palette = list(
    col_women = "#7B4ABF",
    col_men = "#17A0A3",
    col_gray1 = "#2C3E50",
    col_gray2 = "#7F8C8D",
    col_grid = "#ECF0F1"
  )
)

### |- titles and caption ----
title_text <- str_glue(
  "Gender Equity in British Literary Prizes: Progress with Persistent Disparities"
)

subtitle_text <- str_glue(
    "Overall representation improved (+{round(improvement)} pp), ",
    "yet only {balanced} of {total_prize} major prizes achieved gender balance."
)

caption_text <- create_social_caption(
  tt_year = 2025,
  tt_week = 43,
  note_text = NULL,
  source_text = str_glue(
      "Post45 Data Collective (post45.org) | Analysis: British Literary Prizes (1990–2022)"
  )
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----
# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # Text styling
    plot.title = element_markdown(
      face = "bold", family = fonts$title, size = rel(1.4),
      color = colors$title, margin = margin(b = 10), hjust = 0.5
    ),
    plot.subtitle = element_text(
      face = "italic", family = fonts$subtitle, lineheight = 1.2,
      color = colors$subtitle, size = rel(0.9), margin = margin(b = 20), hjust = 0.5
    ),

    ## Grid
    panel.grid.major.y = element_blank(),
    panel.grid.minor = element_blank(),
    panel.grid.major.x = element_line(color = "gray90", linewidth = 0.3),

    # Axes
    axis.title = element_text(size = rel(0.9), color = "gray30"),
    axis.text = element_text(color = "gray30"),
    axis.text.y = element_text(size = rel(0.95)),
    axis.ticks = element_blank(),

    # Facets
    strip.background = element_rect(fill = "gray95", color = NA),
    strip.text = element_text(
      face = "bold",
      color = "gray20",
      size = rel(1),
      margin = margin(t = 8, b = 8)
    ),
    panel.spacing = unit(2, "lines"),

    # Legend elements
    legend.position = "plot",
    legend.title = element_text(
      family = fonts$tsubtitle,
      color = colors$text, size = rel(0.8), face = "bold"
    ),
    legend.text = element_text(
      family = fonts$tsubtitle,
      color = colors$text, size = rel(0.7)
    ),
    legend.margin = margin(t = 15),

    # Plot margin
    plot.margin = margin(20, 20, 20, 20)
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |- P1: pyramid plot ----
p1 <-
  ggplot(pyramid_data, aes(y = y_fac)) +

  # Geom
  geom_col(aes(x = men_x),
    fill = colors$palette$col_men,
    width = 0.7, color = "white", linewidth = 0.25
  ) +
  geom_col(aes(x = women_x),
    fill = colors$palette$col_women,
    width = 0.7, color = "white", linewidth = 0.25
  ) +
  geom_vline(
    xintercept = 0, color = colors$palette$col_gray1,
    linewidth = 1
  ) +
  geom_vline(
    xintercept = c(-50, 50), color = "#E67E22",
    linewidth = 0.8, linetype = "dashed", alpha = 0.7
  ) +
  geom_richtext(
    data = men_lab,
    aes(y = y_fac, x = x, label = txt),
    hjust = 1, color = "gray40", size = 3,
    fill = NA, label.color = NA,
    inherit.aes = FALSE
  ) +
  geom_richtext(
    data = wom_lab,
    aes(y = y_fac, x = x, label = txt),
    hjust = 0, color = "gray40", size = 3,
    fill = NA, label.color = NA,
    inherit.aes = FALSE
  ) +
  # Scales
  coord_cartesian(xlim = c(-110, 110), clip = "off") +
  scale_x_continuous(
    breaks = seq(-100, 100, 25),
    labels = \(x) paste0(abs(x), "%"),
    expand = c(0, 0)
  ) +
  # Labs
  labs(
    title = glue(
      "<span style='color:{colors$palette$col_men}; font-family:{get_font_families()$title};'>**Men**</span> ",
      "<span style='font-family:sans;'>←</span> ",
      "Winners by Prize (Share of Winners) ",
      "<span style='font-family:sans;'>→</span> ",
      "<span style='color:{colors$palette$col_women}; font-family:{get_font_families()$title};'>**Women**</span>"
    ),
    subtitle = glue(
      "{balanced} balanced (40–60%) • ",
      "{male_dom} male-dominant (<40% women) • ",
      "{female_dom} female-dominant (>60% women)"
    ),
    x = NULL,
    y = NULL,
    caption = "Winners only • Prizes with ≥15 total winners • Parity guides at ±50%"
  ) +
  # Theme
  theme(
    plot.caption = element_text(
      color = "#95A5A6", size = 8.5,
      margin = margin(t = 8, b = 5),
      hjust = 0.5
    ),
    panel.grid.major.y = element_blank(),
    axis.text.y = element_text(size = 8.8, lineheight = 0.95),
    plot.margin = margin(20, 45, 20, 45)
  )

### |- P2: timeline plot ----
p2 <-
ggplot(timeline, aes(prize_year, pct_w)) +
  # Annotations
  annotate("rect",
    xmin = 1990, xmax = 2022, ymin = 0, ymax = 50,
    fill = colors$palette$col_men, alpha = 0.03
  ) +
  annotate("rect",
    xmin = 1990, xmax = 2022, ymin = 50, ymax = 75,
    fill = colors$palette$col_women, alpha = 0.04
  ) +
  # Geoms
  geom_ribbon(aes(ymin = lo, ymax = hi),
    fill = colors$palette$col_women, alpha = 0.15
  ) +
  geom_line(color = colors$palette$col_women, linewidth = 1.5) +
  geom_point(color = colors$palette$col_women, size = 2.8, alpha = 0.9) +
  geom_hline(
    yintercept = 50,
    linetype = "dashed",
    color = alpha(colors$palette$col_gray1, 0.3),
    linewidth = 0.5
  ) +
  geom_point(
    data = timeline |> filter(prize_year == parity_year),
    aes(prize_year, pct_w),
    color = "#2C3E50", size = 4.5, shape = 21,
    fill = "white", stroke = 1.5
  ) +
  geom_segment(
    data = milestones,
    aes(
      x = year, xend = year,
      y = ifelse(y > pct_w, pct_w, 0),
      yend = y
    ),
    color = colors$palette$col_gray2,
    linetype = "dotted", linewidth = 0.7
  ) +
  geom_label(
    data = milestones,
    aes(x = year, y = y, label = label),
    size = 3, fontface = "plain",
    fill = alpha("#F9FAFB", 0.75),
    color = "#34495E",
    label.padding = unit(0.28, "lines"),
    label.size = 0.2,
    label.r = unit(0.15, "lines")
  ) +
  annotate(
    "text",
    x = parity_year,
    y = (timeline |>
        filter(prize_year == parity_year) |>
        pull(pct_w) + 6.5),
    label = glue("First ≥50%\n({parity_year})"),
    color = "#2C3E50", size = 3.2, fontface = "bold",
    lineheight = 0.9
  ) +
  annotate("text",
    x = 2021, y = 46.5,
    label = "50% parity",
    color = colors$palette$col_gray1,
    size = 3, fontface = "italic", hjust = 1
  ) +
  # Scales
  scale_y_continuous(
    labels = label_percent(scale = 1),
    breaks = seq(0, 75, 25)
  ) +
  scale_x_continuous(breaks = seq(1990, 2020, 5)) +
  coord_cartesian(ylim = c(0, 75), expand = FALSE) +
  # Labs
  labs(
    title = glue(
      "Women's share of literary prize winners increased from ",
      "{round(early_avg)}% to {round(late_avg)}% (+{round(improvement)} pp)"
    ),
    subtitle = glue(
      "British Literary Prizes, 1990–2022 • ",
      "95% Wilson confidence interval • ",
      "Parity first achieved in {parity_year}"
    ),
    x = "Year",
    y = "Women winners (%)",
    caption = "95% Wilson confidence intervals shown • 158 winners total"
  ) +
  # Theme
  theme(
    plot.caption = element_text(
      color = "#95A5A6", size = 8.5,
      margin = margin(t = 8, b = 5),
      hjust = 0.5
    ),
    panel.grid.major.x = element_blank(),
    panel.grid.major.y = element_line(
      color = "gray92", linewidth = 0.4
    )
  )

### |- Combined plot ----
combined_plots <- p2 / p1 +
    plot_layout(heights = c(0.85, 1.15))

combined_plots <- combined_plots +
    plot_annotation(
        title = title_text,
        subtitle = subtitle_text,
        caption = caption_text,
        theme = theme(
            plot.title = element_markdown(
                size = rel(1.55),
                family = fonts$title,
                face = "bold",
                color = colors$title,
                lineheight = 1.15,
                margin = margin(t = 8, b = 5)
            ),
            plot.subtitle = element_text(
                size = rel(0.87),
                family = fonts$subtitle,
                color = alpha(colors$subtitle, 0.88),
                lineheight = 1.2,
                margin = margin(t = 2, b = 15)
            ),
            plot.caption = element_markdown(
                size = rel(0.73),
                family = fonts$caption,
                color = colors$caption,
                hjust = 0.5,
                lineheight = 1.3,
                margin = margin(t = 12, b = 5),
            )
        )
    )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

save_plot_patchwork(
  plot = combined_plots,
  type = "tidytuesday",
  year = 2025,
  week = 43,
  width  = 12,
  height = 14,
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_43.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_43.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. Data Sources:
- TidyTuesday 2025 Week 43: \[Selected British Literary Prizes (1990-2022)\](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-10-28
:::
#### 11. Custom Functions Documentation
::: {.callout-note collapse="true"}
##### 📦 Custom Helper Functions
This analysis uses custom functions from my personal module library for efficiency and consistency across projects.
**Functions Used:**
- **`fonts.R`**: `setup_fonts()`, `get_font_families()` - Font management with showtext
- **`social_icons.R`**: `create_social_caption()` - Generates formatted social media captions
- **`image_utils.R`**: `save_plot()` - Consistent plot saving with naming conventions
- **`base_theme.R`**: `create_base_theme()`, `extend_weekly_theme()`, `get_theme_colors()` - Custom ggplot2 themes
**Why custom functions?**\
These utilities standardize theming, fonts, and output across all my data visualizations. The core analysis (data tidying and visualization logic) uses only standard tidyverse packages.
**Source Code:**\
View all custom functions → [GitHub: R/utils](https://github.com/poncest/personal-website/tree/master/R)
:::
