---
title: "Flint Lead Contamination: Government vs. Citizen Testing (2015)"
subtitle: "Comparison of water samples collected by MDEQ (n = 71) and Virginia Tech (n = 271)"
description: "Comparing lead levels in Flint water samples: government vs. citizen science testing revealed different contamination patterns and the impact of sample exclusion on public health reporting."
date: "2025-11-01"
categories: ["TidyTuesday", "2025"]
tags: [
"flint-water-crisis",
"public-health",
"environmental-data",
"citizen-science",
"data-ethics",
"ggplot2",
"patchwork",
"stacked-bar-chart",
"cumulative-distribution",
"epa-standards",
"lead-contamination",
"government-data",
"data-transparency",
"sequential-color-palette",
"water-quality"
]
image: "thumbnails/tt_2025_44.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
---
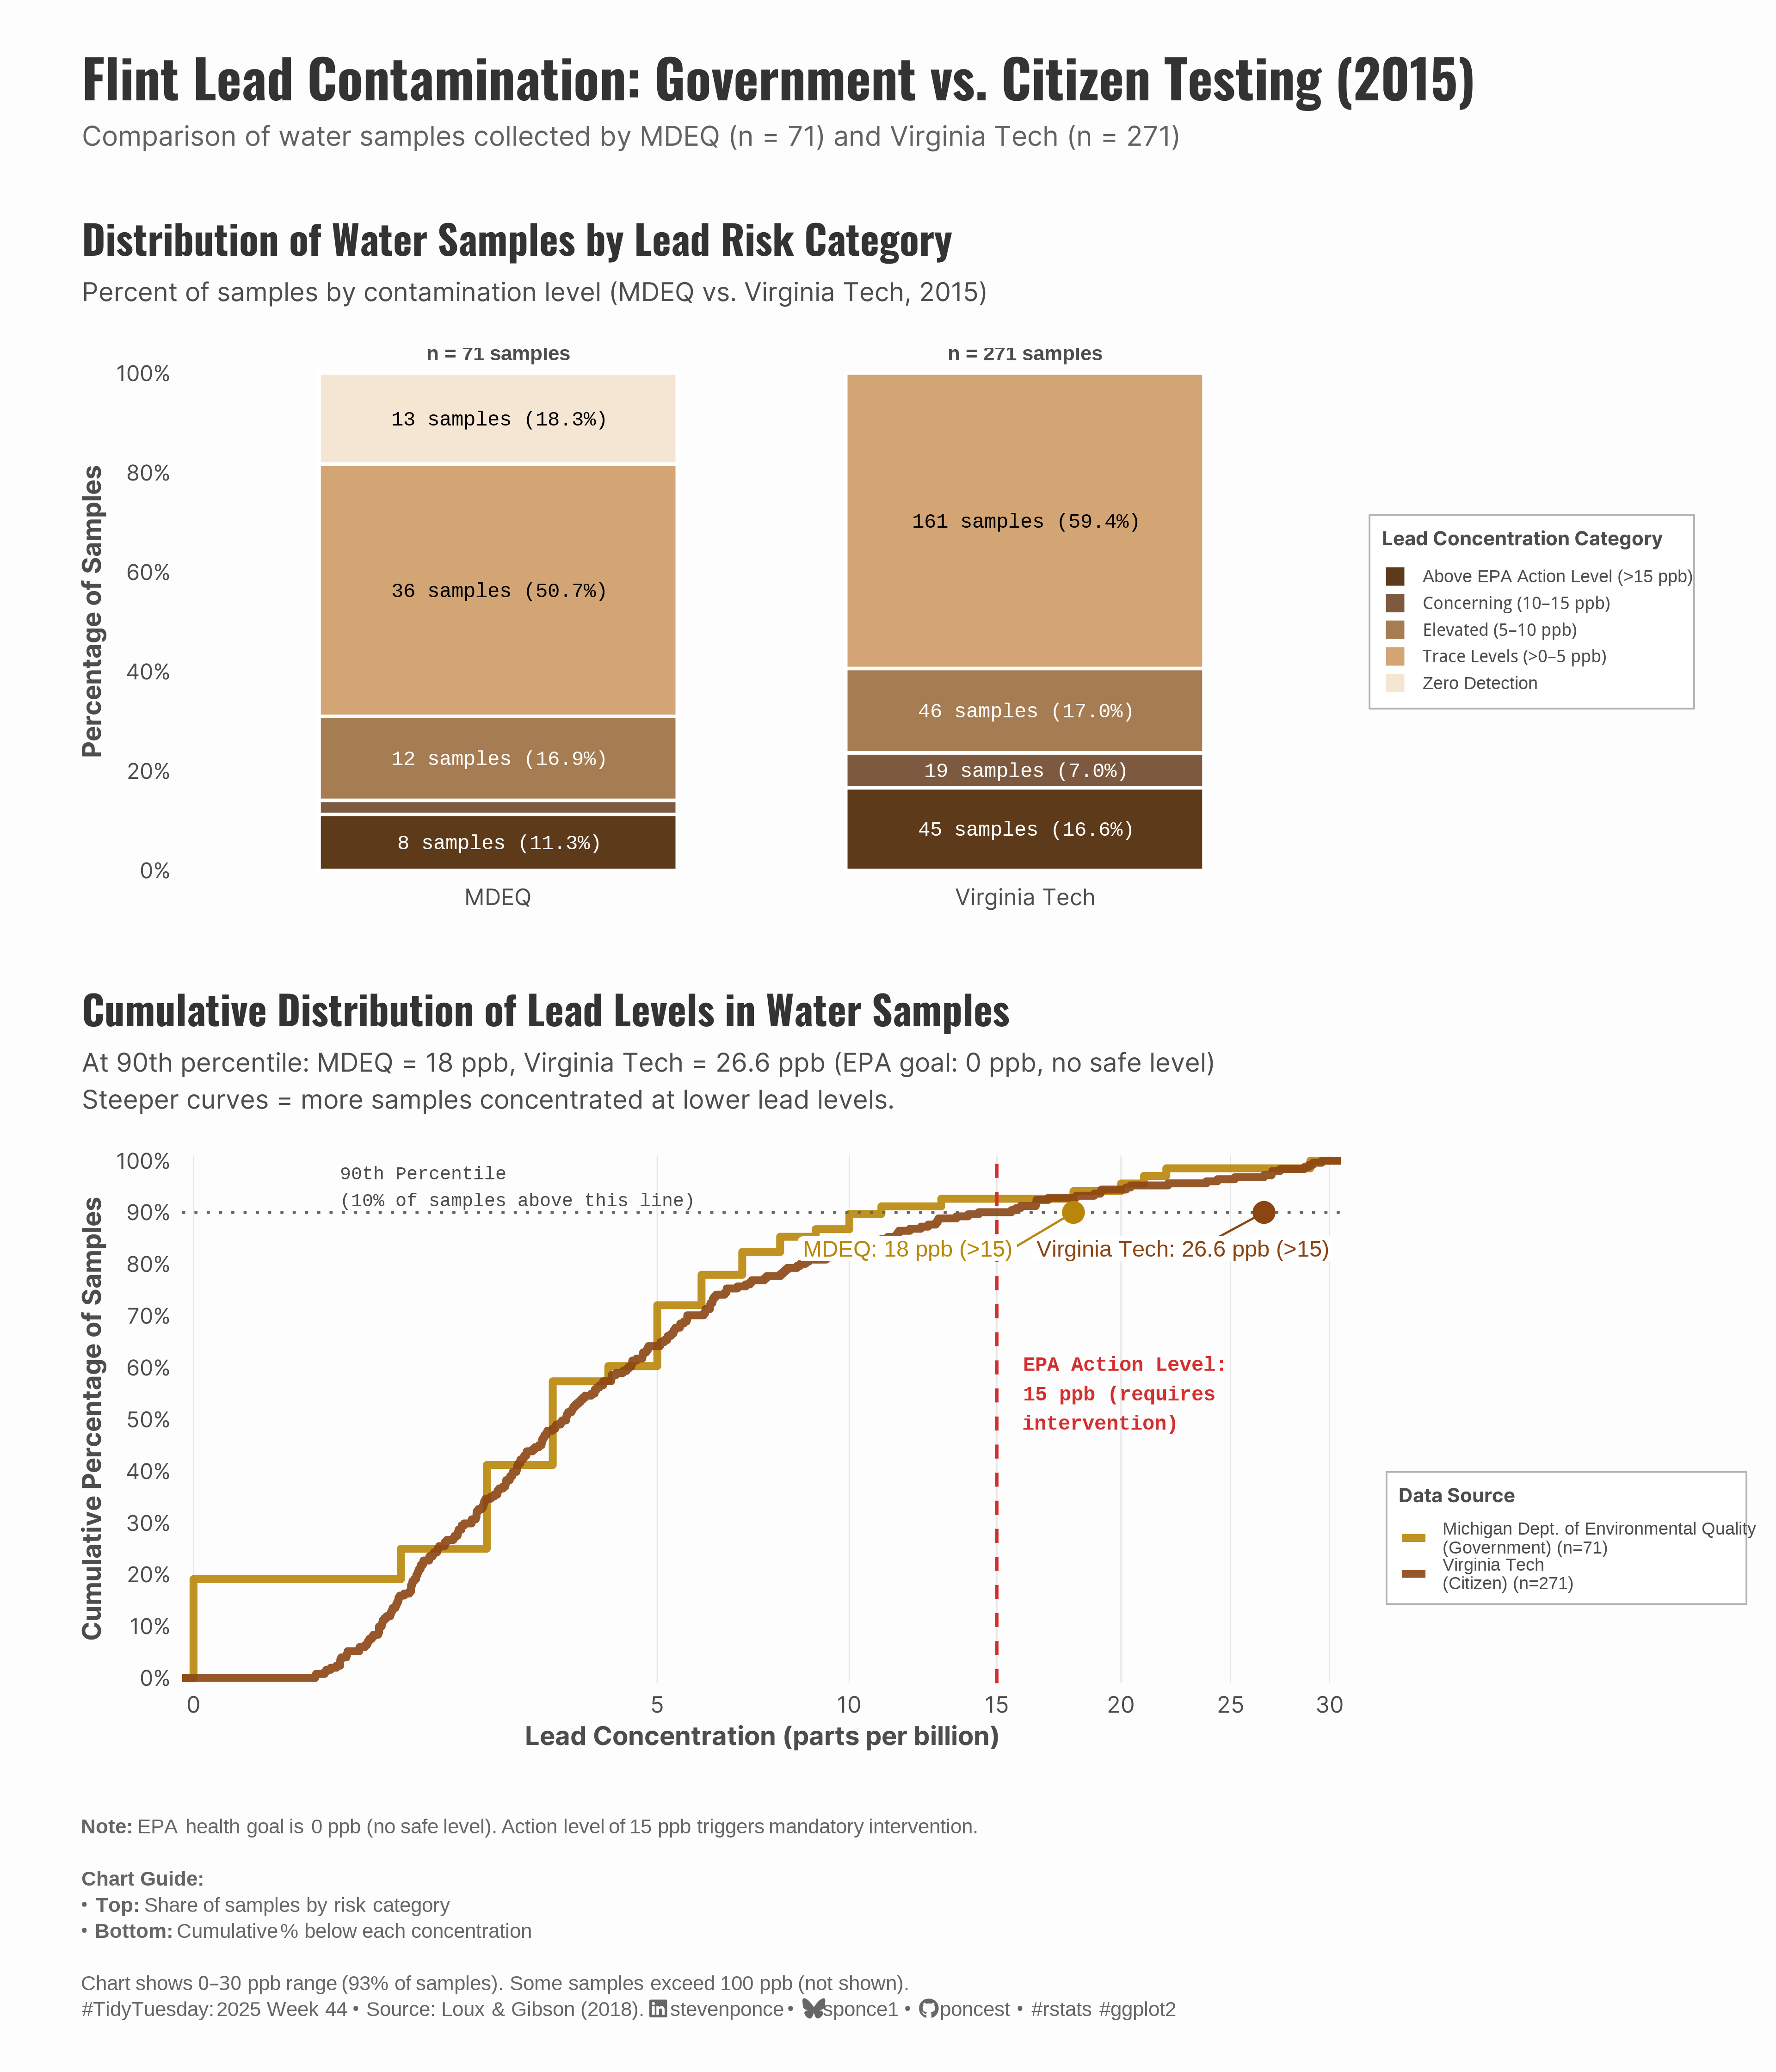{#fig-1}
### <mark> **Steps to Create this Graphic** </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
#| warning: false
#| message: false
#| results: "hide"

## 1. LOAD PACKAGES & SETUP ----
suppressPackageStartupMessages({
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
  tidyverse,  # Easily Install and Load the 'Tidyverse'
  ggtext,     # Improved Text Rendering Support for 'ggplot2'
  showtext,   # Using Fonts More Easily in R Graphs
  janitor,    # Simple Tools for Examining and Cleaning Dirty Data
  scales,     # Scale Functions for Visualization
  glue,       # Interpreted String Literals
  ggrepel,    # Automatically Position Non-Overlapping Text Labels with 'ggplot2'
  patchwork   # The Composer of Plots
)
})

### |- figure size ----
camcorder::gg_record(
  dir    = here::here("temp_plots"),
  device = "png",
  width  = 12,
  height = 14,
  units  = "in",
  dpi    = 320
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
#| include: true
#| eval: true
#| warning: false

tt <- tidytuesdayR::tt_load(2025, week = 44)

flint_mdeq <- tt$flint_mdeq |> clean_names()
flint_vt <- tt$flint_vt |> clean_names()

tidytuesdayR::readme(tt)
rm(tt)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false

glimpse(flint_mdeq)
glimpse(flint_vt)
```
#### 4. Tidy Data
```{r}
#| label: tidy-fixed
#| warning: false

mdeq_tidy <- flint_mdeq |>
  mutate(
    excluded = is.na(lead2),
    source = "MDEQ"
  ) |>
  select(sample, lead, excluded, notes, source)

vt_tidy <- flint_vt |>
  reframe(
    sample, lead,
    excluded = FALSE,
    notes = NA_character_,
    source = "Virginia Tech"
  )

combined_data <- bind_rows(mdeq_tidy, vt_tidy) |>
  mutate(
    source = factor(source, levels = c("MDEQ", "Virginia Tech")),
    status = if_else(excluded, "Excluded by MDEQ", "Included")
  )

source_labels <- c(
  "MDEQ" = "Michigan Dept. of Environmental Quality\n(Government)",
  "Virginia Tech" = "Virginia Tech\n(Citizen)"
)

stats_tbl <- combined_data |>
  group_by(source) |>
  summarise(
    p90 = quantile(lead, 0.90, na.rm = TRUE),
    median = median(lead, na.rm = TRUE),
    mean = mean(lead, na.rm = TRUE),
    n = n(),
    .groups = "drop"
  )

risk_lvls <- c(
  "Zero Detection",
  "Trace Levels (>0–5 ppb)",
  "Elevated (5–10 ppb)",
  "Concerning (10–15 ppb)",
  "Above EPA Action Level (>15 ppb)"
)

risk_data <- combined_data |>
  mutate(
    risk_category = case_when(
      lead == 0 ~ risk_lvls[1],
      lead > 0 & lead <= 5 ~ risk_lvls[2],
      lead > 5 & lead <= 10 ~ risk_lvls[3],
      lead > 10 & lead <= 15 ~ risk_lvls[4],
      lead > 15 ~ risk_lvls[5],
      TRUE ~ NA_character_
    ) |> factor(levels = risk_lvls)
  ) |>
  count(source, risk_category, name = "count") |>
  group_by(source) |>
  mutate(
    percentage = 100 * count / sum(count),
    total = sum(count)
  ) |>
  ungroup() |>
  mutate(text_color = if_else(risk_category %in% risk_lvls[1:2], "black", "white"))

summary_pct <- risk_data |>
  summarise(
    above_15 = sum(percentage[risk_category == "Above EPA Action Level (>15 ppb)"]),
    above_10 = sum(percentage[risk_category %in% c(
      "Concerning (10–15 ppb)",
      "Above EPA Action Level (>15 ppb)"
    )]),
    .by = source
  ) |>
  arrange(source)
```
#### 5. Visualization Parameters
```{r}
#| label: params
#| include: true
#| warning: false

### |-  plot aesthetics ----
# Get basic theme colors
colors <- get_theme_colors(
  palette = c(
    "Zero Detection" = "#F5E6D3",
    "Trace Levels (>0–5 ppb)" = "#D4A574",
    "Elevated (5–10 ppb)" = "#A67C52",
    "Concerning (10–15 ppb)" = "#7D5A3F",
    "Above EPA Action Level (>15 ppb)" = "#5D3A1A",
    "MDEQ" = "#B8860B",
    "Virginia Tech" = "#8B4513"
  )
)

### |- titles and caption ----
title_text <- str_glue(
  "Flint Lead Contamination: Government vs. Citizen Testing (2015)"
)

subtitle_text <- str_glue(
  "Comparison of water samples collected by MDEQ (n = 71) and Virginia Tech (n = 271)"
)

pct_leq_30 <- combined_data |>
  summarise(p = mean(lead <= 30, na.rm = TRUE) * 100) |>
  pull(p) |>
  round(0)

caption_text <- create_social_caption_02(
    tt_year = 2025,
    tt_week = 44,
    note_text = glue::glue(
        "**Note:** EPA health goal is 0 ppb (no safe level). ",
        "Action level of 15 ppb triggers mandatory intervention.<br><br>",
        "**Chart Guide:**<br>",
        "• **Top:** Share of samples by risk category<br>",
        "• **Bottom:** Cumulative % below each concentration<br><br>",
        "Chart shows 0–30 ppb range ({pct_leq_30}% of samples). ",
        "Some samples exceed 100 ppb (not shown)."
    ),
    source_text = "Loux & Gibson (2018)."
)

### |-  fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----
# Start with base theme
base_theme <- create_base_theme(colors)

# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
  base_theme,
  theme(
    # Text styling
    plot.title = element_text(
      face = "bold", family = fonts$title, size = rel(1.4),
      color = colors$title, margin = margin(b = 10), hjust = 0
    ),
    plot.subtitle = element_text(
      face = "italic", family = fonts$subtitle, lineheight = 1.2,
      color = colors$subtitle, size = rel(0.9), margin = margin(b = 20), hjust = 0
    ),

    ## Grid
    panel.grid.major.y = element_blank(),
    panel.grid.minor = element_blank(),
    panel.grid.major.x = element_line(color = "gray90", linewidth = 0.3),

    # Axes
    axis.title = element_text(size = rel(0.9), color = "gray30"),
    axis.text = element_text(color = "gray30"),
    axis.text.y = element_text(size = rel(0.95)),
    axis.ticks = element_blank(),

    # Facets
    strip.background = element_rect(fill = "gray95", color = NA),
    strip.text = element_text(
      face = "bold",
      color = "gray20",
      size = rel(1),
      margin = margin(t = 8, b = 8)
    ),
    panel.spacing = unit(2, "lines"),

    # Legend elements
    legend.position = "plot",
    legend.title = element_text(
      family = fonts$tsubtitle,
      color = colors$text, size = rel(0.8), face = "bold"
    ),
    legend.text = element_text(
      family = fonts$tsubtitle,
      color = colors$text, size = rel(0.7)
    ),
    legend.margin = margin(t = 15),

    # Plot margin
    plot.margin = margin(20, 20, 20, 20)
  )
)

# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
#| warning: false

### |- P1: risk categories plot ----
risk_subtitle <- glue(
  "Percent of samples by contamination level (MDEQ vs. Virginia Tech, 2015)"
)

n_mdeq <- stats_tbl$n[stats_tbl$source == "MDEQ"]
n_vt <- stats_tbl$n[stats_tbl$source == "Virginia Tech"]

p1 <-
  ggplot(risk_data, aes(source, percentage, fill = risk_category)) +
  geom_bar(stat = "identity", color = "white", linewidth = 0.8, width = 0.68) +
  # Geoms
  geom_text(
    aes(
      label = ifelse(
        percentage >= 3,
        sprintf("%d samples (%.1f%%)", count, percentage),
        ""
      ),
      color = text_color,
    ),
    position = position_stack(vjust = 0.5), family = "mono",
    size = 3.5, lineheight = 0.9,
    show.legend = FALSE
  ) +
  # Scales
  scale_color_identity(guide = "none") +
  scale_fill_manual(
    values = colors$palette,
    breaks = rev(risk_lvls),
    labels = rev(risk_lvls),
    name = "Lead Concentration Category"
  ) +
  scale_y_continuous(
    labels = label_percent(scale = 1), breaks = seq(0, 100, 20), expand = c(0.01, 0)
  ) +
  # Annotate
  annotate("text",
    x = 1, y = 104, label = glue("n = {n_mdeq} samples"),
    fontface = "bold", size = 3.5, color = "gray30"
  ) +
  annotate("text",
    x = 2, y = 104, label = glue("n = {n_vt} samples"),
    fontface = "bold", size = 3.5, color = "gray30"
  ) +
  # Labs
  labs(
    title = "Distribution of Water Samples by Lead Risk Category",
    subtitle = risk_subtitle, x = NULL, y = "Percentage of Samples"
  ) +
  # Theme
  theme(
    legend.position = "right",
    legend.background = element_rect(fill = "white", color = "gray70", linewidth = 0.4),
    legend.title = element_text(face = "bold", size = 9.5),
    legend.text = element_text(size = 8.5, family = "Arial"),
    legend.key.size = unit(0.9, "lines"),
    legend.margin = margin(6, 6, 6, 6),
    panel.grid.major.x = element_blank(),
    axis.text.x = element_text(lineheight = 0.95)
  )

### |- P2: Cumulative plot ----
ecdf_subtitle <- glue(
  "At 90th percentile: MDEQ = 18 ppb, Virginia Tech = 26.6 ppb (EPA goal: 0 ppb, no safe level)\n",
  "Steeper curves = more samples concentrated at lower lead levels."
)

annot_pts <- stats_tbl |>
  reframe(
    role = if_else(source == "MDEQ", "Government", "Citizen"),
    x = p90,
    y = 0.90,
    lab = glue("{source}: {round(p90,1)} ppb (>15)"),
    .by = source
  )

p2 <-
  ggplot(combined_data, aes(lead, color = source)) +
    # Geoms
    stat_ecdf(linewidth = 1.8, alpha = 0.9) +
    geom_vline(xintercept = 15, linetype = "dashed", color = "#D32F2F", linewidth = 0.8) +
    geom_hline(yintercept = 0.9, linetype = "dotted", color = "gray40", linewidth = 0.7) +
    geom_point(
      data = annot_pts,
      aes(x, y, fill = source, color = source),
      shape = 21, size = 3.5, stroke = 1.3, show.legend = FALSE
    ) +
    geom_label_repel(
      data = annot_pts, aes(x, y, label = lab, color = source),
      nudge_y = c(-0.07, -0.07), label.padding = unit(0.15, "lines"),
      label.size = 0, show.legend = FALSE, seed = 44
    ) +
    # Annotate
    annotate("text",
      x = 16, y = 0.55,
      label = "EPA Action Level:\n15 ppb (requires\nintervention)",
      color = "#D32F2F", size = 3.5, hjust = 0, fontface = "bold", family = "mono"
    ) +
    annotate("text",
      x = 0.5, y = 0.95,
      label = "90th Percentile\n(10% of samples above this line)",
      color = "gray30", size = 3.2, hjust = 0, family = "mono"
    ) +
    # Scales
    scale_color_manual(
      values = colors$palette,
      breaks = c("MDEQ", "Virginia Tech"),
      labels = c(
        glue("{source_labels['MDEQ']} (n={n_mdeq})"),
        glue("{source_labels['Virginia Tech']} (n={n_vt})")
      ),
      name = "Data Source"
    ) +
    scale_fill_manual(values = colors$palette, guide = "none") +
    scale_x_continuous(
      trans = "sqrt", limits = c(0, 30), breaks = seq(0, 30, 5),
      expand = c(0.01, 0)
    ) +
    scale_y_continuous(
      labels = label_percent(accuracy = 1),
      breaks = seq(0, 1, 0.1), expand = c(0.01, 0)
    ) +
    # Labs
    labs(
      title = "Cumulative Distribution of Lead Levels in Water Samples",
      subtitle = ecdf_subtitle,
      x = "Lead Concentration (parts per billion)",
      y = "Cumulative Percentage of Samples"
    ) +
    guides(color = guide_legend(
      title = "Data Source",
      override.aes = list(linetype = 1, linewidth = 1.8)
    )) +
    # Theme
    theme(
      legend.position = "inside",
      legend.position.inside = c(1.35, 0.15),
      legend.justification = c("right", "bottom"),
      legend.background = element_rect(fill = "white", color = "gray70", linewidth = 0.4),
      legend.title = element_text(face = "bold", size = 9.5),
      legend.text = element_text(size = 8.5, family = "Arial"),
      legend.key.size = unit(1, "lines"),
      legend.margin = margin(6, 6, 6, 6),
    )

### |- Combined plot ----
combined_plots <- p1 / p2

combined_plots <- combined_plots +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_text(
        size = rel(1.85),
        family = fonts$title,
        face = "bold",
        color = colors$title,
        lineheight = 1.15,
        margin = margin(t = 8, b = 5)
      ),
      plot.subtitle = element_text(
        size = rel(0.95),
        family = fonts$subtitle,
        color = alpha(colors$subtitle, 0.88),
        lineheight = 1.2,
        margin = margin(t = 2, b = 15)
      ),
      plot.caption = element_markdown(
        size = rel(0.7),
        family = "Arial",
        color = colors$caption,
        hjust = 0,
        lineheight = 1.3,
        margin = margin(t = 12, b = 5),
      )
    )
  )
```
#### 7. Save
```{r}
#| label: save
#| warning: false

### |-  plot image ----
save_plot_patchwork(
  plot = combined_plots,
  type = "tidytuesday",
  year = 2025,
  week = 44,
  width  = 12,
  height = 14,
  )
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`tt_2025_44.qmd`](https://github.com/poncest/personal-website/blob/master/data_visualizations/TidyTuesday/2025/tt_2025_44.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
1. **Primary Source:**
- Loux, T., & Gibson, A. K. (2019). Using Flint, Michigan, lead data in introductory statistics. *Teaching Statistics*, *41*(3), 85-88. https://doi.org/10.1111/test.12187
2. **Data Source:**
- TidyTuesday 2025 Week 44: [Lead concentration in Flint water samples in 2015](https://github.com/rfordatascience/tidytuesday/blob/main/data/2025/2025-11-04/readme.md)
3. **Additional Context:**
- Pieper, K. J., Tang, M., & Edwards, M. A. (2017). Flint water crisis caused by interrupted corrosion control: Investigating "ground zero" home. *Environmental Science & Technology*, *51*(4), 2007-2014.
- EPA. (n.d.). [Basic information about lead in drinking water](https://19january2017snapshot.epa.gov/ground-water-and-drinking-water/basic-information-about-lead-drinking-water_.html)
:::
#### 11. Custom Functions Documentation
::: {.callout-note collapse="true"}
##### 📦 Custom Helper Functions
This analysis uses custom functions from my personal module library for efficiency and consistency across projects.
**Functions Used:**
- **`fonts.R`**: `setup_fonts()`, `get_font_families()` - Font management with showtext
- **`social_icons.R`**: `create_social_caption()` - Generates formatted social media captions
- **`image_utils.R`**: `save_plot()` - Consistent plot saving with naming conventions
- **`base_theme.R`**: `create_base_theme()`, `extend_weekly_theme()`, `get_theme_colors()` - Custom ggplot2 themes
**Why custom functions?**\
These utilities standardize theming, fonts, and output across all my data visualizations. The core analysis (data tidying and visualization logic) uses only standard tidyverse packages.
**Source Code:**\
View all custom functions → [GitHub: R/utils](https://github.com/poncest/personal-website/tree/master/R)
:::
